
Microsoft DP-700 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-700
- Exam Name: Microsoft Fabric Data Engineer
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
You are developing a data pipeline named Pipeline1.
You need to add a Copy data activity that will copy data from a Snowflake data source to a Fabric warehouse.
What should you configure?
- A . Degree of copy parallelism
- B . Fault tolerance
- C . Enable staging
- D . Enable logging
C
Explanation:
When using the Copy data activity in a data pipeline to move data from Snowflake to a Fabric warehouse, the process often involves intermediate staging to handle data efficiently, especially for large datasets or cross-cloud data transfers.
Staging involves temporarily storing data in an intermediate location (e.g., Blob storage or Azure Data Lake) before loading it into the target destination.
For cross-cloud data transfers (e.g., from Snowflake to Fabric), enabling staging ensures data is processed and stored temporarily in an efficient format for transfer.
Staging is especially useful when dealing with large datasets, ensuring the process is optimized and avoids memory limitations.
You need to populate the MAR1 data in the bronze layer.
Which two types of activities should you include in the pipeline? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
- A . ForEach
- B . Copy data
- C . WebHook
- D . Stored procedure
A,B
Explanation:
MAR1 has seven entities, each accessible via a different API endpoint. A ForEach activity is required to iterate over these endpoints to fetch data from each one. It enables dynamic execution of API calls for each entity.
The Copy data activity is the primary mechanism to extract data from REST APIs and load it into the bronze layer in Delta format. It supports native connectors for REST APIs and Delta, minimizing development effort.
HOTSPOT
You have an Azure Event Hubs data source that contains weather data.
You ingest the data from the data source by using an eventstream named Eventstream1.
Eventstream1 uses a lakehouse as the destination.
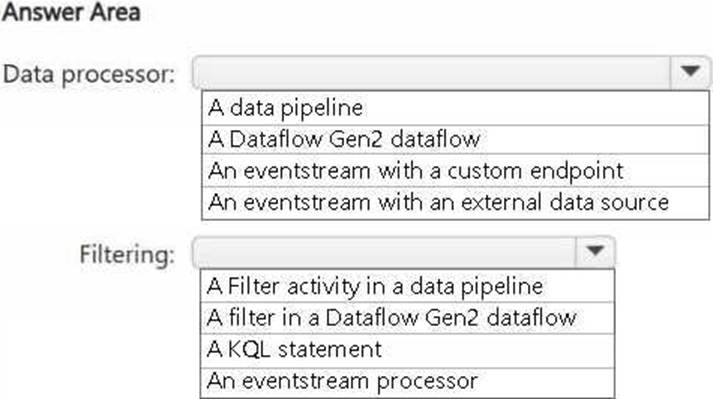
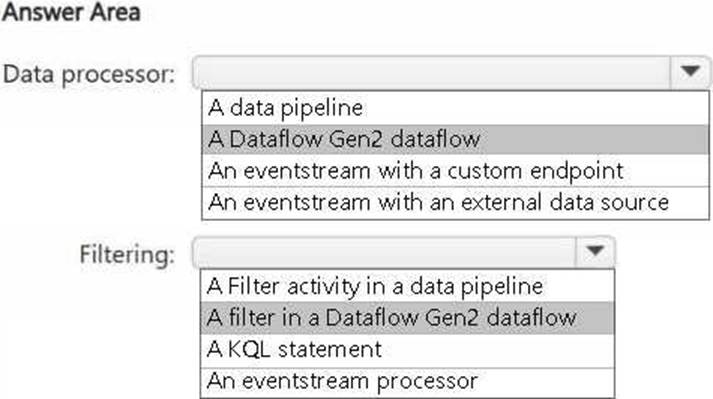
You need to batch ingest only rows from the data source where the City attribute has a value of Kansas. The filter must be added before the destination. The solution must minimize development effort.
What should you use for the data processor and filtering? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
You are implementing a medallion architecture in a Fabric lakehouse.
You plan to create a dimension table that will contain the following columns:
• ID
• CustomerCode
• CustomerName
• CustomerAddress
• CustomerLocation
• ValidFrom
• ValidTo
You need to ensure that the table supports the analysis of historical sales data by customer location at the time of each sale
Which type of slowly changing dimension (SCD) should you use?
- A . Type 2
- B . Type 0
- C . Type 1
- D . Type 3
HOTSPOT
You have a Fabric workspace that contains a warehouse named DW1. DW1 contains the following tables and columns.
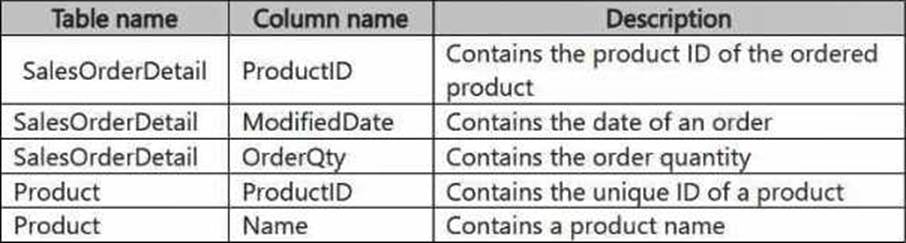
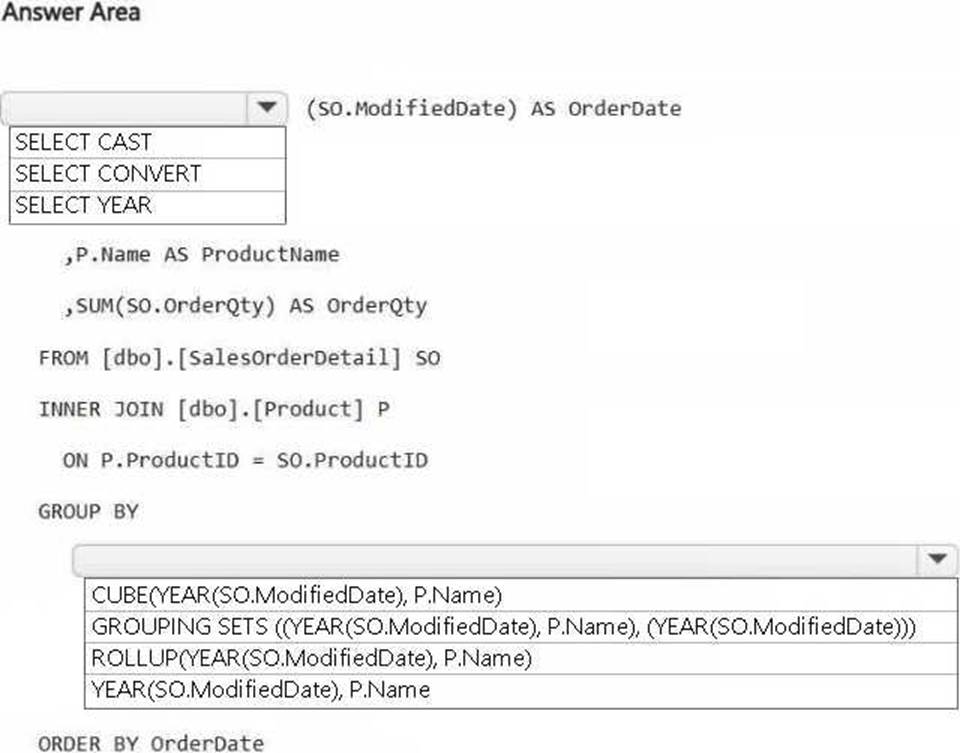
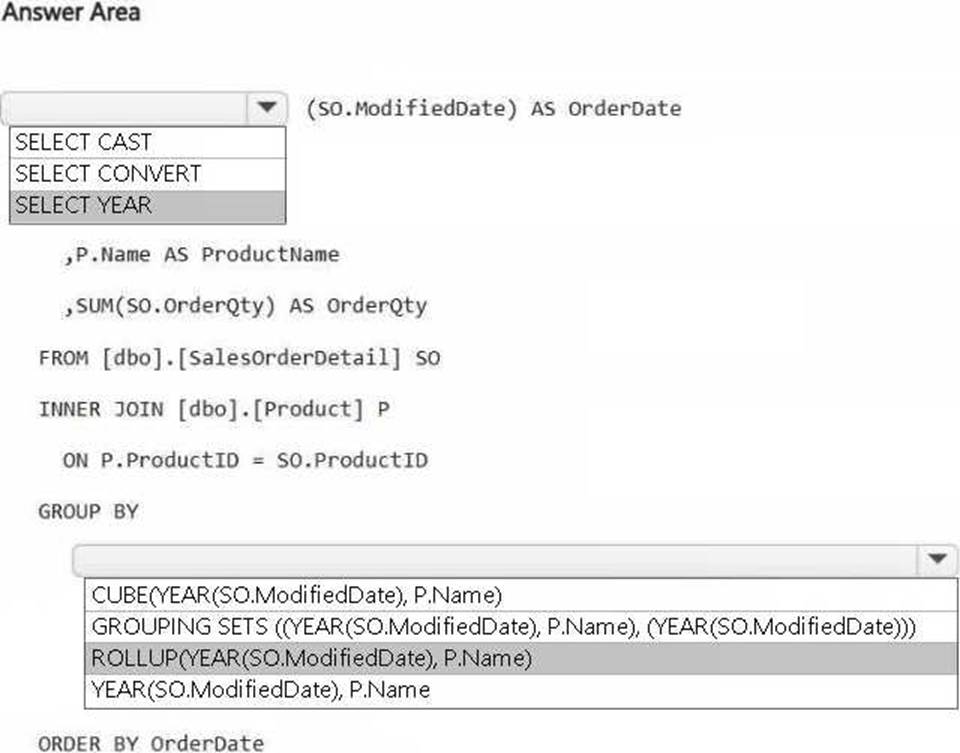
You need to create an output that presents the summarized values of all the order quantities by year and product. The results must include a summary of the order quantities at the year level for all the products.
How should you complete the code? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
HOTSPOT
You have a Fabric workspace that contains a warehouse named Warehouse1. Warehouse! contains a table named Customer.
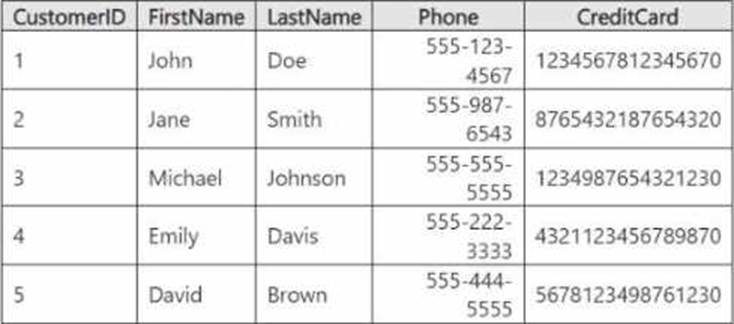
Customer contains the following data.
You have an internal Microsoft Entra user named User1 that has an email address of
[email protected].
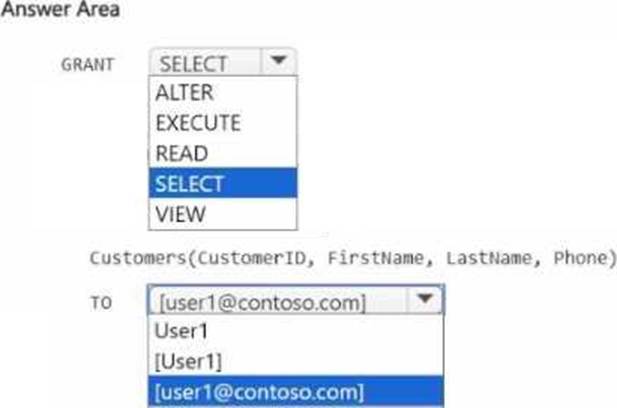
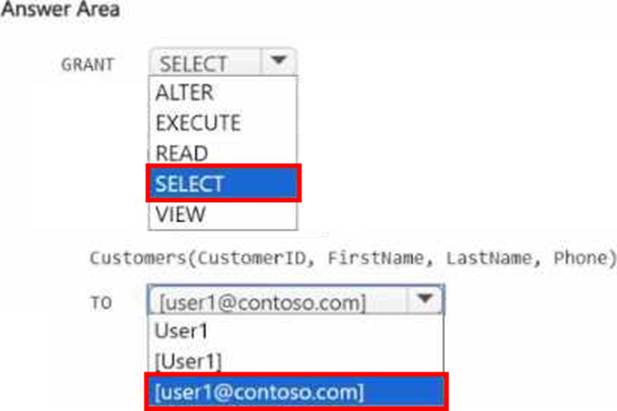
You need to provide User1 with access to the Customer table. The solution must prevent User1 from accessing the CreditCard column.
How should you complete the statement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
You have a Fabric workspace named Workspace1 that contains a warehouse named DW1 and a data pipeline named Pipeline1.
You plan to add a user named User3 to Workspace1.
You need to ensure that User3 can perform the following actions:
View all the items in Workspace1.
Update the tables in DW1.
The solution must follow the principle of least privilege.
You already assigned the appropriate object-level permissions to DW1.
Which workspace role should you assign to User3?
- A . Admin
- B . Member
- C . Viewer
- D . Contributor
D
Explanation:
To ensure User3 can view all items in Workspace1 and update the tables in DW1, the most appropriate workspace role to assign is the Contributor role.
This role allows User3 to:
View all items in Workspace1: The Contributor role provides the ability to view all objects within the workspace, such as data pipelines, warehouses, and other resources.
Update the tables in DW1: The Contributor role allows User3 to modify or update resources within the workspace, including the tables in DW1, assuming that appropriate object-level permissions are set for the warehouse.
This role adheres to the principle of least privilege, as it provides the necessary permissions without granting broader administrative rights.
You have a Fabric notebook named Notebook1 that has been executing successfully for the last week.
During the last run, Notebook1executed nine jobs.
You need to view the jobs in a timeline chart.
What should you use?
- A . Real-Time hub
- B . Monitoring hub
- C . the job history from the application run
- D . Spark History Server
- E . the run series from the details of the application run
E
Explanation:
The run series from the details of the application run is the most detailed and relevant feature for visualizing job execution in a timeline format, making it the correct choice for this scenario. It provides an intuitive way to analyze job execution patterns and improve the efficiency of the notebook.
HOTSPOT
You have a Fabric workspace that contains an eventstream named EventStream1.
You discover that an EventStream1 transformation fails.
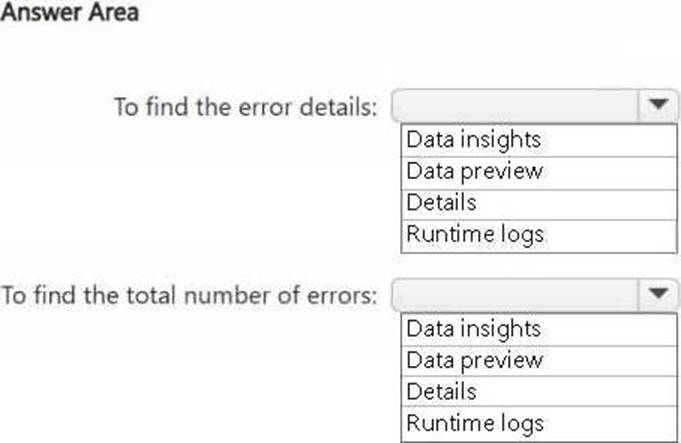
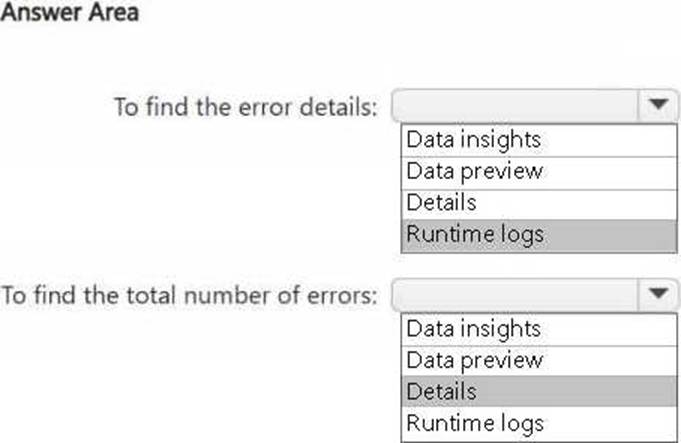
You need to find the following error information:
– The error details, including the occurrence time
– The total number of errors
What should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
HOTSPOT
You are processing streaming data from an external data provider.
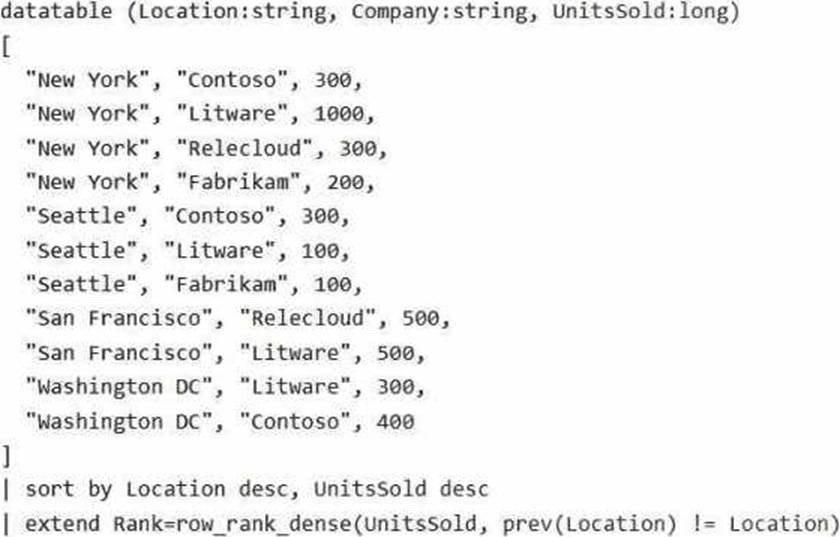
You have the following code segment.
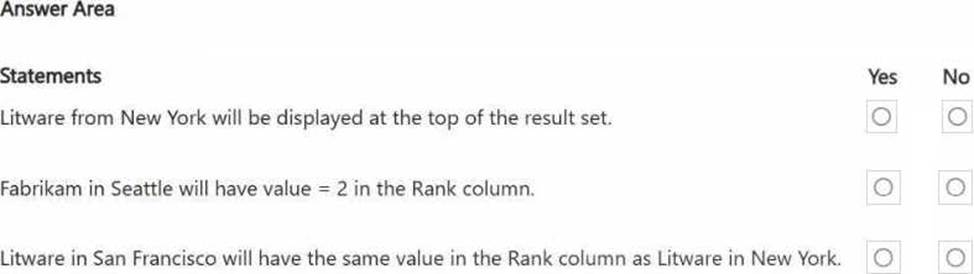
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
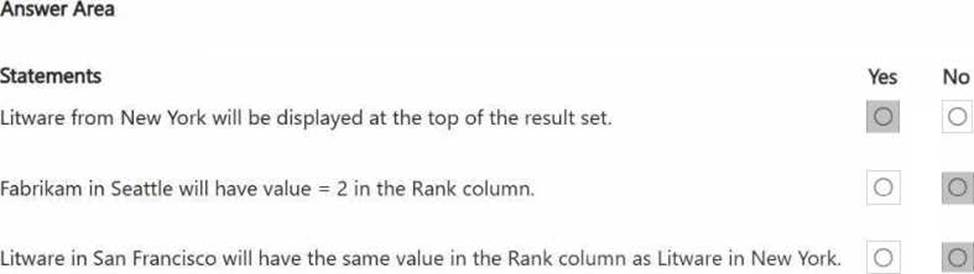
Explanation:
Litware from New York will be displayed at the top of the result set C Yes
The data is sorted first by Location in descending order and then by UnitsSold in descending order.
Since "New York" is alphabetically the last Location, it will appear first in the result set. Within "New York", Litware has the highest UnitsSold (1000), so it will be displayed at the top.
Fabrikam in Seattle will have value = 2 in the Rank column C No
The row_rank_dense function assigns dense ranks based on UnitsSold within each location.
In "Seattle":
– Contoso has UnitsSold = 300 → Rank 1
– Litware has UnitsSold = 100 → Rank 2
– Fabrikam also has UnitsSold = 100, so it shares the same rank (2) as Litware.
Litware in San Francisco will have the same value in the Rank column as Litware in New York C No The rank is calculated separately for each location. In "San Francisco":
– Both Relecloud and Litware have UnitsSold = 500, so they share the same rank (1).
– In "New York", Litware has the highest UnitsSold = 1000 → Rank 1.
Since ranks are calculated independently for each location, Litware in San Francisco does not share the same rank as Litware in New York.