
Microsoft DP-700 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-700
- Exam Name: Microsoft Fabric Data Engineer
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
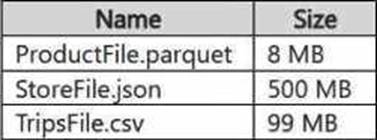
You have a Google Cloud Storage (GCS) container named storage1 that contains the files shown in the following table.
You have a Fabric workspace named Workspace1 that has the cache for shortcuts enabled. Workspace1 contains a lakehouse named Lakehouse1.
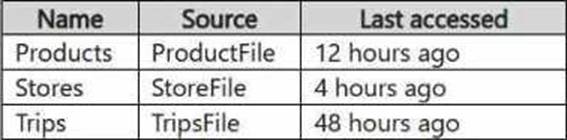
Lakehouse1 has the shortcuts shown in the following table.
You need to read data from all the shortcuts.
Which shortcuts will retrieve data from the cache?
- A . Stores only
- B . Products only
- C . Stores and Products only
- D . Products, Stores, and Trips
- E . Trips only
- F . Products and Trips only
C
Explanation:
When reading data from shortcuts in Fabric (in this case, from a lakehouse like Lakehouse1), the cache for shortcuts helps by storing the data locally for quick access. The last accessed timestamp and the cache expiration rules determine whether data is fetched from the cache or from the source (Google Cloud Storage, in this case).
Products: The ProductFile.parquet was last accessed 12 hours ago. Since the cache has data available for up to 12 hours, it is likely that this data will be retrieved from the cache, as it hasn’t been too long since it was last accessed.
Stores: The StoreFile.json was last accessed 4 hours ago, which is within the cache retention period.
Therefore, this data will also be retrieved from the cache.
Trips: The TripsFile.csv was last accessed 48 hours ago. Given that it’s outside the typical caching window (assuming the cache has a maximum retention period of around 24 hours), it would not be retrieved from the cache. Instead, it will likely require a fresh read from the source.
HOTSPOT
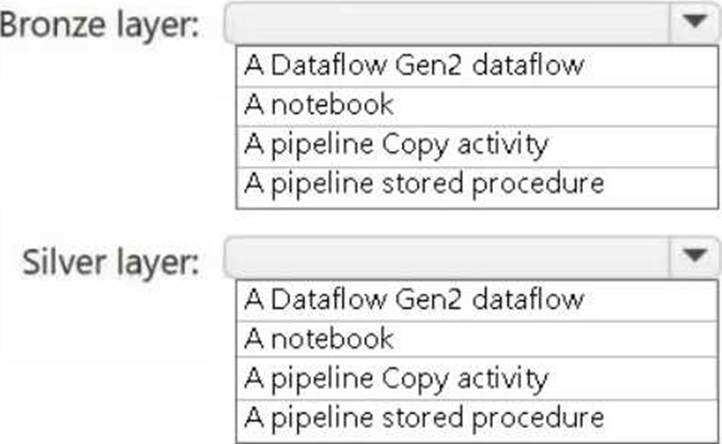
You need to recommend a method to populate the POS1 data to the lakehouse medallion layers.
What should you recommend for each layer? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Explanation:
A screenshot of a computer Description automatically generated
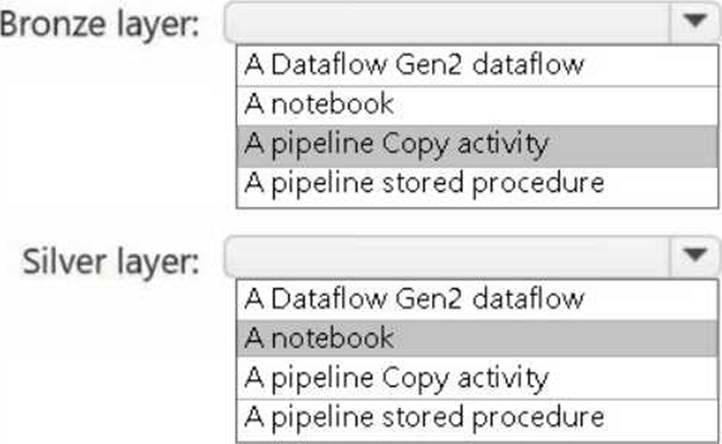
Bronze Layer: A pipeline Copy activity
The bronze layer is used to store raw, unprocessed data. The requirements specify that no transformations should be applied before landing the data in this layer. Using a pipeline Copy activity ensures minimal development effort, built-in connectors, and the ability to ingest the data directly into the Delta format in the bronze layer.
Silver Layer: A notebook
The silver layer involves extensive data cleansing (deduplication, handling missing values, and standardizing capitalization). A notebook provides the flexibility to implement complex transformations and is well-suited for this task.
You have a Fabric workspace that contains an eventhouse and a KQL database named Database1.
Database1 has the following:
– A table named Table1
– A table named Table2
– An update policy named Policy1
Policy1 sends data from Table1 to Table2.
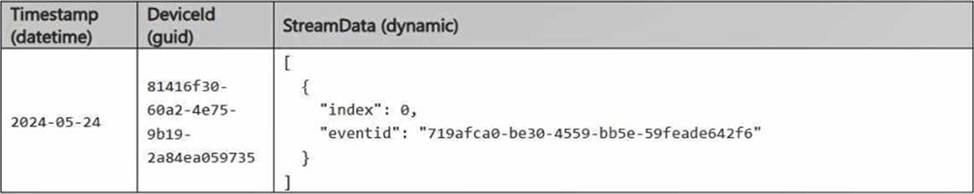
The following is a sample of the data in Table2.
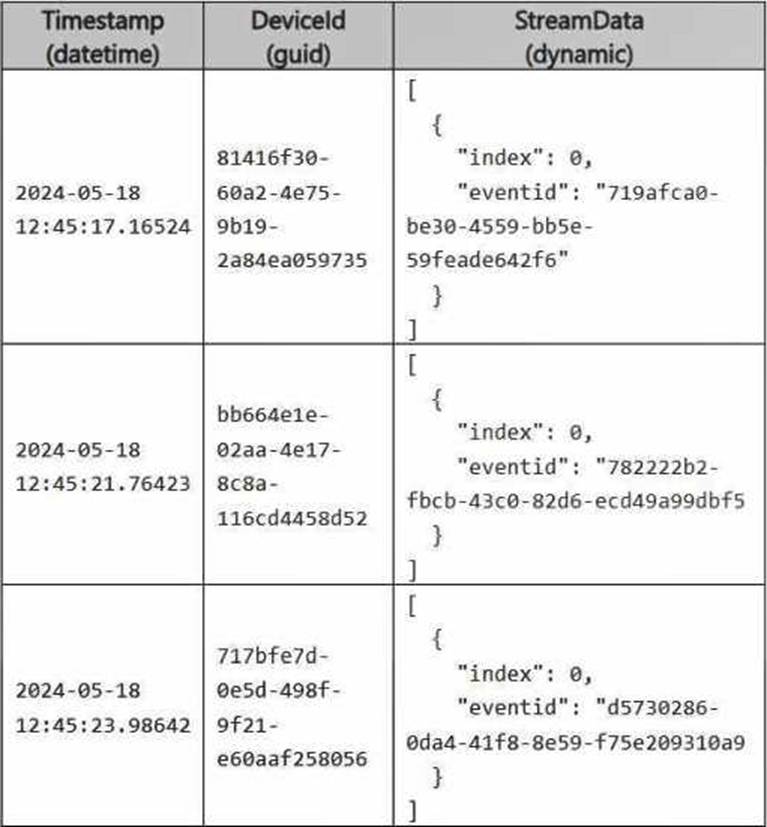
Recently, the following actions were performed on Table1:
– An additional element named temperature was added to the StreamData column.
– The data type of the Timestamp column was changed to date.
– The data type of the DeviceId column was changed to string.
You plan to load additional records to Table2.
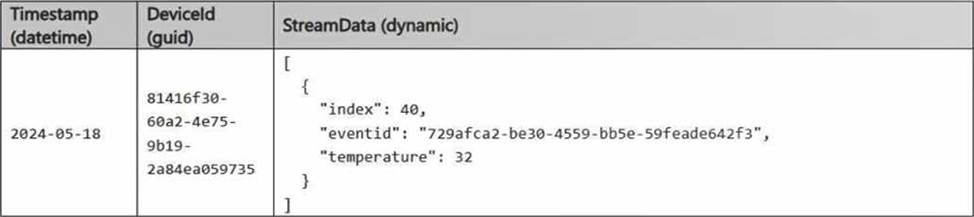
Which two records will load from Table1 to Table2? Each correct answer presents a complete solution. NOTE: Each correct selection is worth one point.
A)
B)
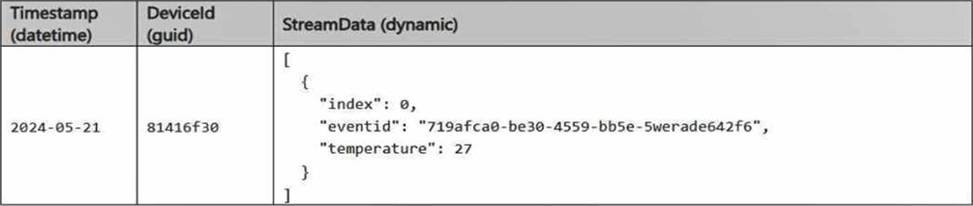
C)
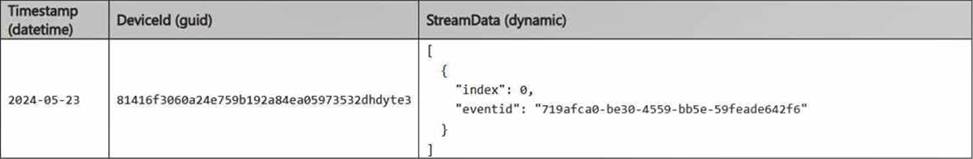
D)
- A . Option A
- B . Option B
- C . Option c
- D . Option D
B,D
Explanation:
Changes to Table1 Structure:
– StreamData column: An additional temperature element was added.
– Timestamp column: Data type changed from datetime to date.
– DeviceId column: Data type changed from guid to string.
Impact of Changes:
– Only records that comply with Table2’s structure will load.
– Records that deviate from Table2’s column data types or structure will be rejected.
Record B:
– Timestamp: Matches Table2 (datetime format).
– eviceId: Matches Table2 (guid format).
– StreamData: Contains only the index and eventid, which matches Table2.
Accepted because it fully matches Table2’s structure and data types.
Record D:
– Timestamp: Matches Table2 (datetime format).
– DeviceId: Matches Table2 (guid format).
– StreamData: Matches Table2’s structure.
Accepted because it fully matches Table2’s structure and data types.
DRAG DROP
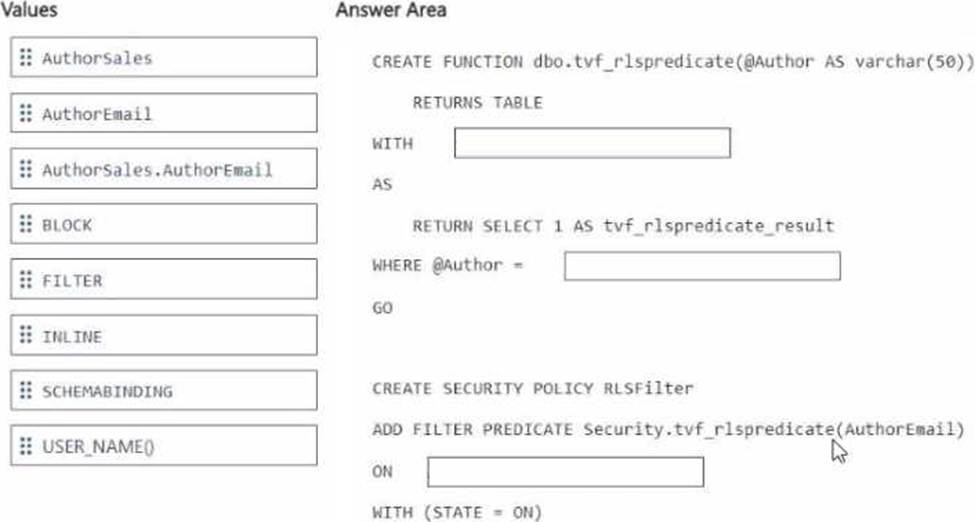
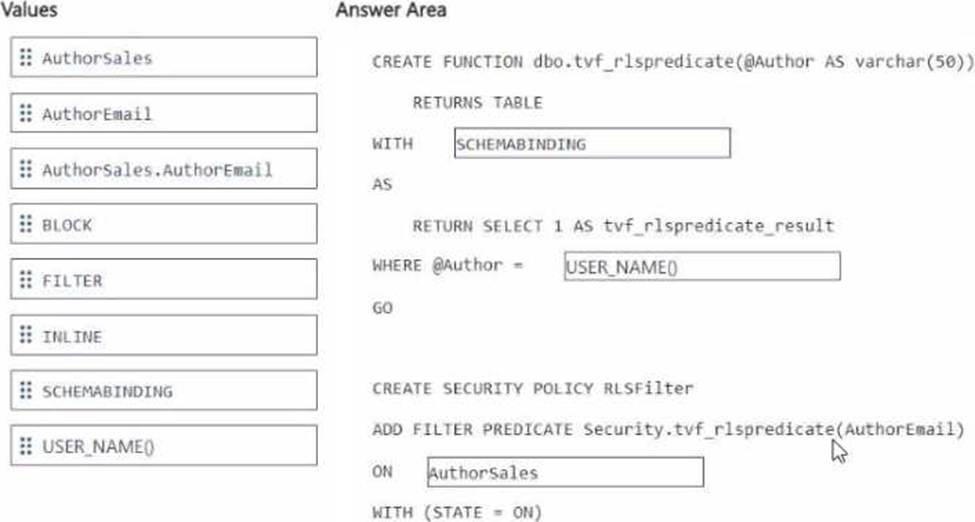
You need to ensure that the authors can see only their respective sales data.
How should you complete the statement? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.
You have an Azure key vault named KeyVaultl that contains secrets.
You have a Fabric workspace named Workspace!. Workspace! contains a notebook named Notebookl that performs the following tasks:
• Loads stage data to the target tables in a lakehouse
• Triggers the refresh of a semantic model
You plan to add functionality to Notebookl that will use the Fabric API to monitor the semantic model refreshes. You need to retrieve the registered application ID and secret from KeyVaultl to generate the authentication token. Solution: You use the following code segment:
Use notebookutils. credentials.getSecret and specify key vault URL and the name of a linked service.
Does this meet the goal?
- A . Yes
- B . No
You have an Azure key vault named KeyVaultl that contains secrets.
You have a Fabric workspace named Workspace!. Workspace! contains a notebook named Notebookl that performs the following tasks:
• Loads stage data to the target tables in a lakehouse
• Triggers the refresh of a semantic model
You plan to add functionality to Notebookl that will use the Fabric API to monitor the semantic model refreshes. You need to retrieve the registered application ID and secret from KeyVaultl to generate the authentication token. Solution: You use the following code segment:
Use notebookutils. credentials.getSecret and specify key vault URL and the name of a linked service.
Does this meet the goal?
- A . Yes
- B . No
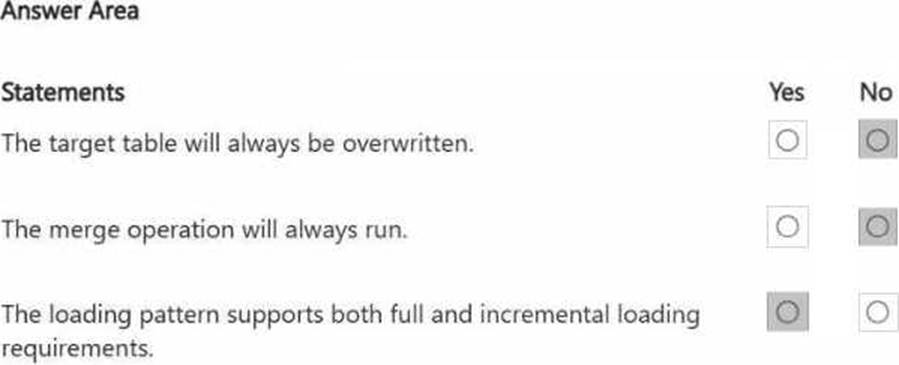
HOTSPOT
You are building a data loading pattern for Fabric notebook workloads.
You have the following code segment:
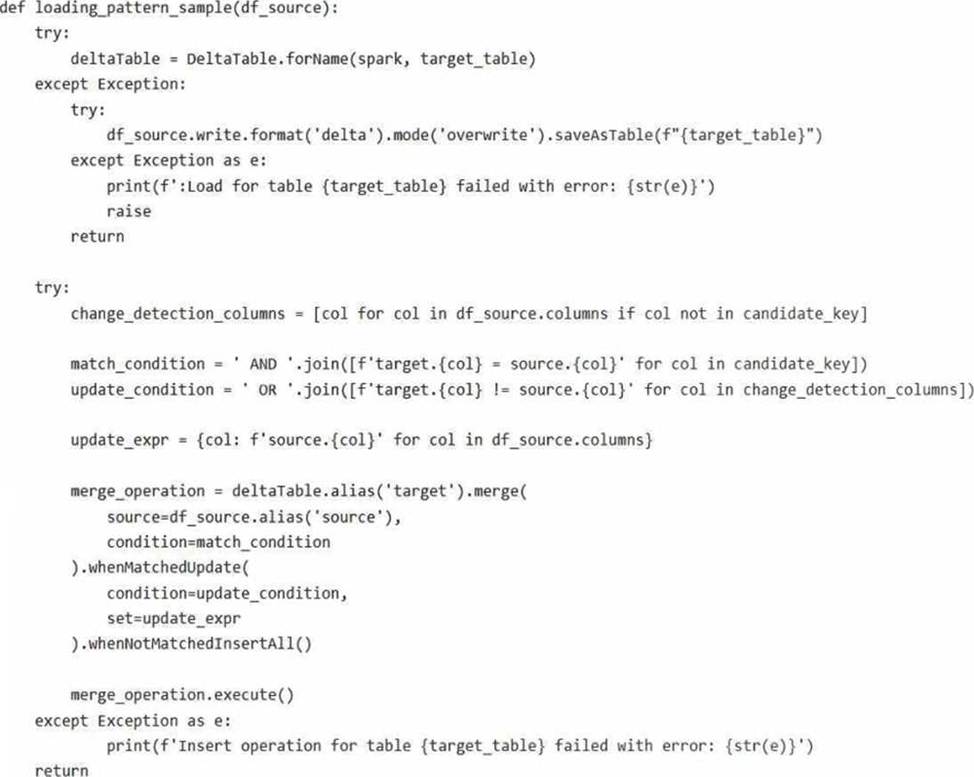
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
You have a Fabric workspace that contains a lakehouse named Lakehouse1. Lakehouse1 contains a
Delta table named Table1.
You analyze Table1 and discover that Table1 contains 2,000 Parquet files of 1 MB each.
You need to minimize how long it takes to query Table1.
What should you do?
- A . Disable V-Order and run the OPTIMIZE command.
- B . Disable V-Order and run the VACUUM command.
- C . Run the OPTIMIZE and VACUUM commands.
C
Explanation:
Problem Overview:
Table1 has 2,000 small Parquet files (1 MB each).
Query performance suffers when the table contains numerous small files because the query engine must process each file individually, leading to significant overhead.
Solution:
To improve performance, file compaction is necessary to reduce the number of small files and create larger, optimized files.
Commands and Their Roles:
OPTIMIZE Command:
– Compacts small Parquet files into larger files to improve query performance.
– It supports optional features like V-Order, which organizes data for efficient scanning. VACUUM Command:
– Removes old, unreferenced data files and metadata from the Delta table.
– Running VACUUM after OPTIMIZE ensures unnecessary files are cleaned up, reducing storage overhead and improving performance.
HOTSPOT
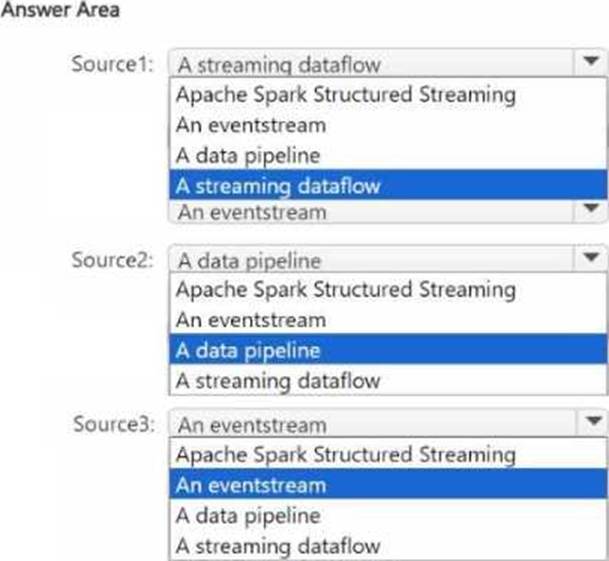
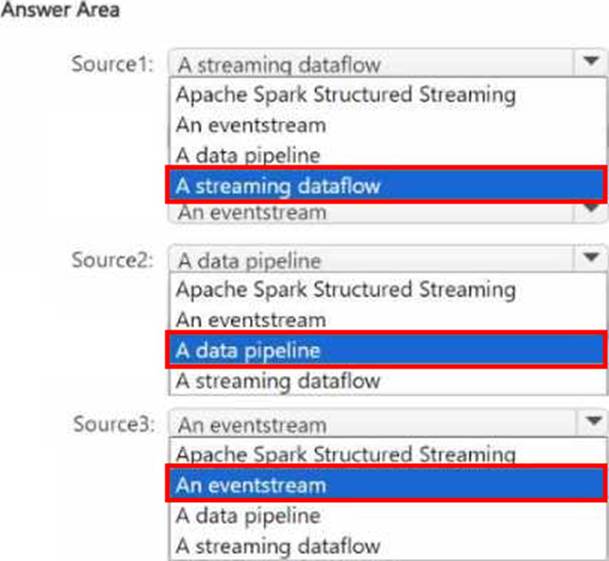
You need to recommend a Fabric streaming solution that will use the sources shown in the following table.
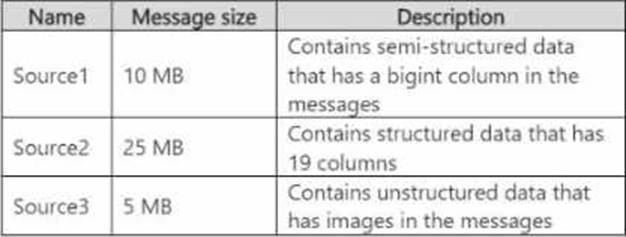
The solution must minimize development effort.
What should you include in the recommendation for each source? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Topic 2, Litware, Inc
Case Study
Overview
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide. Litware also manages an online advertising business for the authors it represents.
Existing Environment. Fabric Environment
Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
The company has a data engineering team that uses Python for data processing.
Existing Environment. Data Processing
The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse. Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
Litware has image files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
Existing Environment. Sales Data
Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
In the source system, the sales data refreshes every six hours starting at midnight each day.
The sales data is captured in a Dataflow Gen1 dataflow. When the dataflow runs, new and historical data is captured.
The dataflow captures the following fields of the source:
– Sales Date
– Author
– Price
– Units
– SKU
A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
Existing Environment. Security Groups
Litware has the following security groups:
– Sales
– Fabric Admins
– Streaming Admins
Existing Environment. Performance Issues
Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: “The SQL query failed while running.”
The data engineering team wants to debug the issue and find queries that cause more than one failure.
When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
The company’s sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
Requirements. Planned Changes
Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
Requirements. Version Control
Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
Requirements. Governance Requirements
To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
Requirements. Data Requirements
Litware identifies the following data requirements:
– Process the SEO data in near-real-time (NRT).
– Make the book reviews available in the lakehouse without making a copy of the data.
– When a new book cover image arrives in the Files folder, process the image as soon as possible.
You need to implement the solution for the book reviews.
Which should you do?
- A . Create a Dataflow Gen2 dataflow.
- B . Create a shortcut.
- C . Enable external data sharing.
- D . Create a data pipeline.
B
Explanation:
The requirement specifies that Litware plans to make the book reviews available in the lakehouse without making a copy of the data. In this case, creating a shortcut in Fabric is the most appropriate solution. A shortcut is a reference to the external data, and it allows Litware to access the book reviews stored in Amazon S3 without duplicating the data into the lakehouse.