
Splunk SPLK-2003 Practice Exams
Last updated on Oct 07,2026- Exam Code: SPLK-2003
- Exam Name: Splunk SOAR Certified Automation Developer Exam
- Certification Provider: Splunk
- Latest update: Oct 07,2026
The SOAR server has been configured to use an external Splunk search head for search and searching on SOAR works; however, the search results don’t include content that was being returned by search before configuring external search.
Which of the following could be the problem?
- A . The existing content indexes on the SOAR server need to be re-indexed to migrate them to Splunk.
- B . The user configured on the SOAR side with Phantomsearch capability is not enabled on Splunk.
- C . The remote Splunk search head is currently offline.
- D . Content that existed before configuring external search must be backed up on SOAR and restored on the Splunk search head.
B
Explanation:
If, after configuring an external Splunk search head for search in SOAR, the search results do not include content that was previously returned, one possible issue could be that the user account configured on the SOAR side does not have the required permissions (such as the ‘phantomsearch’ capability) enabled on the Splunk side. This capability is necessary for the SOAR server to execute searches and retrieve results from the Splunk search head.
Which of the following applies to filter blocks?
- A . Can select which blocks have access to container data.
- B . Can select assets by tenant, approver, or app.
- C . Can be used to select data for use by other blocks.
- D . Can select containers by seventy or status.
C
Explanation:
The correct answer is C because filter blocks can be used to select data for use by other blocks. Filter blocks can filter data from the container, artifacts, or custom lists based on various criteria, such as field name, value, operator, etc. Filter blocks can also join data from multiple sources using the join action. The output of the filter block can be used as input for other blocks, such as decision, format, prompt, etc. See Splunk SOAR Documentation for more details.
Filter blocks within Splunk SOAR playbooks are designed to sift through data and select specific pieces of information based on defined criteria. These blocks are crucial for narrowing down the data that subsequent blocks in a playbook will act upon. By applying filters, a playbook can focus on relevant data, thereby enhancing efficiency and ensuring that actions are taken based on precise, contextually relevant information. This capability is essential for tailoring the playbook’s actions to the specific needs of the incident or workflow, enabling more targeted and effective automation strategies. Filters do not directly select blocks for container data access, choose assets by various administrative criteria, or select containers by attributes like severity or status; their primary function is to refine data within the playbook’s operational context.
A user wants to get the playbook results for a single artifact.
Which steps will accomplish the?
- A . Use the contextual menu from the artifact and select run playbook.
- B . Use the run playbook dialog and set the scope to the artifact.
- C . Create a new container including Just the artifact in question.
- D . Use the contextual menu from the artifact and select the actions.
A
Explanation:
To get playbook results for a single artifact, a user can utilize the contextual menu option directly from the artifact itself. This method allows for targeted execution of a playbook on just that artifact, facilitating a focused analysis or action based on the data within that specific artifact. This approach is particularly useful when a user needs to drill down into the details of an individual piece of evidence or data point within a larger incident or case, allowing for granular control and execution of playbooks in the Splunk SOAR environment.
Two action blocks, geolocate_ip 1 and file_reputation_2, are connected to a decision block.
Which of the following is a correct configuration for making a decision on the action results from one of the given blocks?
A)
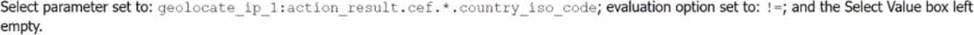
B)
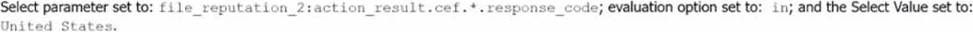
C)
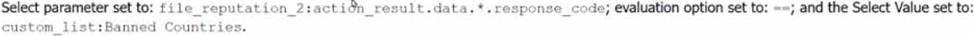
D)
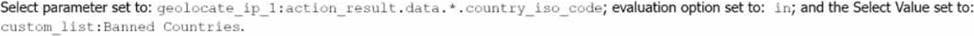
- A . Option A
- B . Option B
- C . Option C
- D . Option D
A
Explanation:
In the given decision block, you are trying to evaluate the results of two action blocks:
geolocate_ip_1 and file_reputation_2. The correct configuration for making a decision based on the result of geolocate_ip_1 is by checking the country_iso_code field from the action result and setting the evaluation option to != (not equal), with no specific value provided in the "Select Value" box. This essentially checks whether a valid country ISO code exists in the action result and proceeds if it’s not empty or different from a specific value. This is a common check when working with geolocation results to see if a response has been returned.
Other options (B, C, and D) include response codes or list comparisons, which do not align with the decision structure mentioned, which needs to operate based on a country_iso_code field.
Reference: Splunk SOAR Playbook Development Guide.
Splunk SOAR Documentation on Decision Blocks and Action Result Evaluation.
An active playbook can be configured to operate on all containers that share which attribute?
- A . Artifact
- B . Label
- C . Tag
- D . Severity
B
Explanation:
The correct answer is B because an active playbook can be configured to operate on all containers that share a label. A label is a user-defined attribute that can be applied to containers to group them by a common characteristic, such as source, type, severity, etc. Labels can be used to filter containers and trigger active playbooks based on the label value. See Splunk SOAR Documentation for more details.
In Splunk SOAR, labels are used to categorize containers (such as incidents or events) based on their characteristics or the type of security issue they represent. An active playbook can be configured to trigger on all containers that share a specific label, enabling targeted automation based on the nature of the incident. This functionality allows for efficient and relevant playbook execution, ensuring that the automated response is tailored to the specific requirements of the container’s category. Labels serve as a powerful organizational tool within SOAR, guiding the automated response framework to act on incidents that meet predefined criteria, thus streamlining the security operations process.
Configuring Phantom search to use an external Splunk server provides which of the following benefits?
- A . The ability to run more complex reports on Phantom activities.
- B . The ability to ingest Splunk notable events into Phantom.
- C . The ability to automate Splunk searches within Phantom.
- D . The ability to display results as Splunk dashboards within Phantom.
C
Explanation:
The correct answer is C because configuring Phantom search to use an external Splunk server allows you to automate Splunk searches within Phantom using the run query action. This action can be used to run any Splunk search command on the external Splunk server and return the results to Phantom. You can also use the format results action to parse the results and use them in other blocks. See Splunk SOAR Documentation for more details.
Configuring Phantom (now known as Splunk SOAR) to use an external Splunk server enhances the automation capabilities within Phantom by allowing the execution of Splunk searches as part of the automation and orchestration processes. This integration facilitates the automation of tasks that involve querying data from Splunk, thereby streamlining security operations and incident response workflows. Splunk SOAR’s ability to integrate with over 300 third-party tools, including Splunk, supports a wide range of automatable actions, thus enabling a more efficient and effective security operations center (SOC) by reducing the time to respond to threats and by making repetitive tasks more manageable
https://www.splunk.com/en_us/products/splunk-security-orchestration-and-automation-features.html
Which of the following are the default ports that must be configured on Splunk to allow connections from SOAR?
- A . SplunkWeb (8088), SplunkD (8089), HTTP Collector (8000)
- B . SplunkWeb (8089), SplunkD (8088), HTTP Collector (8000)
- C . SplunkWeb (8000), SplunkD (8089), HTTP Collector (8088)
- D . SplunkWeb (8469), SplunkD (8702), HTTP Collector (8864)
C
Explanation:
For Splunk SOAR to connect with Splunk Enterprise, certain default ports must be configured to facilitate communication between the two platforms. Typically, SplunkWeb, which serves the Splunk Enterprise web interface, uses port 8000. SplunkD, the Splunk daemon that handles most of the back-end services, listens on port 8089. The HTTP Event Collector (HEC), which allows HTTP clients to send data to Splunk, typically uses port 8088. These ports are essential for the integration, allowing SOAR to send data to Splunk for indexing, searching, and visualization. Options A, B, and D list incorrect port configurations for this purpose, making option C the correct answer based on standard Splunk configurations.
These are the default ports used by Splunk SOAR (On-premises) to communicate with the embedded
Splunk Enterprise instance. SplunkWeb is the web interface for Splunk Enterprise, SplunkD is the management port for Splunk Enterprise, and HTTP Collector is the port for receiving data from HTTP Event Collector (HEC). The other options are either incorrect or not default ports. For example, option B has the SplunkWeb and SplunkD ports reversed, and option D has arbitrary port numbers that are not used by Splunk by default.
What is the default embedded search engine used by SOAR?
- A . Embedded Splunk search engine.
- B . Embedded SOAR search engine.
- C . Embedded Django search engine.
- D . Embedded Elastic search engine.
B
Explanation:
the default embedded search engine used by SOAR is the SOAR search engine, which is powered by
the PostgreSQL database built-in to Splunk SOAR (Cloud). A Splunk SOAR (Cloud) Administrator can configure options for search from the Home menu, in Search Settings under Administration Settings. The SOAR search engine has been modified to accept the * wildcard and supports various operators and filters. For search syntax and examples, see Search within Splunk SOAR (Cloud)2.
Option A is incorrect, because the embedded Splunk search engine was used in earlier releases of Splunk SOAR (Cloud), but not in the current version.
Option C is incorrect, because Django is a web framework, not a search engine.
Option D is incorrect, because Elastic is a separate search engine that is not embedded in Splunk SOAR (Cloud).
1: Configure search in Splunk SOAR (Cloud) 2: Search within Splunk SOAR (Cloud)
Splunk SOAR utilizes its own embedded search engine by default, which is tailored to its security orchestration and automation framework. While Splunk SOAR can integrate with other search engines, like the Embedded Splunk search engine, for advanced capabilities and log analytics, its default setup comes with an embedded search engine optimized for the typical data and search patterns encountered within the SOAR platform.
Which app allows a user to send Splunk Enterprise Security notable events to Phantom?
- A . Any of the integrated Splunk/Phantom Apps
- B . Splunk App for Phantom Reporting.
- C . Splunk App for Phantom.
- D . Phantom App for Splunk.
C
Explanation:
The Splunk App for Phantom is designed to facilitate the integration between Splunk Enterprise Security and Splunk SOAR (Phantom), enabling the seamless forwarding of notable events from Splunk to Phantom. This app allows users to leverage the analytical and data processing capabilities of Splunk ES and utilize Phantom for automated orchestration and response. The app typically includes mechanisms for specifying which notable events to send to Phantom, formatting the data appropriately, and ensuring secure communication between the two platforms. This integration is crucial for organizations looking to combine the strengths of Splunk’s SIEM capabilities with Phantom’s automation and orchestration features to enhance their security operations.
Which of the following can be configured in the ROI Settings?
- A . Number of full time employees (FTEs).
- B . Time lost.
- C . Analyst hours per month.
- D . Annual analyst salary.
C
Explanation:
ROI Settings dashboard allows you to configure the parameters used to estimate the data displayed in the Automation ROI Summary dashboard. One of the settings that can be configured is the FTE Gained, which is the number of full time employees (FTEs) that are freed up by automation. To calculate this value, Splunk SOAR divides the number of actions run by automation by the number of expected actions an analyst would take, based on minutes per action and analyst hours per day. Therefore, option A is the correct answer, as it is one of the settings that can be configured in the ROI Settings dashboard.
Option B is incorrect, because time lost is not a setting that can be configured in the ROI Settings dashboard, but a metric that is calculated by Splunk SOAR based on the difference between the analyst minutes per action and the actual minutes per action.
Option C is incorrect, because analyst hours per month is not a setting that can be configured in the ROI Settings dashboard, but a value that is derived from the analyst hours per day setting.
Option D is incorrect, because annual analyst salary is a setting that can be configured in the ROI Settings dashboard, but not the one that is asked in the question.
1: Configure the ROI Settings dashboard in Administer Splunk SOAR (On-premises)
ROI (Return on Investment) Settings within Splunk SOAR are used to estimate the efficiency and financial impact of the SOAR platform. One of the configurable parameters in these settings is the ‘Analyst hours per month’. This parameter helps in calculating the time saved through automation, which in turn can be translated into cost savings and efficiency gains. It reflects the direct contribution of the SOAR platform to operational productivity.