
Microsoft DP-203 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-203
- Exam Name: Data Engineering on Microsoft Azure
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
HOTSPOT
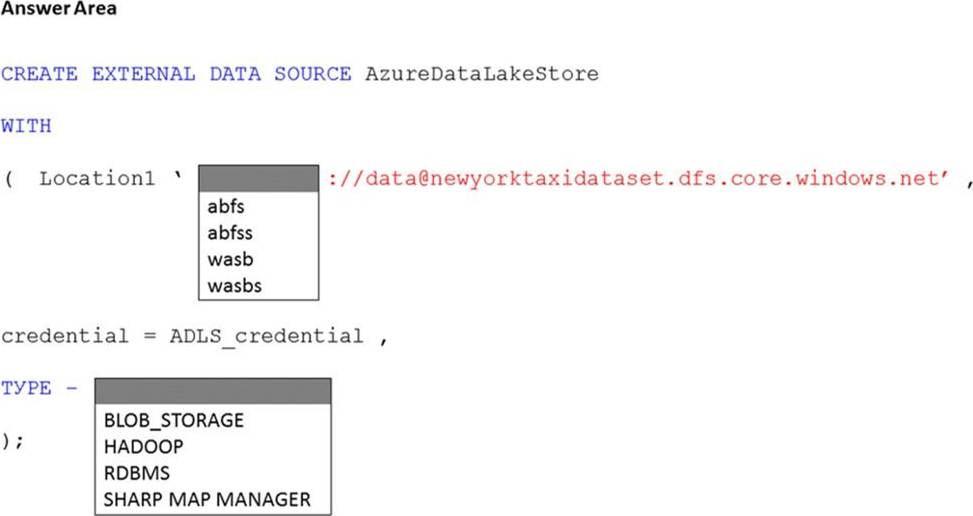
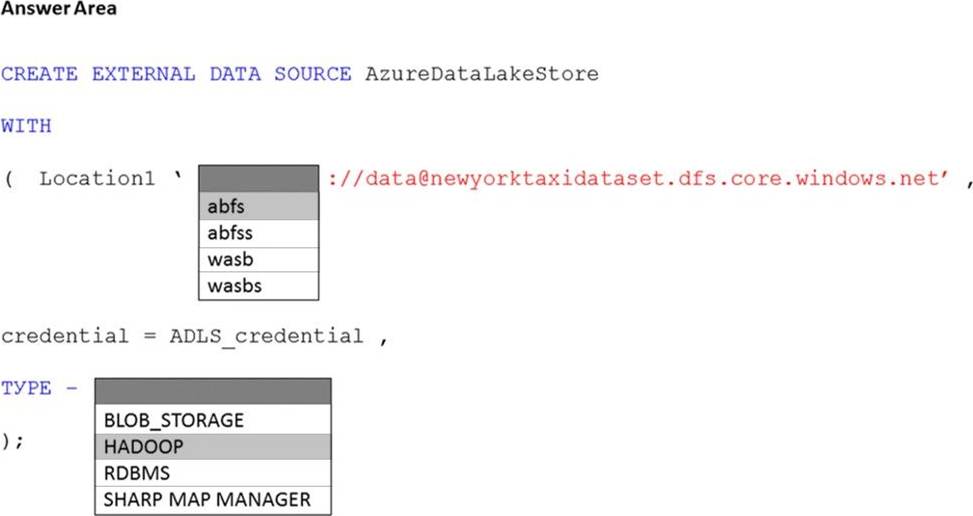
You have an Azure subscription that contains an Azure Synapse Analytics dedicated SQL pool named Pool1 and an Azure Data Lake Storage account named storage1. Storage1 requires secure transfers.
You need to create an external data source in Pool1 that will be used to read .orc files in storage1.
How should you complete the code? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
You have two fact tables named Flight and Weather. Queries targeting the tables will be based on the join between the following columns.
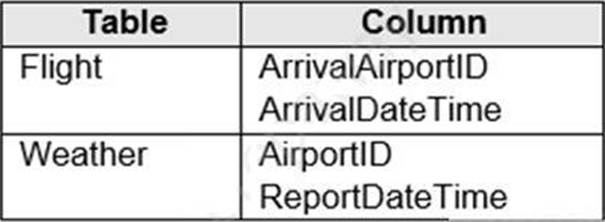
You need to recommend a solution that maximizes query performance.
What should you include in the recommendation?
- A . In the tables use a hash distribution of ArrivalDateTime and ReportDateTime.
- B . In the tables use a hash distribution of ArrivaIAirportID and AirportlD.
- C . In each table, create an identity column.
- D . In each table, create a column as a composite of the other two columns in the table.
HOTSPOT
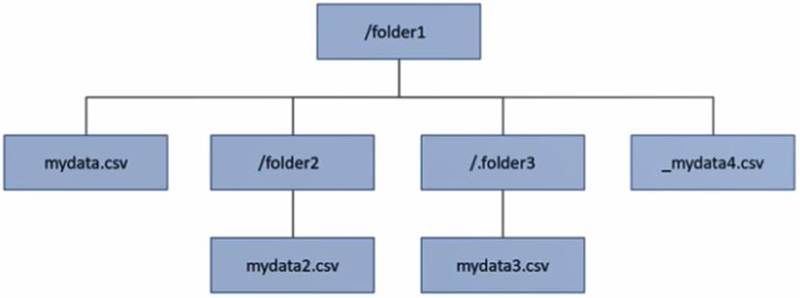
You have an Azure Data Lake Storage Gen2 account that contains a container named container1. You have an Azure Synapse Analytics serverless SQL pool that contains a native external table named dbo.Table1. The source data for dbo.Table1 is stored in container1.
The folder structure of container1 is shown in the following exhibit.
The external data source is defined by using the following statement.
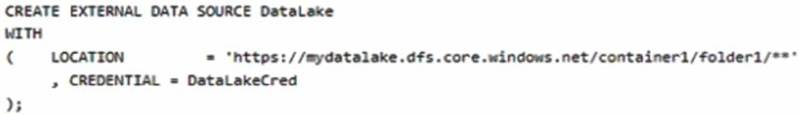
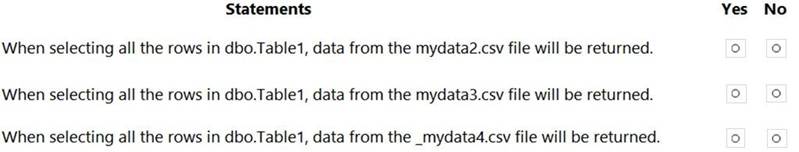
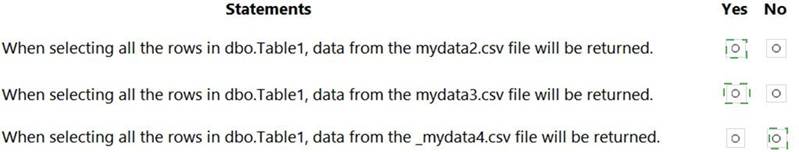
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
You have several Azure Data Factory pipelines that contain a mix of the following types of activities.
* Wrangling data flow
* Notebook
* Copy
* jar
Which two Azure services should you use to debug the activities? Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
- A . Azure HDInsight
- B . Azure Databricks
- C . Azure Machine Learning
- D . Azure Data Factory
- E . Azure Synapse Analytics
You have an Azure subscription that contains an Azure data factory named ADF1.
From Azure Data Factory Studio, you build a complex data pipeline in ADF1.
You discover that the Save button is unavailable and there are validation errors that prevent the pipeline from being published.
You need to ensure that you can save the logic of the pipeline.
Solution: You export ADF1 as an Azure Resource Manager (ARM) template.
- A . Yes
- B . No
You have an Azure subscription that contains an Azure Synapse Analytics account. The account is integrated with an Azure Repos repository named Repo1 and contains a pipeline named Pipeline1.
Repo1 contains the branches shown in the following table.
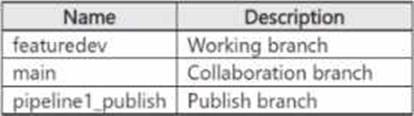
From featuredev, you develop and test changes to Pipeline1. You need to publish the changes.
What should you do first?
- A . From featuredev. create a pull request.
- B . From main, create a pull request.
- C . Add a Publish_config.json file to the root folder of the collaboration branch.
- D . Switch to live mode.
You have an Azure Blob storage account named storage! and an Azure Synapse Analytics serverless SQL pool named Pool! From Pool1., you plan to run ad-hoc queries that target storage!
You need to ensure that you can use shared access signature (SAS) authorization without defining a data source.
What should you create first?
- A . a stored access policy
- B . a server-level credential
- C . a managed identity
- D . a database scoped credential
You have an Azure Synapse Analytics dedicated SQL pool that contains a table named Table1.
You have files that are ingested and loaded into an Azure Data Lake Storage Gen2 container named container1.
You plan to insert data from the files into Table1 and azure Data Lake Storage Gen2 container named container1.
You plan to insert data from the files into Table1 and transform the data. Each row of data in the files will produce one row in the serving layer of Table1.
You need to ensure that when the source data files are loaded to container1, the DateTime is stored as an additional column in Table1.
Solution: In an Azure Synapse Analytics pipeline, you use a data flow that contains a Derived Column transformation.
- A . Yes
- B . No
You are designing a data mart for the human resources (MR) department at your company. The data mart will contain information and employee transactions.
From a source system you have a flat extract that has the following fields:
• EmployeeID
• FirstName
• LastName
• Recipient
• GrossArnount
• TransactionID
• GovernmentID
• NetAmountPaid
• TransactionDate
You need to design a start schema data model in an Azure Synapse analytics dedicated SQL pool for the data mart.
Which two tables should you create? Each Correct answer present part of the solution.
- A . a dimension table for employee
- B . a fabric for Employee
- C . a dimension table far EmployeeTransaction
- D . a dimension table for Transaction
- E . a fact table for Transaction
You have an Azure Synapse Analytics dedicated SQL pool named Pcol1. Pool1 contains a table named tablet
You load 5 TB of data into table1.
You need to ensure that column store compression is maximized for table1.
Which statement should you execute?
- A . ALTER INDEX ALL on table REBUILD
- B . DBCC DBREINOEX (table)
- C . DBCC IIDEXDEFRAG (pool1, table1)
- D . ALTER INDEX ALL on table REORGANIZE