Microsoft DP-203 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-203
- Exam Name: Data Engineering on Microsoft Azure
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure Data Lake Storage account that contains a staging zone.
You need to design a daily process to ingest incremental data from the staging zone, transform the data by executing an R script, and then insert the transformed data into a data warehouse in Azure Synapse Analytics.
Solution: You schedule an Azure Databricks job that executes an R notebook, and then inserts the data into the data warehouse.
Does this meet the goal?
- A . Yes
- B . No
DRAG DROP
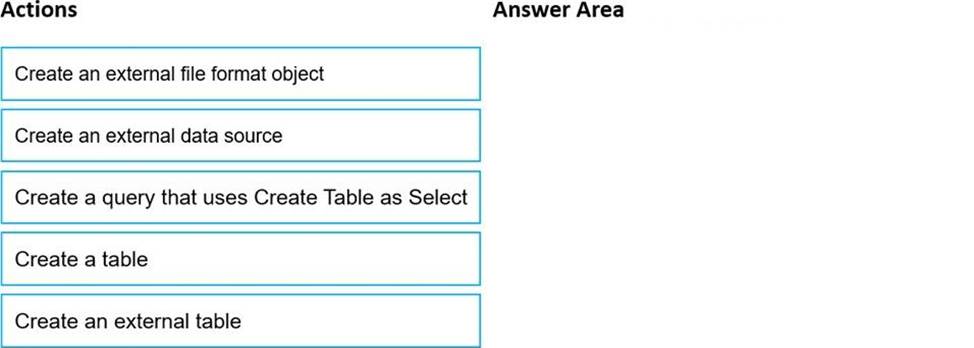
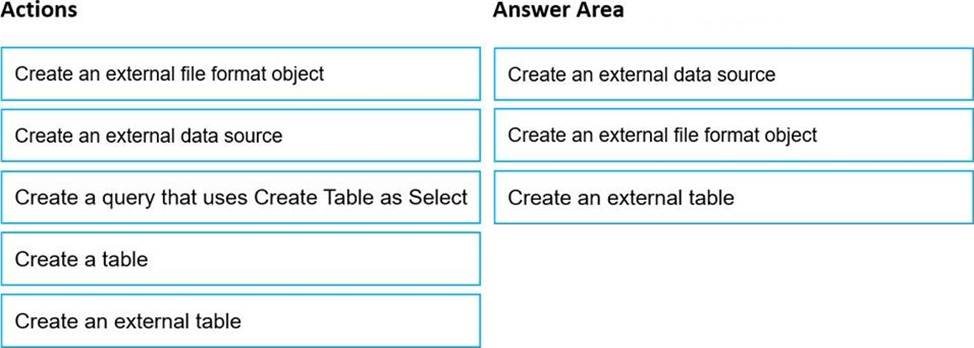
You need to build a solution to ensure that users can query specific files in an Azure Data Lake Storage Gen2 account from an Azure Synapse Analytics serverless SQL pool.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order. NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.
HOTSPOT
You are creating dimensions for a data warehouse in an Azure Synapse Analytics dedicated SQL pool.
You create a table by using the Transact-SQL statement shown in the following exhibit.
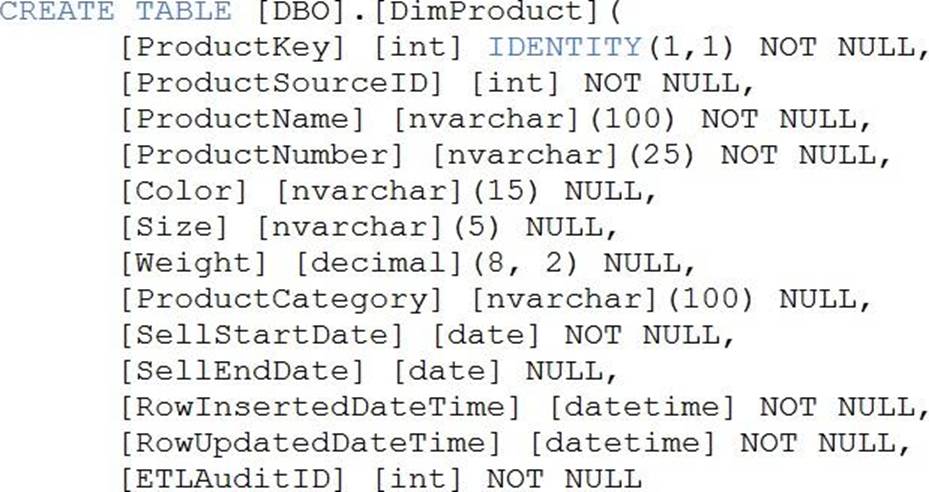
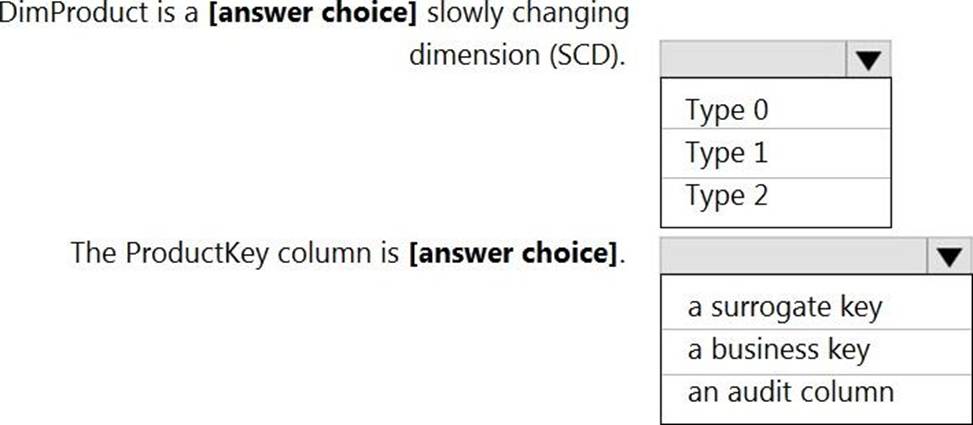
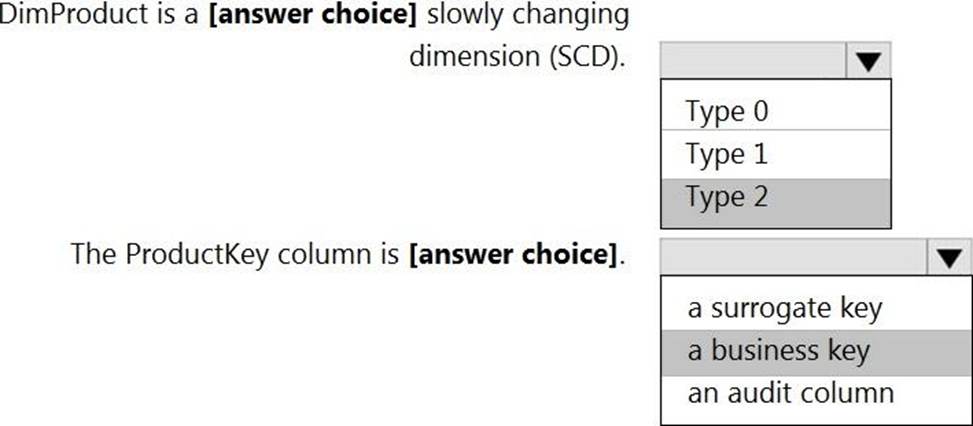
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic. NOTE: Each correct selection is worth one point.
You use Azure Data Factory to create data pipelines.
You are evaluating whether to integrate Data Factory and GitHub for source and version control.
What are two advantages of the integration? Each correct answer presents a complete solution. NOTE: Each correct selection is worth one point.
- A . the ability to save without publishing
- B . lower pipeline execution times
- C . the ability to save pipelines that have validation issues
- D . additional triggers
DRAG DROP
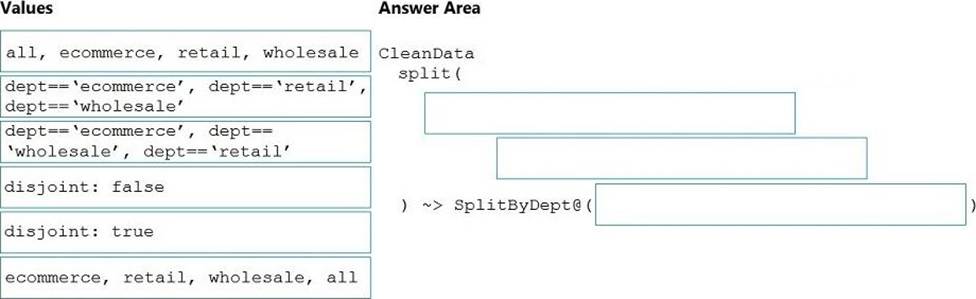
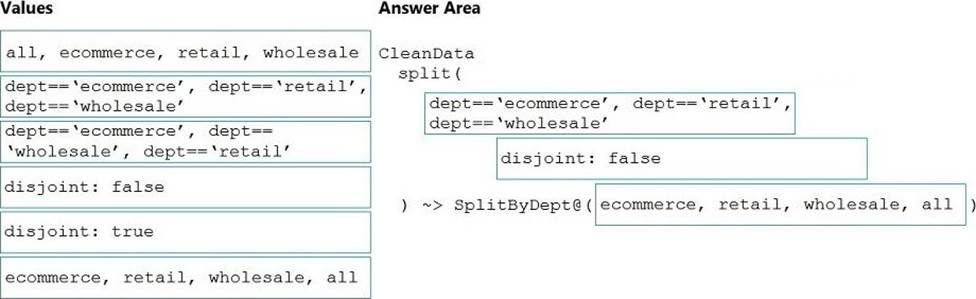
You need to create an Azure Data Factory pipeline to process data for the following three departments at your company: Ecommerce, retail, and wholesale. The solution must ensure that data can also be processed for the entire company.
How should you complete the Data Factory data flow script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.
HOTSPOT
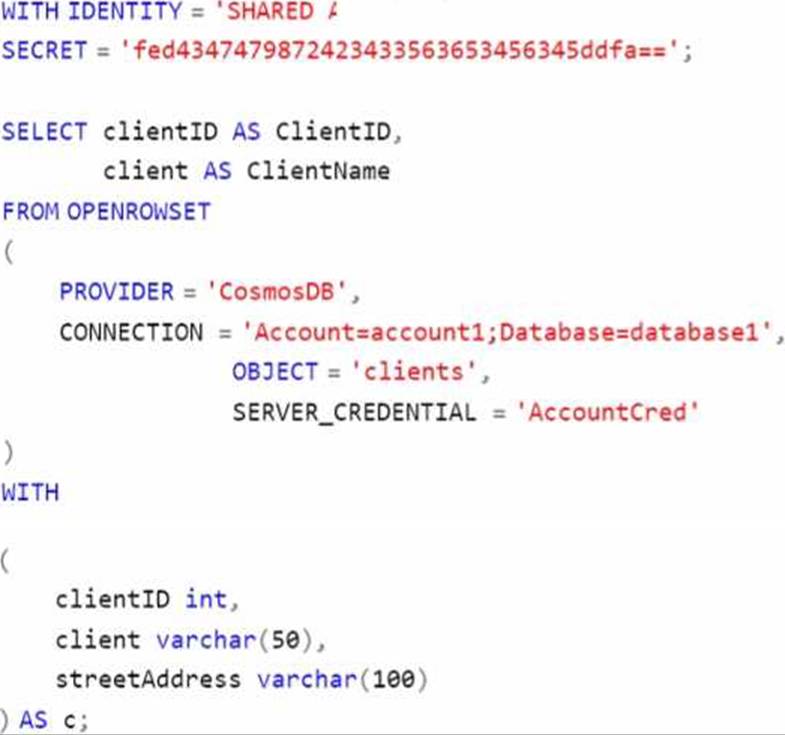
You have an Azure subscription that contains an Azure Cosmos DB analytical store and an Azure Synapse Analytics workspace named WS 1. WS1 has a serverless SQL pool name Pool1.
You execute the following query by using Pool1.
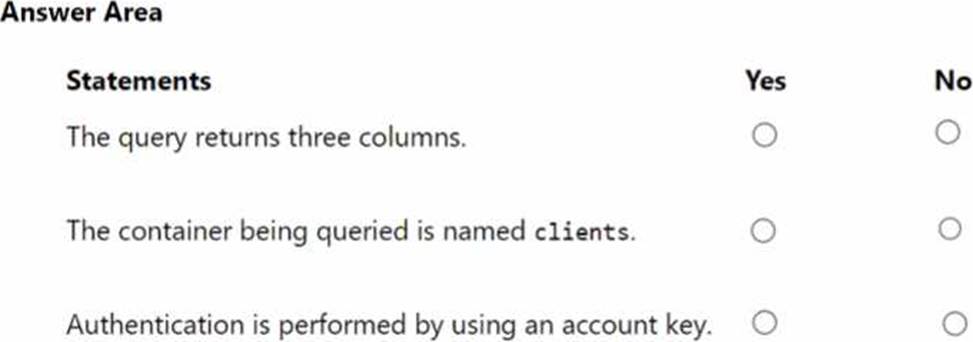
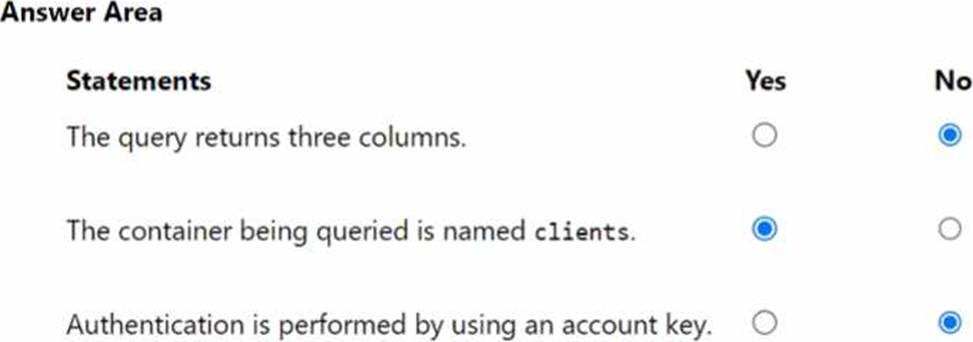
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
DRAG DROP
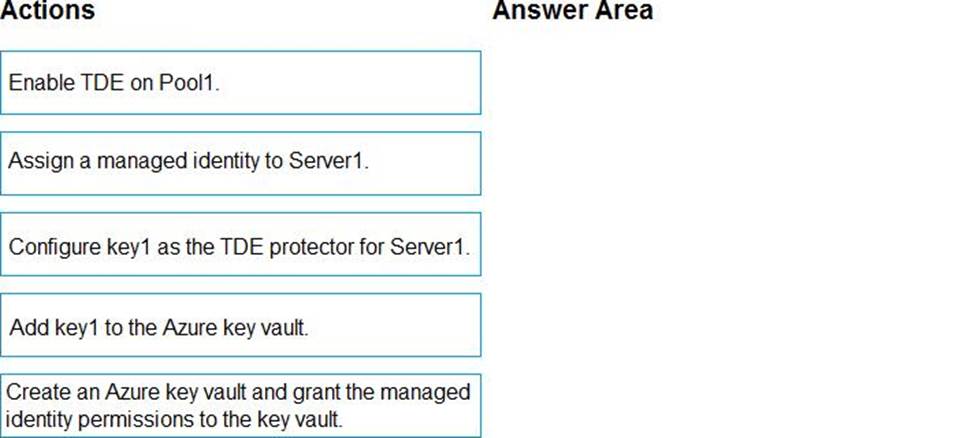
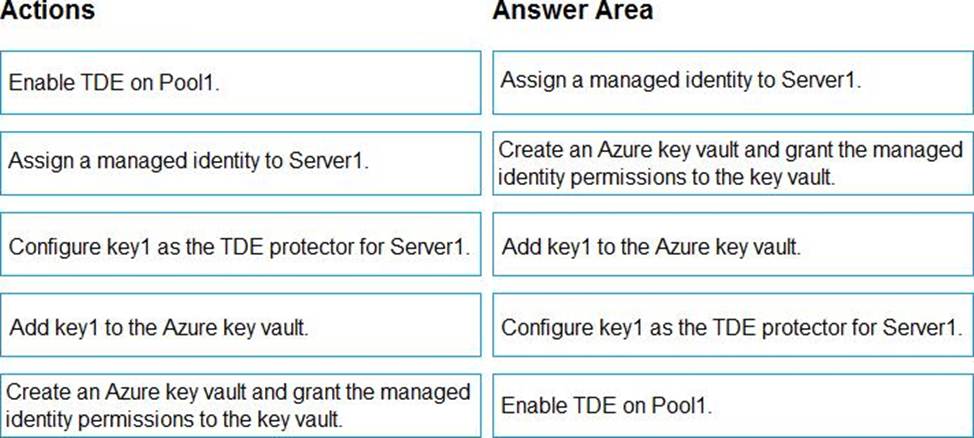
You have an Azure Synapse Analytics SQL pool named Pool1 on a logical Microsoft SQL server named Server1.
You need to implement Transparent Data Encryption (TDE) on Pool1 by using a custom key named key1.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
You are designing an Azure Databricks cluster that runs user-defined local processes.
You need to recommend a cluster configuration that meets the following requirements:
• Minimize query latency.
• Maximize the number of users that can run queues on the cluster at the same time
« Reduce overall costs without compromising other requirements
Which cluster type should you recommend?
- A . Standard with Auto termination
- B . Standard with Autoscaling
- C . High Concurrency with Autoscaling
- D . High Concurrency with Auto Termination
You are designing a highly available Azure Data Lake Storage solution that will include geo-zone-redundant storage (GZRS).
You need to monitor for replication delays that can affect the recovery point objective (RPO).
What should you include in the monitoring solution?
- A . availability
- B . Average Success E2E Latency
- C . 5xx: Server Error errors
- D . Last Sync Time
You plan to create an Azure Synapse Analytics dedicated SQL pool.
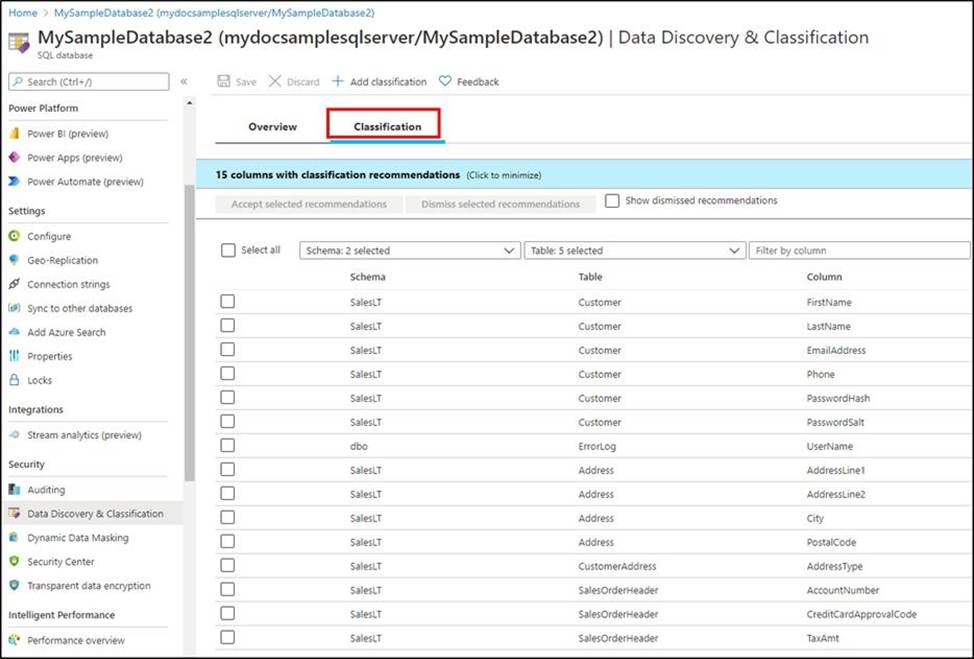
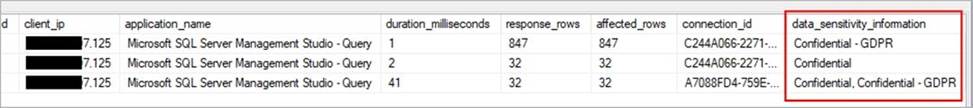
You need to minimize the time it takes to identify queries that return confidential information as defined by the company’s data privacy regulations and the users who executed the queues.
Which two components should you include in the solution? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
- A . sensitivity-classification labels applied to columns that contain confidential information
- B . resource tags for databases that contain confidential information
- C . audit logs sent to a Log Analytics workspace
- D . dynamic data masking for columns that contain confidential information