Microsoft DP-203 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-203
- Exam Name: Data Engineering on Microsoft Azure
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
You have an Azure Stream Analytics query. The query returns a result set that contains 10,000 distinct values for a column named clusterID.
You monitor the Stream Analytics job and discover high latency.
You need to reduce the latency.
Which two actions should you perform? Each correct answer presents a complete solution. NOTE: Each correct selection is worth one point.
- A . Add a pass-through query.
- B . Add a temporal analytic function.
- C . Scale out the query by using PARTITION BY.
- D . Convert the query to a reference query.
- E . Increase the number of streaming units.
You develop data engineering solutions for a company.
A project requires the deployment of data to Azure Data Lake Storage.
You need to implement role-based access control (RBAC) so that project members can manage the Azure Data Lake Storage resources.
Which three actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
- A . Assign Azure AD security groups to Azure Data Lake Storage.
- B . Configure end-user authentication for the Azure Data Lake Storage account.
- C . Configure service-to-service authentication for the Azure Data Lake Storage account.
- D . Create security groups in Azure Active Directory (Azure AD) and add project members.
- E . Configure access control lists (ACL) for the Azure Data Lake Storage account.
You have two fact tables named Flight and Weather. Queries targeting the tables will be based on the join between the following columns.
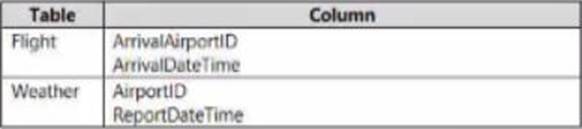
You need to recommend a solution that maximum query performance.
What should you include in the recommendation?
- A . In each table, create a column as a composite of the other two columns in the table.
- B . In each table, create an IDENTITY column.
- C . In the tables, use a hash distribution of ArriveDateTime and ReportDateTime.
- D . In the tables, use a hash distribution of ArriveAirPortID and AirportID.
You need to trigger an Azure Data Factory pipeline when a file arrives in an Azure Data Lake Storage Gen2 container.
Which resource provider should you enable?
- A . Microsoft.Sql
- B . Microsoft-Automation
- C . Microsoft.EventGrid
- D . Microsoft.EventHub
You have an Azure Synapse Analytics dedicated SQL pool named Pool1 and a database named DB1.
DB1 contains a fact table named Table1.
You need to identify the extent of the data skew in Table1.
What should you do in Synapse Studio?
- A . Connect to the built-in pool and run dbcc pdw_showspaceused.
- B . Connect to the built-in pool and run dbcc checkalloc.
- C . Connect to Pool1 and query sys.dm_pdw_node_scacus.
- D . Connect to Pool1 and query sys.dm_pdw_nodes_db_partition_scacs.
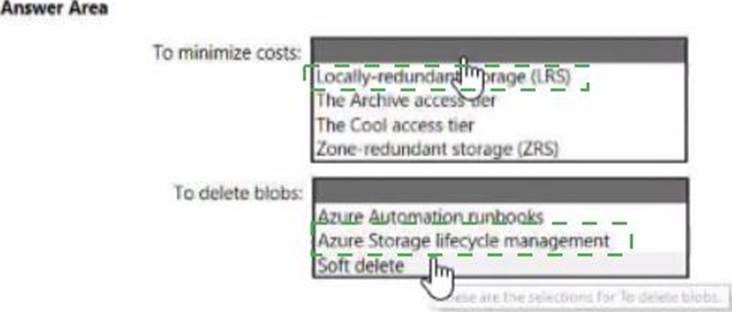
HOTSPOT
You have an Azure subscription.
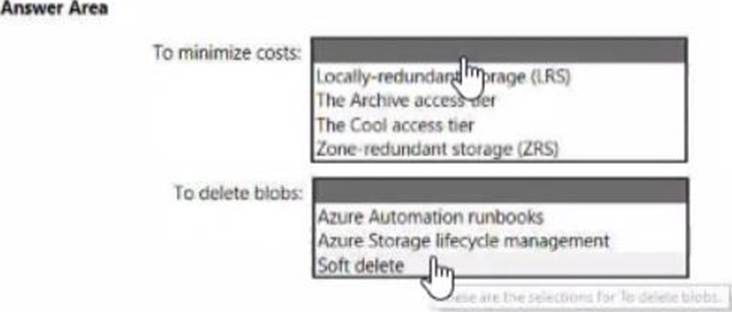
You need to deploy an Azure Data Lake Storage Gen2 Premium account.
The solution must meet the following requirements:
• Blobs that are older than 365 days must be deleted.
• Administrator efforts must be minimized.
• Costs must be minimized
What should you use? To answer, select the appropriate options in the answer area. NOTE Each correct selection is worth one point.
DRAG DROP
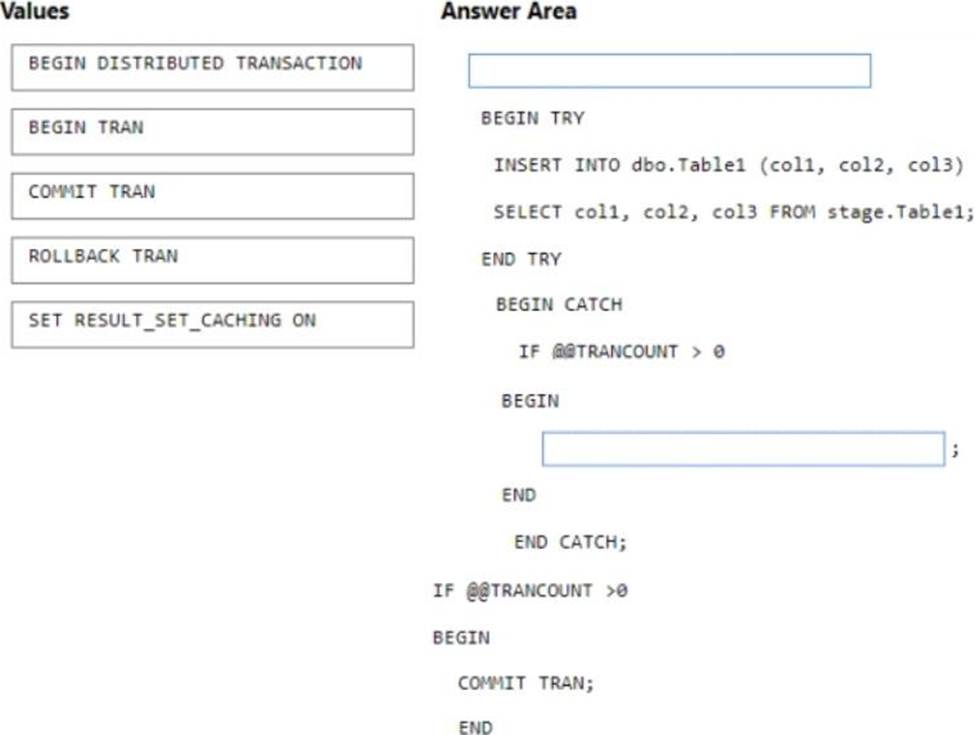
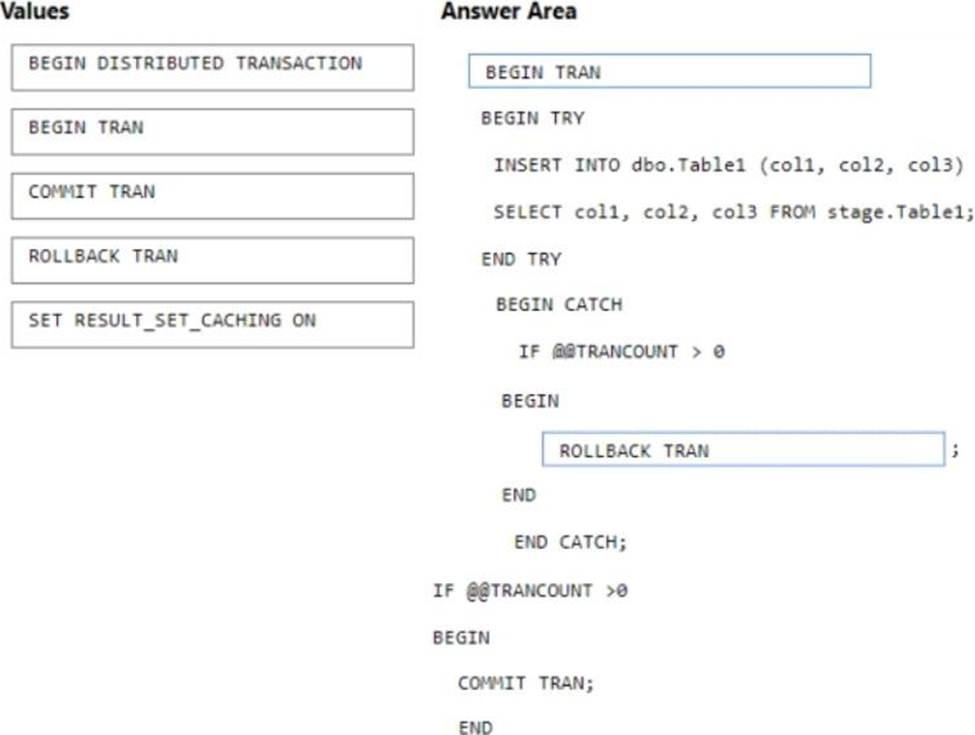
You are batch loading a table in an Azure Synapse Analytics dedicated SQL pool.
You need to load data from a staging table to the target table. The solution must ensure that if an error occurs while loading the data to the target table, all the inserts in that batch are undone.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content. NOTE Each correct selection is worth one point.
You are designing a partition strategy for a fact table in an Azure Synapse Analytics dedicated SQL pool.
The table has the following specifications:
• Contain sales data for 20,000 products.
• Use hash distribution on a column named ProduclID,
• Contain 2.4 billion records for the years 20l9 and 2020.
Which number of partition ranges provides optimal compression and performance of the clustered columnstore index?
- A . 40
- B . 240
- C . 400
- D . 2,400
You have an Azure Synapse Analytics dedicated SQL pool named Pool1 and a database named DB1.
DB1 contains a fact table named Table1.
You need to identify the extent of the data skew in Table1.
What should you do in Synapse Studio?
- A . Connect to the built-in pool and query sysdm_pdw_sys_info.
- B . Connect to Pool1 and run DBCC CHECKALLOC.
- C . Connect to the built-in pool and run DBCC CHECKALLOC.
- D . Connect to Pool! and query sys.dm_pdw_nodes_db_partition_stats.
HOTSPOT
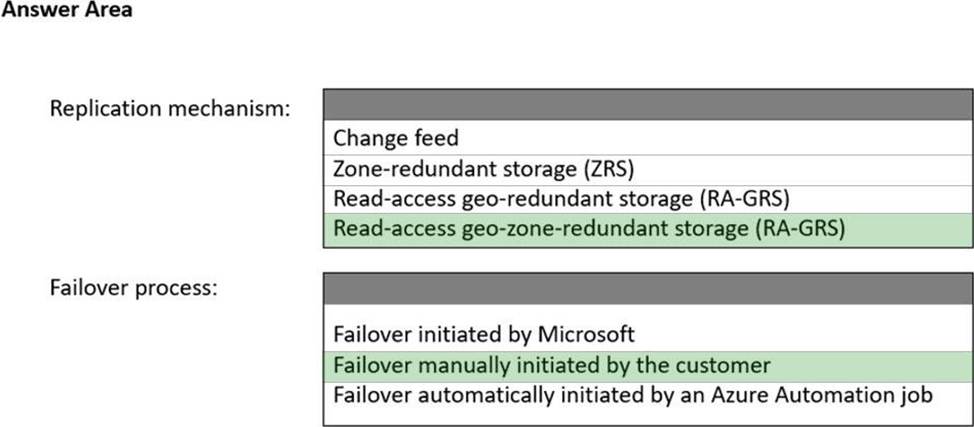
You plan to create an Azure Data Lake Storage Gen2 account
You need to recommend a storage solution that meets the following requirements:
• Provides the highest degree of data resiliency
• Ensures that content remains available for writes if a primary data center fails
What should you include in the recommendation? To answer, select the appropriate options in the answer area.