
Microsoft DP-100 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-100
- Exam Name: Designing and Implementing a Data Science Solution on Azure
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
You register a model that you plan to use in a batch inference pipeline.
The batch inference pipeline must use a ParallelRunStep step to process files in a file dataset. The script has the ParallelRunStep step runs must process six input files each time the inferencing function is called.
You need to configure the pipeline.
Which configuration setting should you specify in the ParallelRunConfig object for the PrallelRunStep step?
- A . process_count_per_node= "6"
- B . node_count= "6"
- C . mini_batch_size= "6"
- D . error_threshold= "6"
HOTSPOT
You plan to implement an Azure Machine Learning solution.
You have the following requirements:
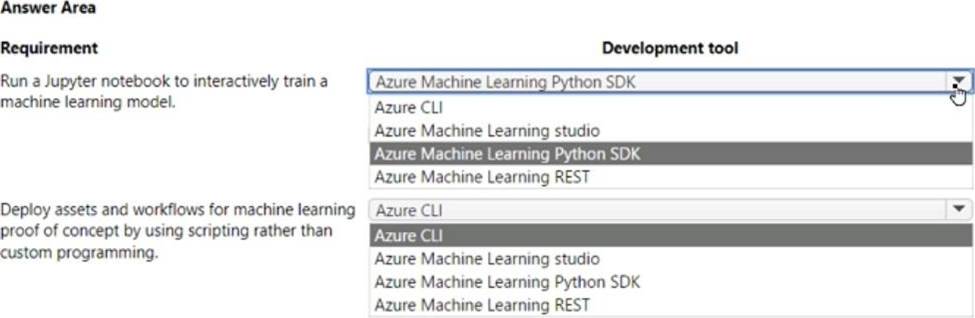
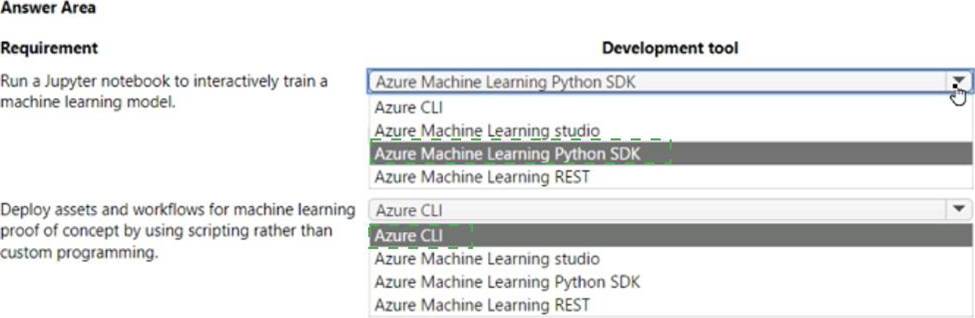
• Run a Jupyter notebook to interactively tram a machine learning model.
• Deploy assets and workflows for machine learning proof of concept by using scripting rather than custom programming.
You need to select a development technique for each requirement
Which development technique should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
You have a Python script that executes a pipeline.
The script includes the following code:
from azureml.core import Experiment
pipeline_run = Experiment(ws, ‘pipeline_test’).submit(pipeline)
You want to test the pipeline before deploying the script.
You need to display the pipeline run details written to the STDOUT output when the pipeline completes.
Which code segment should you add to the test script?
- A . pipeline_run.get.metrics()
- B . pipeline_run.wait_for_completion(show_output=True)
- C . pipeline_param = PipelineParameter(name="stdout", default_value="console")
- D . pipeline_run.get_status()
DRAG DROP
You have a dataset that contains over 150 features. You use the dataset to train a Support Vector Machine (SVM) binary classifier.
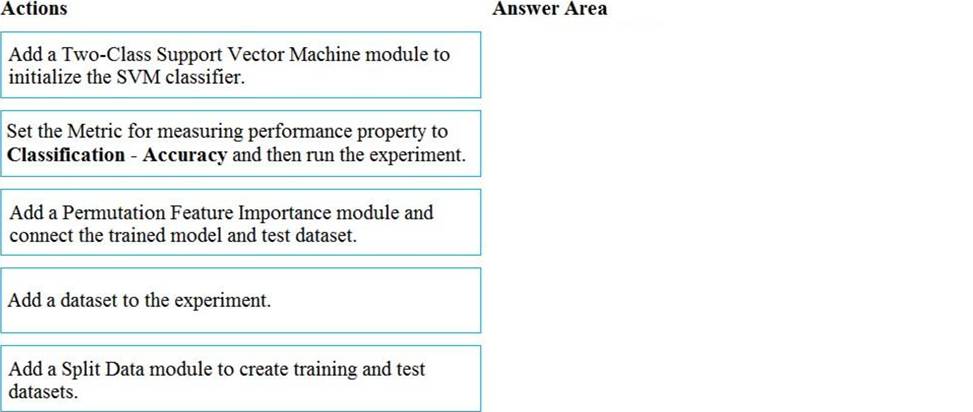
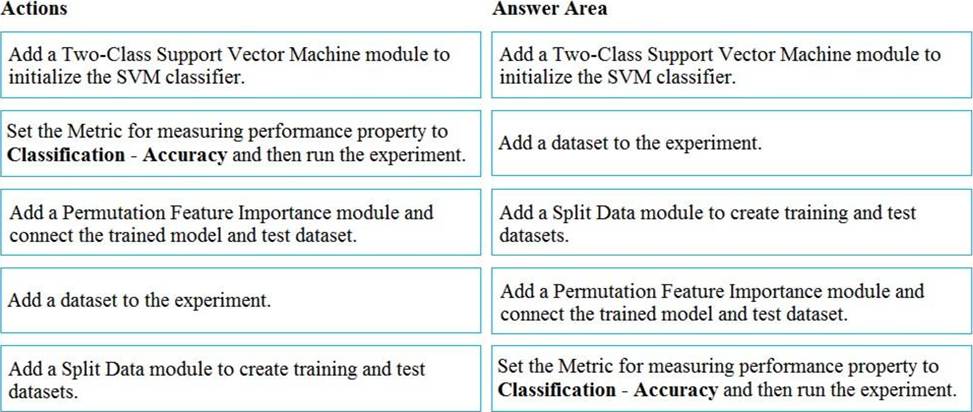
You need to use the Permutation Feature Importance module in Azure Machine Learning Studio to compute a set of feature importance scores for the dataset.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a model to predict the price of a student’s artwork depending on the following variables: the student’s length of education, degree type, and art form.
You start by creating a linear regression model.
You need to evaluate the linear regression model.
Solution: Use the following metrics: Mean Absolute Error, Root Mean Absolute Error, Relative Absolute Error, Accuracy, Precision, Recall, F1 score, and AUC.
Does the solution meet the goal?
- A . Yes
- B . No
HOTSPOT
You are creating data wrangling and model training solutions in an Azure Machine Learning workspace.
You must use the same Python notebook to perform both data wrangling and model training.
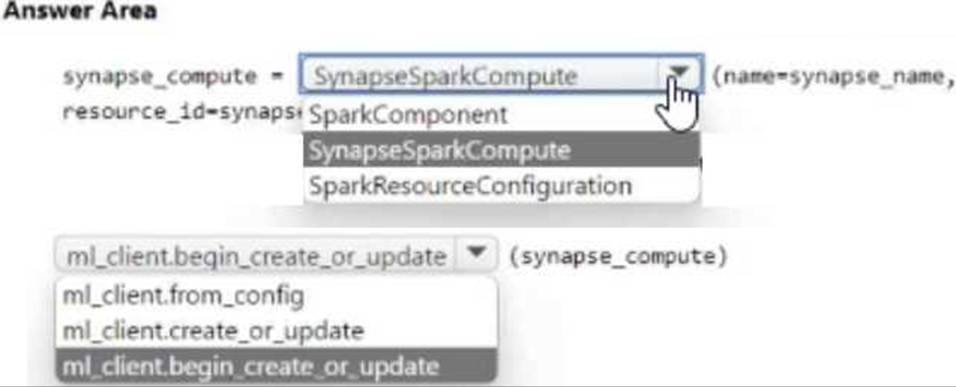
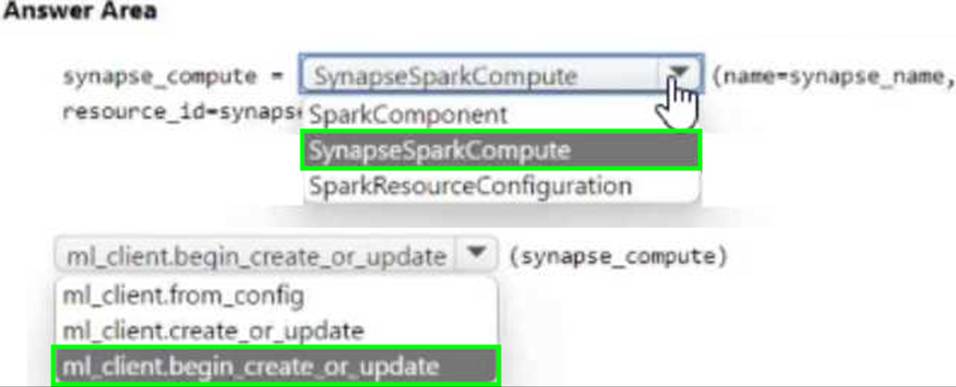
You need to use the Azure Machine Learning Python SDK v2 to define and configure the Synapse Spark pool asynchronously in the workspace as dedicated compute
How should you complete the rode segment? To answer, select the appropriate options in the answer area. NOTE: Lach correct selection is worth one point.
DRAG DROP
You manage an Azure Machine Learning workspace That has an Azure Machine Learning datastore.
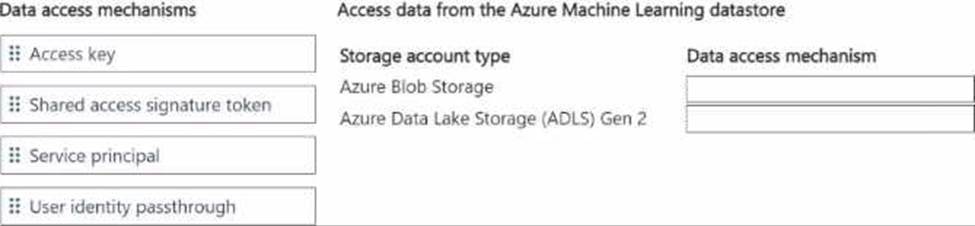
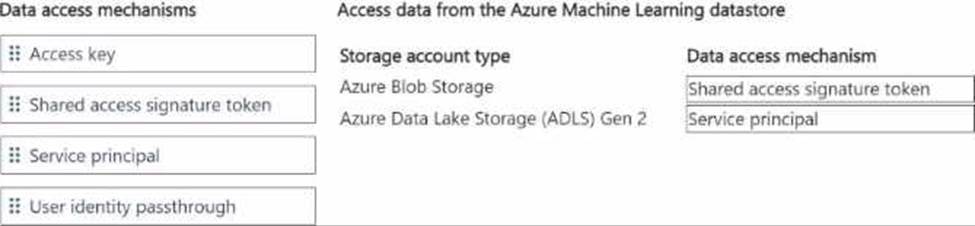
Data must be loaded from the following sources:
• a credential-less Azure Blob Storage
• an Azure Data Lake Storage (ADLS) Gen 2 which is not a credential-less datastore
You need to define the authentication mechanisms to access data in the Azure Machine Learning datastore.
Which data access mechanism should you use? To answer, move the appropriate data access mechanisms to the correct storage types. You may use each data access mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.
HOTSPOT
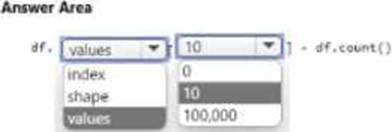
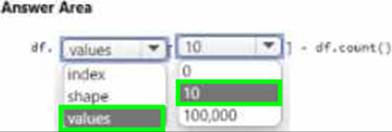
You load data from a notebook in an Azure Machine Learning workspace into a panda’s cat frame.
The data contains 10.000 records. Each record consists of 10 columns.
You must identify the number of missing values in each of the columns.
You need to complete the Python code that will return the number of missing values in each of the columns.
Which code segments should you use? To answer, select the appropriate options in the answer area. NOTE; Each correct selection it worth one point.
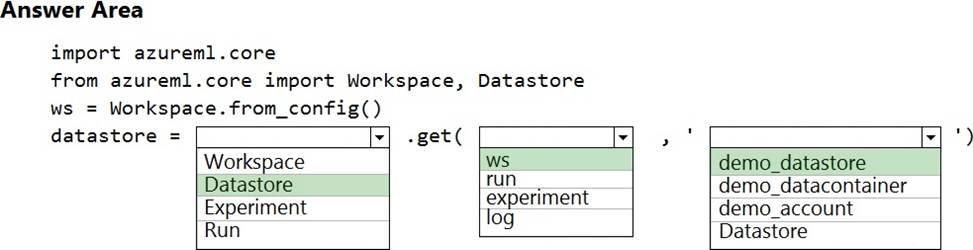
HOTSPOT
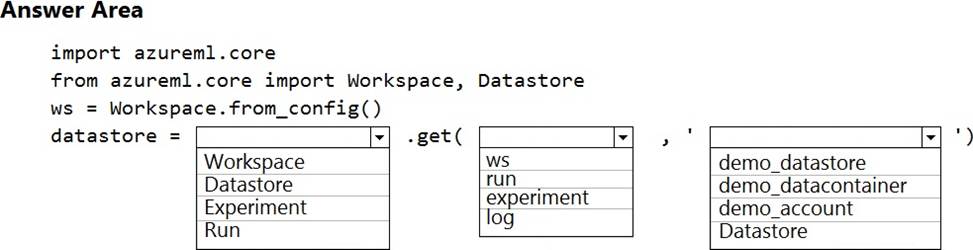
A coworker registers a datastore in a Machine Learning services workspace by using the following code:
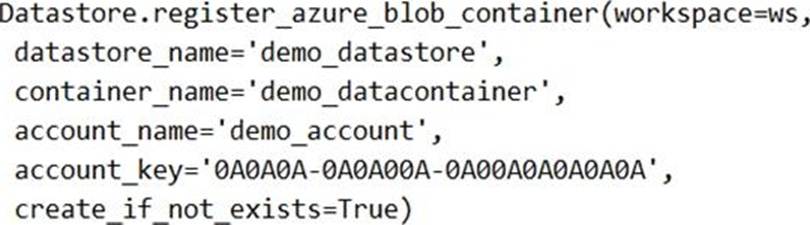
You need to write code to access the datastore from a notebook.
You use Azure Machine Learning to tram a model.
You must use Baylean sampling to Tune hyperparaters.
You need to select a learning_rate parameter distribution.
Which two distributions can you use? Each correct answer presents a complete solution. NOTE: Each correct selection is worth one point.
- A . Normal
- B . Uniform
- C . Choice
- D . LogUniform
- E . QNormal