
Microsoft DP-100 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-100
- Exam Name: Designing and Implementing a Data Science Solution on Azure
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
HOTSPOT
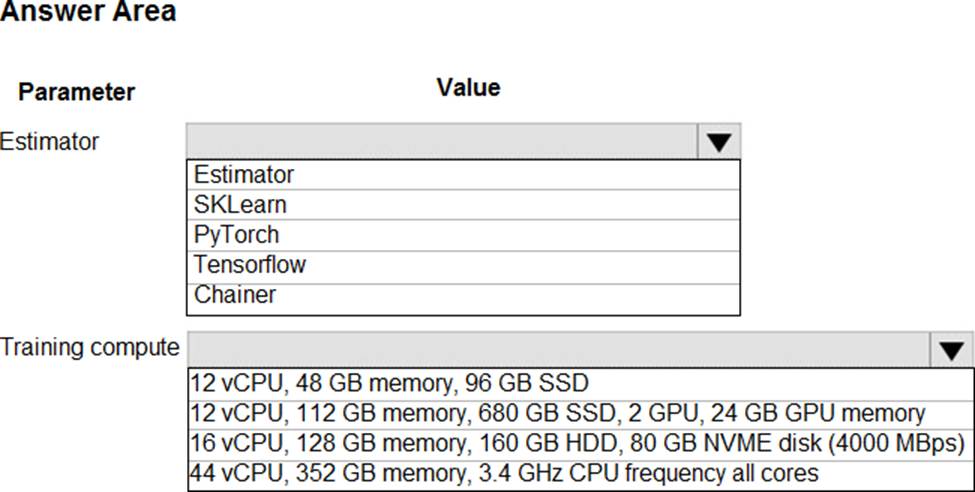
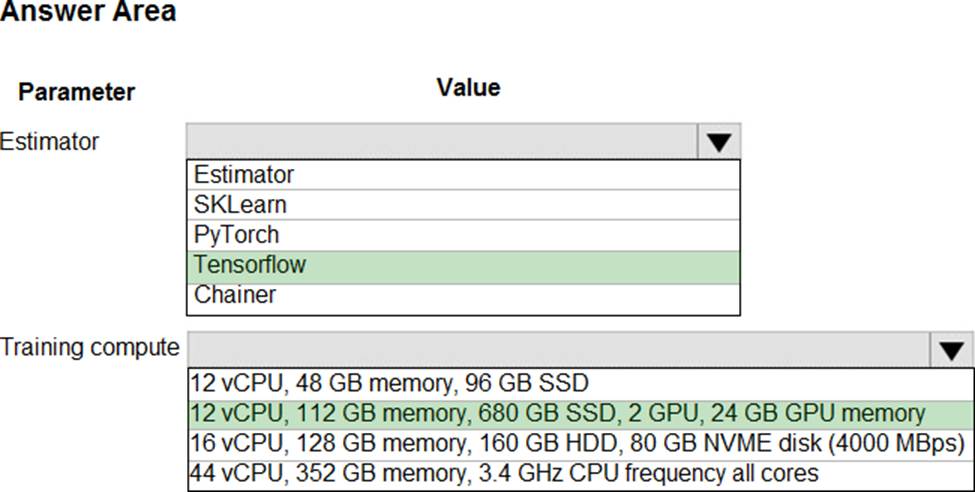
space and set up a development environment. You plan to train a deep neural network (DNN) by using the Tensorflow framework and by using estimators to submit training scripts.
You must optimize computation speed for training runs.
You need to choose the appropriate estimator to use as well as the appropriate training compute target configuration.
Which values should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model.
You configure a HyperDriveConfig for the experiment by running the following code:
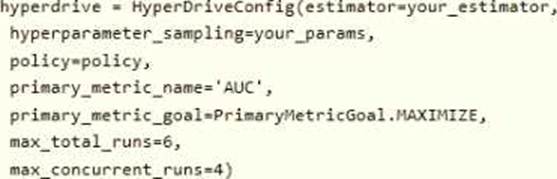
variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted. You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric.
Solution: Run the following code:
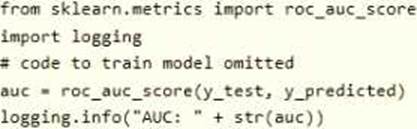
Does the solution meet the goal?
- A . Yes
- B . No
DRAG DROP
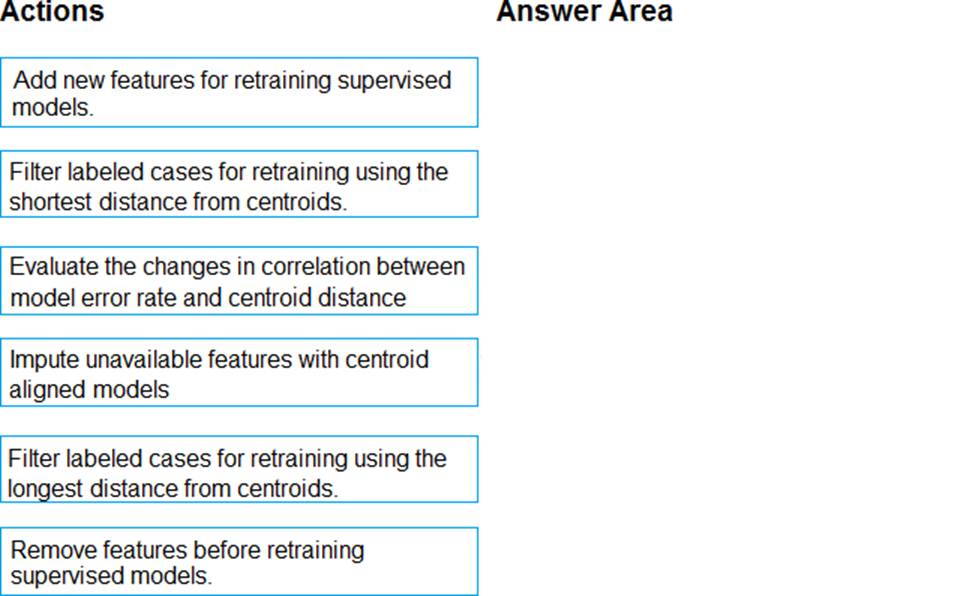
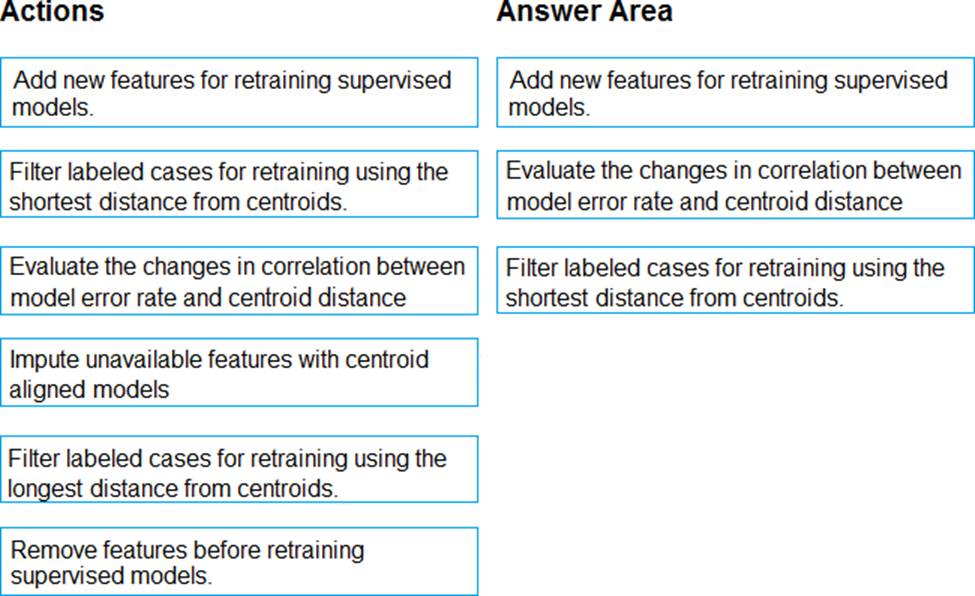
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
DRAG DROP
You configure a Deep Learning Virtual Machine for Windows.
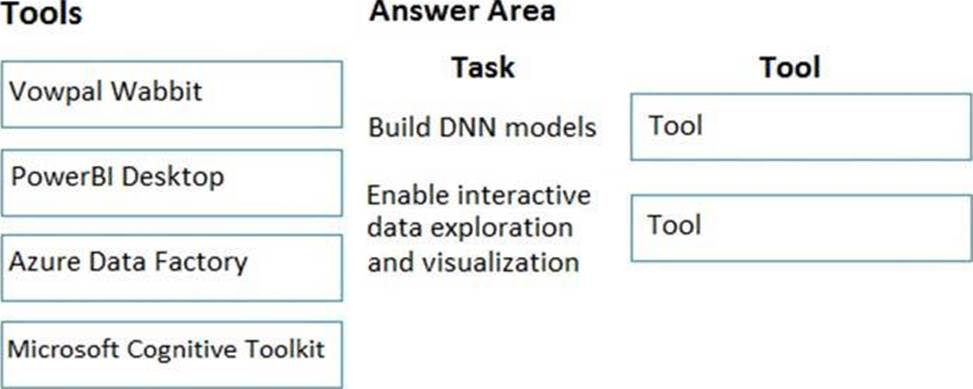
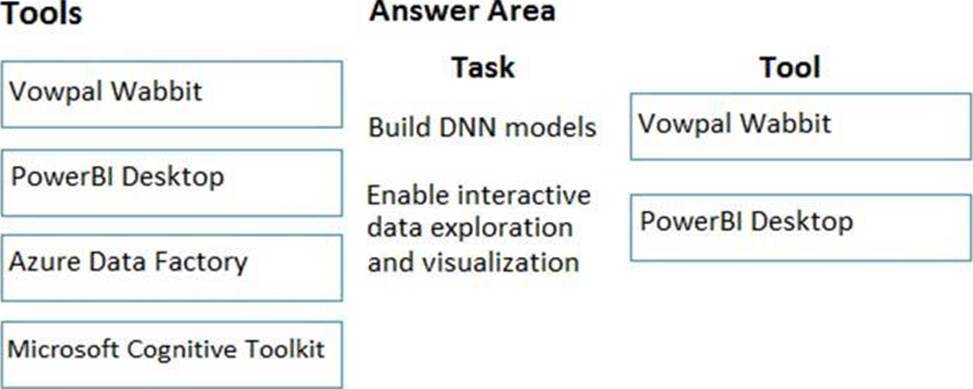
You need to recommend tools and frameworks to perform the following:
✑ Build deep neural network (DNN) models
✑ Perform interactive data exploration and visualization
Which tools and frameworks should you recommend? To answer, drag the appropriate tools to the correct tasks. Each tool may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are a data scientist using Azure Machine Learning Studio.
You need to normalize values to produce an output column into bins to predict a target column.
Solution: Apply an Equal Width with Custom Start and Stop binning mode.
Does the solution meet the goal?
- A . Yes
- B . No
HOTSPOT
You manage an Azure Machine Learning workspace. The development environment is configured with a Serverless Spark compute in Azure Machine Learning Notebooks.
You perform interactive data wrangling to clean up the Titanic dataset and store it as a new dataset (Line numbers are used for reference only.)
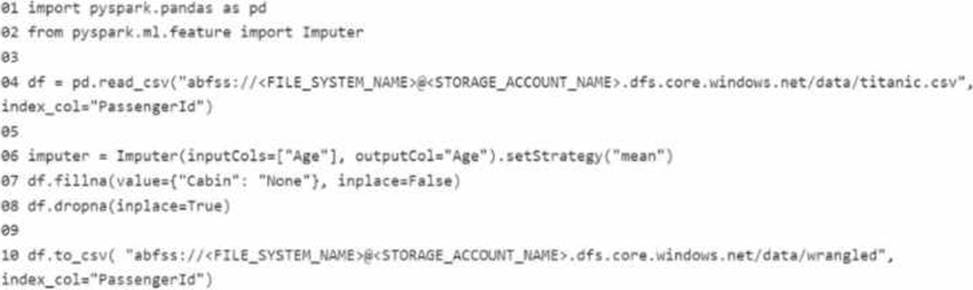
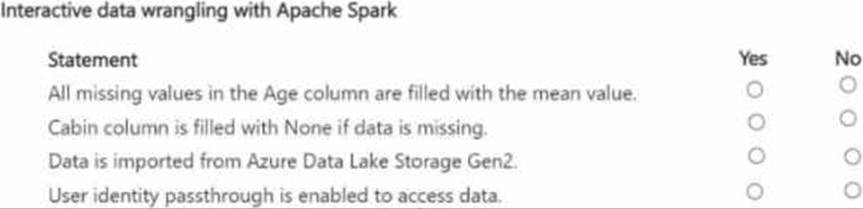
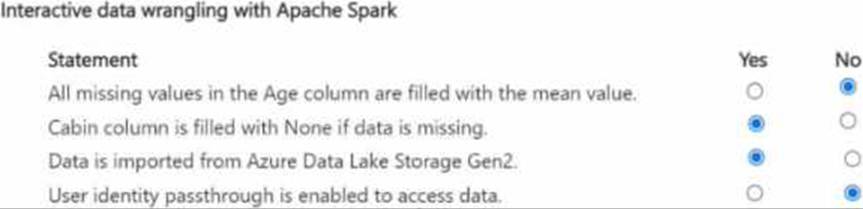
For each of the following statements, select Yes if the statement is true Otherwise, select No NOTE: Bach correct selection is worth one point.
HOTSPOT
You manage an Azure Machine Learning workspace. The development environment is configured with a Serverless Spark compute in Azure Machine Learning Notebooks.
You perform interactive data wrangling to clean up the Titanic dataset and store it as a new dataset (Line numbers are used for reference only.)
For each of the following statements, select Yes if the statement is true Otherwise, select No NOTE: Bach correct selection is worth one point.
You are conducting feature engineering to prepuce data for further analysis.
The data includes seasonal patterns on inventory requirements.
You need to select the appropriate method to conduct feature engineering on the data.
Which method should you use?
- A . Exponential Smoothing (ETS) function.
- B . One Class Support Vector Machine module
- C . Time Series Anomaly Detection module
- D . Finite Impulse Response (FIR) Filter module.
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You plan to use a Python script to run an Azure Machine Learning experiment. The script creates a reference to the experiment run context, loads data from a file, identifies the set of unique values for the label column, and completes the experiment run:
from azureml.core import Run
import pandas as pd
run = Run.get_context()
data = pd.read_csv(‘data.csv’)
label_vals = data[‘label’].unique()
# Add code to record metrics here run.complete()
The experiment must record the unique labels in the data as metrics for the run that can be reviewed later.
You must add code to the script to record the unique label values as run metrics at the point indicated by the comment.
Solution: Replace the comment with the following code:
run.log_table(‘Label Values’, label_vals)
Does the solution meet the goal?
- A . Yes
- B . No
You register a model that you plan to use in a batch inference pipeline.
The batch inference pipeline must use a ParallelRunStep step to process files in a file dataset. The script has the ParallelRunStep step runs must process six input files each time the inferencing function is called.
You need to configure the pipeline.
Which configuration setting should you specify in the ParallelRunConfig object for the PrallelRunStep step?
- A . process_count_per_node= "6"
- B . node_count= "6"
- C . mini_batch_size= "6"
- D . error_threshold= "6"