
Google Professional Machine Learning Engineer Practice Exams
Last updated on Oct 10,2026- Exam Code: Professional Machine Learning Engineer
- Exam Name: Google Professional Machine Learning Engineer
- Certification Provider: Google
- Latest update: Oct 10,2026
You are developing an ML model that predicts the cost of used automobiles based on data such as location, condition model type color, and engine-‘battery efficiency. The data is updated every night Car dealerships will use the model to determine appropriate car prices. You created a Vertex Al pipeline that reads the data splits the data into training/evaluation/test sets performs feature engineering trains the model by using the training dataset and validates the model by using the evaluation dataset. You need to configure a retraining workflow that minimizes cost.
What should you do?
- A . Compare the training and evaluation losses of the current run If the losses are similar, deploy the model to a Vertex AI endpoint Configure a cron job to redeploy the pipeline every night.
- B . Compare the training and evaluation losses of the current run If the losses are similar deploy the model to a Vertex Al endpoint with training/serving skew threshold model monitoring When the model monitoring threshold is tnggered redeploy the pipeline.
- C . Compare the results to the evaluation results from a previous run If the performance improved deploy the model to a Vertex Al endpoint Configure a cron job to redeploy the pipeline every night.
- D . Compare the results to the evaluation results from a previous run If the performance improved deploy the model to a Vertex Al endpoint with training/serving skew threshold model monitoring. When the model monitoring threshold is triggered, redeploy the pipeline.
B
Explanation:
Comparing the training and evaluation losses of the current run is a good way to check if the model is overfitting or underfitting. If the losses are similar, it means that the model is generalizing well and can be deployed to a Vertex AI endpoint. Vertex AI endpoint is a service that allows you to serve your ML models online and scale them automatically. By using a training/serving skew threshold model monitoring, you can detect if there is a significant difference between the data used for training and the data used for serving. This can indicate that the model is becoming stale or inaccurate over time. When the model monitoring threshold is triggered, it means that the model needs to be retrained with the latest data. By redeploying the pipeline, you can automate the retraining process and update the model with the new data. This way, you can minimize the cost of retraining and ensure that your model is always up-to-date and accurate.
Reference: Vertex AI documentation
Vertex AI endpoint documentation
Model monitoring documentation
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
You are developing a Kubeflow pipeline on Google Kubernetes Engine. The first step in the pipeline is to issue a query against BigQuery. You plan to use the results of that query as the input to the next step in your pipeline. You want to achieve this in the easiest way possible.
What should you do?
- A . Use the BigQuery console to execute your query and then save the query results Into a new BigQuery table.
- B . Write a Python script that uses the BigQuery API to execute queries against BigQuery Execute this script as the first step in your Kubeflow pipeline
- C . Use the Kubeflow Pipelines domain-specific language to create a custom component that uses the Python BigQuery client library to execute queries
- D . Locate the Kubeflow Pipelines repository on GitHub Find the BigQuery Query Component, copy that component’s URL, and use it to load the component into your pipeline. Use the component to execute queries against BigQuery
D
Explanation:
Kubeflow is an open source platform for developing, orchestrating, deploying, and running scalable and portable machine learning workflows on Kubernetes. Kubeflow Pipelines is a component of Kubeflow that allows you to build and manage end-to-end machine learning pipelines using a graphical user interface or a Python-based domain-specific language (DSL). Kubeflow Pipelines can help you automate and orchestrate your machine learning workflows, and integrate with various Google Cloud services and tools1
One of the Google Cloud services that you can use with Kubeflow Pipelines is BigQuery, which is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data. BigQuery can help you analyze and prepare your data for machine learning, and store and manage your machine learning models2
To execute a query against BigQuery as the first step in your Kubeflow pipeline, and use the results of that query as the input to the next step in your pipeline, the easiest way to do that is to use the BigQuery Query Component, which is a pre-built component that you can find in the Kubeflow Pipelines repository on GitHub. The BigQuery Query Component allows you to run a SQL query on BigQuery, and output the results as a table or a file. You can use the component’s URL to load the component into your pipeline, and specify the query and the output parameters. You can then use the output of the component as the input to the next step in your pipeline, such as a data processing or a model training step3
The other options are not as easy or feasible. Using the BigQuery console to execute your query and then save the query results into a new BigQuery table is not a good idea, as it does not integrate with your Kubeflow pipeline, and requires manual intervention and duplication of data. Writing a Python script that uses the BigQuery API to execute queries against BigQuery is not ideal, as it requires writing custom code and handling authentication and error handling. Using the Kubeflow Pipelines DSL to create a custom component that uses the Python BigQuery client library to execute queries is not optimal, as it requires creating and packaging a Docker container image for the component, and testing and debugging the component.
Reference: 1: Kubeflow Pipelines overview 2: BigQuery overview 3: BigQuery Query Component
You work at a mobile gaming startup that creates online multiplayer games Recently, your company observed an increase in players cheating in the games, leading to a loss of revenue and a poor user experience. You built a binary classification model to determine whether a player cheated after a completed game session, and then send a message to other downstream systems to ban the player that cheated Your model has performed well during testing, and you now need to deploy the model to production You want your serving solution to provide immediate classifications after a completed game session to avoid further loss of revenue.
What should you do?
- A . Import the model into Vertex Al Model Registry. Use the Vertex Batch Prediction service to run batch inference jobs.
- B . Save the model files in a Cloud Storage Bucket Create a Cloud Function to read the model files and make online inference requests on the Cloud Function.
- C . Save the model files in a VM Load the model files each time there is a prediction request and run an inference job on the VM.
- D . Import the model into Vertex Al Model Registry Create a Vertex Al endpoint that hosts the model and make online inference requests.
D
Explanation:
Online inference is a process where you send a single or a small number of prediction requests to a model and get immediate responses1. Online inference is suitable for scenarios where you need timely predictions, such as detecting cheating in online games. Online inference requires that the model is deployed to an endpoint, which is a resource that provides a service URL for prediction requests2.
Vertex AI Model Registry is a central repository where you can manage the lifecycle of your ML models3. You can import models from various sources, such as custom models or AutoML models, and assign them to different versions and aliases3. You can also deploy models to endpoints, which are resources that provide a service URL for online prediction2.
By importing the model into Vertex AI Model Registry, you can leverage the Vertex AI features to monitor and update the model3. You can use Vertex AI Experiments to track and compare the metrics of different model versions, such as accuracy, precision, recall, and AUC. You can also use Vertex AI Explainable AI to generate feature attributions that show how much each input feature contributed to the model’s prediction.
By creating a Vertex AI endpoint that hosts the model, you can use the Vertex AI Prediction service to serve online inference requests2. Vertex AI Prediction provides various benefits, such as scalability, reliability, security, and logging2. You can use the Vertex AI API or the Google Cloud console to send online inference requests to the endpoint and get immediate classifications4.
Therefore, the best option for your scenario is to import the model into Vertex AI Model Registry, create a Vertex AI endpoint that hosts the model, and make online inference requests.
The other options are not suitable for your scenario, because they either do not provide immediate classifications, such as using batch prediction or loading the model files each time, or they do not use Vertex AI Prediction, which would require more development and maintenance effort, such as creating a Cloud Function or a VM.
Reference: Online versus batch prediction | Vertex AI | Google Cloud Deploy a model to an endpoint | Vertex AI | Google Cloud Introduction to Vertex AI Model Registry | Google Cloud Get online predictions | Vertex AI | Google Cloud
You manage a team of data scientists who use a cloud-based backend system to submit training jobs.
This system has become very difficult to administer, and you want to use a managed service instead.
The data scientists you work with use many different frameworks, including Keras, PyTorch, theano.
Scikit-team, and custom libraries.
What should you do?
- A . Use the Al Platform custom containers feature to receive training jobs using any framework
- B . Configure Kubeflow to run on Google Kubernetes Engine and receive training jobs through TFJob
- C . Create a library of VM images on Compute Engine; and publish these images on a centralized repository
- D . Set up Slurm workload manager to receive jobs that can be scheduled to run on your cloud infrastructure.
A
Explanation:
A cloud-based backend system is a system that runs on a cloud platform and provides services or resources to other applications or users. A cloud-based backend system can be used to submit training jobs, which are tasks that involve training a machine learning model on a given dataset using a specific framework and configuration1
However, a cloud-based backend system can also have some drawbacks, such as:
High maintenance: A cloud-based backend system may require a lot of administration and management, such as provisioning, scaling, monitoring, and troubleshooting the cloud resources and services. This can be time-consuming and costly, and may distract from the core business objectives2 Low flexibility: A cloud-based backend system may not support all the frameworks and libraries that the data scientists need to use for their training jobs. This can limit the choices and capabilities of the data scientists, and affect the quality and performance of their models3
Poor integration: A cloud-based backend system may not integrate well with other cloud services or tools that the data scientists need to use for their machine learning workflows, such as data processing, model deployment, or model monitoring. This can create compatibility and interoperability issues, and reduce the efficiency and productivity of the data scientists.
Therefore, it may be better to use a managed service instead of a cloud-based backend system to submit training jobs. A managed service is a service that is provided and operated by a third-party provider, and offers various benefits, such as:
Low maintenance: A managed service handles the administration and management of the cloud resources and services, and abstracts away the complexity and details of the underlying infrastructure. This can save time and money, and allow the data scientists to focus on their core tasks2
High flexibility: A managed service can support multiple frameworks and libraries that the data scientists need to use for their training jobs, and allow them to customize and configure their training environments and parameters. This can enhance the choices and capabilities of the data scientists, and improve the quality and performance of their models3
Easy integration: A managed service can integrate seamlessly with other cloud services or tools that the data scientists need to use for their machine learning workflows, and provide a unified and consistent interface and experience. This can solve the compatibility and interoperability issues, and increase the efficiency and productivity of the data scientists.
One of the best options for using a managed service to submit training jobs is to use the AI Platform custom containers feature to receive training jobs using any framework. AI Platform is a Google Cloud service that provides a platform for building, deploying, and managing machine learning models. AI Platform supports various machine learning frameworks, such as TensorFlow, PyTorch, scikit-learn, and XGBoost, and provides various features, such as hyperparameter tuning, distributed training, online prediction, and model monitoring.
The AI Platform custom containers feature allows the data scientists to use any framework or library that they want for their training jobs, and package their training application and dependencies as a Docker container image. The data scientists can then submit their training jobs to AI Platform, and specify the container image and the training parameters. AI Platform will run the training jobs on the cloud infrastructure, and handle the scaling, logging, and monitoring of the training jobs. The data scientists can also use the AI Platform features to optimize, deploy, and manage their models.
The other options are not as suitable or feasible. Configuring Kubeflow to run on Google Kubernetes Engine and receive training jobs through TFJob is not ideal, as Kubeflow is mainly designed for TensorFlow-based training jobs, and does not support other frameworks or libraries. Creating a library of VM images on Compute Engine and publishing these images on a centralized repository is not optimal, as Compute Engine is a low-level service that requires a lot of administration and management, and does not provide the features and integrations of AI Platform. Setting up Slurm workload manager to receive jobs that can be scheduled to run on your cloud infrastructure is not relevant, as Slurm is a tool for managing and scheduling jobs on a cluster of nodes, and does not provide a managed service for training jobs.
Reference: 1: Cloud computing 2: Managed services 3: Machine learning frameworks: [Machine learning workflow]: [AI Platform overview]: [Custom containers for training]
You are building an ML model to detect anomalies in real-time sensor data. You will use Pub/Sub to handle incoming requests. You want to store the results for analytics and visualization.
How should you configure the pipeline?
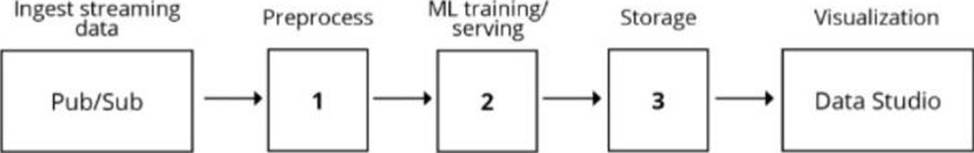
- A . 1 Dataflow, 2 – Al Platform, 3 BigQuery
- B . 1 DataProc, 2 AutoML, 3 Cloud Bigtable
- C . 1 BigQuery, 2 AutoML, 3 Cloud Functions
- D . 1 BigQuery, 2 Al Platform, 3 Cloud Storage
A
Explanation:
Dataflow is a fully managed service for executing Apache Beam pipelines that can process streaming or batch data1.
Al Platform is a unified platform that enables you to build and run machine learning applications across Google Cloud2.
BigQuery is a serverless, highly scalable, and cost-effective cloud data warehouse designed for business agility3.
These services are suitable for building an ML model to detect anomalies in real-time sensor data, as they can handle large-scale data ingestion, preprocessing, training, serving, storage, and visualization.
The other options are not as suitable because:
DataProc is a service for running Apache Spark and Apache Hadoop clusters, which are not optimized for streaming data processing4.
AutoML is a suite of machine learning products that enables developers with limited machine learning expertise to train high-quality models specific to their business needs5. However, it does not support custom models or real-time predictions.
Cloud Bigtable is a scalable, fully managed NoSQL database service for large analytical and operational workloads. However, it is not designed for ad hoc queries or interactive analysis. Cloud Functions is a serverless execution environment for building and connecting cloud services. However, it is not suitable for storing or visualizing data.
Cloud Storage is a service for storing and accessing data on Google Cloud. However, it is not a data warehouse and does not support SQL queries or visualization tools.
Your team frequently creates new ML models and runs experiments. Your team pushes code to a single repository hosted on Cloud Source Repositories. You want to create a continuous integration pipeline that automatically retrains the models whenever there is any modification of the code.
What should be your first step to set up the CI pipeline?
- A . Configure a Cloud Build trigger with the event set as "Pull Request"
- B . Configure a Cloud Build trigger with the event set as "Push to a branch"
- C . Configure a Cloud Function that builds the repository each time there is a code change.
- D . Configure a Cloud Function that builds the repository each time a new branch is created.
B
Explanation:
According to the web search results, Cloud Build1 is a service that executes your builds on Google Cloud Platform infrastructure. Cloud Build can import source code from Cloud Source Repositories2, Cloud Storage, GitHub, Bitbucket, or any publicly hosted Git repository. Cloud Build allows you to create and manage build triggers, which are automated workflows that run whenever a code change is pushed to your source repository. You can use Cloud Build triggers to automatically retrain your ML models whenever there is any modification of the code. Therefore, option B is the best way to set up the CI pipeline for the given use case, as it allows you to configure a Cloud Build trigger with the event set as “Push to a branch”, which means the trigger will run whenever a new commit is pushed to a specific branch of your source repository. The other options are not relevant or optimal for this scenario.
Reference: Cloud Build
Cloud Source Repositories
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
You are training a Resnet model on Al Platform using TPUs to visually categorize types of defects in automobile engines. You capture the training profile using the Cloud TPU profiler plugin and observe that it is highly input-bound. You want to reduce the bottleneck and speed up your model training process.
Which modifications should you make to the tf .data dataset? Choose 2 answers
- A . Use the interleave option for reading data
- B . Reduce the value of the repeat parameter
- C . Increase the buffer size for the shuffle option.
- D . Set the prefetch option equal to the training batch size
- E . Decrease the batch size argument in your transformation
A, D
Explanation:
The tf.data dataset is a TensorFlow API that provides a way to create and manipulate data pipelines for machine learning. The tf.data dataset allows you to apply various transformations to the data, such as reading, shuffling, batching, prefetching, and interleaving. These transformations can affect the performance and efficiency of the model training process1
One of the common performance issues in model training is input-bound, which means that the model is waiting for the input data to be ready and is not fully utilizing the computational resources. Input-bound can be caused by slow data loading, insufficient parallelism, or large data size. Input-bound can be detected by using the Cloud TPU profiler plugin, which is a tool that helps you analyze the performance of your model on Cloud TPUs. The Cloud TPU profiler plugin can show you the percentage of time that the TPU cores are idle, which indicates input-bound2
To reduce the input-bound bottleneck and speed up the model training process, you can make some modifications to the tf.data dataset.
Two of the modifications that can help are:
Use the interleave option for reading data. The interleave option allows you to read data from multiple files in parallel and interleave their records. This can improve the data loading speed and reduce the idle time of the TPU cores. The interleave option can be applied by using
the tf.data.Dataset.interleave method, which takes a function that returns a dataset for each input element, and a number of parallel calls3
Set the prefetch option equal to the training batch size. The prefetch option allows you to prefetch the next batch of data while the current batch is being processed by the model. This can reduce the latency between batches and improve the throughput of the model training. The prefetch option can be applied by using the tf.data.Dataset.prefetch method, which takes a buffer size argument. The buffer size should be equal to the training batch size, which is the number of examples per batch4. The other options are not effective or counterproductive. Reducing the value of the repeat parameter will reduce the number of epochs, which is the number of times the model sees the entire dataset. This can affect the model’s accuracy and convergence. Increasing the buffer size for the shuffle option will increase the randomness of the data, but also increase the memory usage and the data loading time. Decreasing the batch size argument in your transformation will reduce the number of examples per batch, which can affect the model’s stability and performance.
Reference: 1: tf.data: Build TensorFlow input pipelines 2: Cloud TPU Tools in TensorBoard 3: tf.data.Dataset.interleave 4: tf.data.Dataset.prefetch: [Better performance with the tf.data API]
You work at a subscription-based company. You have trained an ensemble of trees and neural networks to predict customer churn, which is the likelihood that customers will not renew their yearly subscription. The average prediction is a 15% churn rate, but for a particular customer the model predicts that they are 70% likely to churn. The customer has a product usage history of 30%, is located in New York City, and became a customer in 1997. You need to explain the difference between the actual prediction, a 70% churn rate, and the average prediction. You want to use Vertex Explainable AI.
What should you do?
- A . Train local surrogate models to explain individual predictions.
- B . Configure sampled Shapley explanations on Vertex Explainable AI.
- C . Configure integrated gradients explanations on Vertex Explainable AI.
- D . Measure the effect of each feature as the weight of the feature multiplied by the feature value.
B
Explanation:
Option A is incorrect because training local surrogate models to explain individual predictions is not a feature of Vertex Explainable AI, but rather a general technique for interpreting black-box models. Local surrogate models are simpler models that approximate the behavior of the original model around a specific input1.
Option B is correct because configuring sampled Shapley explanations on Vertex Explainable AI is a way to explain the difference between the actual prediction and the average prediction for a given input. Sampled Shapley explanations are based on the Shapley value, which is a game-theoretic concept that measures how much each feature contributes to the prediction2. Vertex Explainable AI supports sampled Shapley explanations for tabular data, such as customer churn3.
Option C is incorrect because configuring integrated gradients explanations on Vertex Explainable AI is not suitable for explaining the difference between the actual prediction and the average prediction for a given input. Integrated gradients explanations are based on the idea of computing the gradients of the prediction with respect to the input features along a path from a baseline input to the actual input4. Vertex Explainable AI supports integrated gradients explanations for image and text data, but not for tabular data3.
Option D is incorrect because measuring the effect of each feature as the weight of the feature multiplied by the feature value is not a valid way to explain the difference between the actual prediction and the average prediction for a given input. This method assumes that the model is linear and additive, which is not the case for an ensemble of trees and neural networks. Moreover, this method does not account for the interactions between features or the non-linearity of the model5.
Reference: Local surrogate models
Shapley value
Vertex Explainable AI overview
Integrated gradients
Feature importance
While performing exploratory data analysis on a dataset, you find that an important categorical feature has 5% null values. You want to minimize the bias that could result from the missing values.
How should you handle the missing values?
- A . Remove the rows with missing values, and upsample your dataset by 5%.
- B . Replace the missing values with the feature’s mean.
- C . Replace the missing values with a placeholder category indicating a missing value.
- D . Move the rows with missing values to your validation dataset.
C
Explanation:
The best option for handling missing values in a categorical feature is to replace them with a placeholder category indicating a missing value. This is a type of imputation, which is a method of estimating the missing values based on the observed data. Imputing the missing values with a placeholder category preserves the information that the data is missing, and avoids introducing bias or distortion in the feature distribution. It also allows the machine learning model to learn from the missingness pattern, and potentially use it as a predictor for the target variable.
The other options are not suitable for handling missing values in a categorical feature, because:
Removing the rows with missing values and upsampling the dataset by 5% would reduce the size of the dataset and potentially lose important information. It would also introduce sampling bias and overfitting, as the upsampling process would create duplicate or synthetic observations that do not reflect the true population.
Replacing the missing values with the feature’s mean would not make sense for a categorical feature, as the mean is a numerical measure that does not capture the mode or frequency of the categories. It would also create a new category that does not exist in the original data, and might confuse the machine learning model.
Moving the rows with missing values to the validation dataset would compromise the validity and reliability of the model evaluation, as the validation dataset would not be representative of the test or production data. It would also reduce the amount of data available for training the model, and might introduce leakage or inconsistency between the training and validation datasets.
Reference: Imputation of missing values
Effective Strategies to Handle Missing Values in Data Analysis How to Handle Missing Values of Categorical Variables? Google Cloud launches machine learning engineer certification Google Professional Machine Learning Engineer Certification Professional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate