
Google Professional Cloud Developer Practice Exams
Last updated on Oct 24,2026- Exam Code: Professional Cloud Developer
- Exam Name: Professional Cloud Developer
- Certification Provider: Google
- Latest update: Oct 24,2026
Your team is setting up a build pipeline for an application that will run in Google Kubernetes Engine (GKE). For security reasons, you only want images produced by the pipeline to be deployed to your GKE cluster.
Which combination of Google Cloud services should you use?
- A . Google Cloud Deploy. Artifact Registry, and Google Cloud Armor
- B . Google Cloud Deploy, Cloud Storage and Google Cloud Armor
- C . Cloud Build, Cloud Storage, and Binary Authorization
- D . Cloud Build. Artifact Registry and Binary Authorization
You recently developed a new service on Cloud Run. The new service authenticates using a custom service and then writes transactional information to a Cloud Spanner database. You need to verify that your application can support up to 5,000 read and 1,000 write transactions per second while identifying any bottlenecks that occur. Your test infrastructure must be able to autoscale.
What should you do?
- A . Build a test harness to generate requests and deploy it to Cloud Run. Analyze the VPC Flow Logs using Cloud Logging.
- B . Create a Google Kubernetes Engine cluster running the Locust or JMeter images to dynamically generate load tests. Analyze the results using Cloud Trace.
- C . Create a Cloud Task to generate a test load. Use Cloud Scheduler to run 60,000 Cloud Task transactions per minute for 10 minutes. Analyze the results using Cloud Monitoring.
- D . Create a Compute Engine instance that uses a LAMP stack image from the Marketplace, and use Apache Bench to generate load tests against the service. Analyze the results using Cloud Trace.
B
Explanation:
https://cloud.google.com/architecture/distributed-load-testing-using-gke
You are writing a single-page web application with a user-interface that communicates with a third-party API for content using XMLHttpRequest. The data displayed on the UI by the API results is less critical than other data displayed on the same web page, so it is acceptable for some requests to not have the API data displayed in the UI. However, calls made to the API should not delay rendering of other parts of the user interface. You want your application to perform well when the API response is an error or a timeout.
What should you do?
- A . Set the asynchronous option for your requests to the API to false and omit the widget displaying the API results when a timeout or error is encountered.
- B . Set the asynchronous option for your request to the API to true and omit the widget displaying the API results when a timeout or error is encountered.
- C . Catch timeout or error exceptions from the API call and keep trying with exponential backoff until the API response is successful.
- D . Catch timeout or error exceptions from the API call and display the error response in the UI widget.
You are developing an ecommerce application that stores customer, order, and inventory data as relational tables inside Cloud Spanner. During a recent load test, you discover that Spanner performance is not scaling linearly as expected.
Which of the following is the cause?
- A . The use of 64-bit numeric types for 32-bit numbers.
- B . The use of the STRING data type for arbitrary-precision values.
- C . The use of Version 1 UUIDs as primary keys that increase monotonically.
- D . The use of LIKE instead of STARTS_WITH keyword for parameterized SQL queries.
You are developing a new public-facing application that needs to retrieve specific properties in the metadata of users’ objects in their respective Cloud Storage buckets. Due to privacy and data residency requirements, you must retrieve only the metadata and not the object data. You want to maximize the performance of the retrieval process.
How should you retrieve the metadata?
- A . Use the patch method.
- B . Use the compose method.
- C . Use the copy method.
- D . Use the fields request parameter.
D
Explanation:
https://cloud.google.com/storage/docs/json_api/v1/objects/get
You are creating an App Engine application that writes a file to any user’s Google Drive.
How should the application authenticate to the Google Drive API?
- A . With an OAuth Client ID that uses the https://www.googleapis.com/auth/drive.file scope to obtain an access token for each user.
- B . With an OAuth Client ID with delegated domain-wide authority.
- C . With the App Engine service account and https://www.googleapis.com/auth/drive.file scope that generates a signed JWT.
- D . With the App Engine service account with delegated domain-wide authority.
B
Explanation:
Reference: https://developers.google.com/drive/api/v3/about-auth
You are trying to connect to your Google Kubernetes Engine (GKE) cluster using kubectl from Cloud Shell. You have deployed your GKE cluster with a public endpoint.
From Cloud Shell, you run the following command:
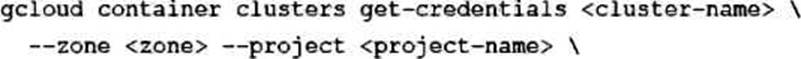
You notice that the kubectl commands time out without returning an error message.
What is the most likely cause of this issue?
- A . Your user account does not have privileges to interact with the cluster using kubectl.
- B . Your Cloud Shell external IP address is not part of the authorized networks of the cluster.
- C . The Cloud Shell is not part of the same VPC as the GKE cluster.
- D . A VPC firewall is blocking access to the cluster’s endpoint.
B
Explanation:
https://cloud.google.com/kubernetes-engine/docs/how-to/private-clusters#cloud_shell
If you want to use Cloud Shell to access the cluster, you must add the public IP address of your Cloud Shell to the cluster’s list of authorized networks.
You are deploying your applications on Compute Engine. One of your Compute Engine instances failed to launch.
What should you do? (Choose two.)
- A . Determine whether your file system is corrupted.
- B . Access Compute Engine as a different SSH user.
- C . Troubleshoot firewall rules or routes on an instance.
- D . Check whether your instance boot disk is completely full.
- E . Check whether network traffic to or from your instance is being dropped.
AD
Explanation:
https://cloud.google.com/compute/docs/troubleshooting/vm-startup