
Google Professional Cloud Developer Practice Exams
Last updated on Oct 24,2026- Exam Code: Professional Cloud Developer
- Exam Name: Professional Cloud Developer
- Certification Provider: Google
- Latest update: Oct 24,2026
You are building a CI/CD pipeline that consists of a version control system, Cloud Build, and Container Registry. Each time a new tag is pushed to the repository, a Cloud Build job is triggered, which runs unit tests on the new code builds a new Docker container image, and pushes it into Container Registry. The last step of your pipeline should deploy the new container to your production Google Kubernetes Engine (GKE) cluster.
You need to select a tool and deployment strategy that meets the following requirements:
• Zero downtime is incurred
• Testing is fully automated
• Allows for testing before being rolled out to users
• Can quickly rollback if needed
What should you do?
- A . Trigger a Spinnaker pipeline configured as an A/B test of your new code and, if it is successful, deploy the container to production.
- B . Trigger a Spinnaker pipeline configured as a canary test of your new code and, if it is successful, deploy the container to production.
- C . Trigger another Cloud Build job that uses the Kubernetes CLI tools to deploy your new container to your GKE cluster, where you can perform a canary test.
- D . Trigger another Cloud Build job that uses the Kubernetes CLI tools to deploy your new container to your GKE cluster, where you can perform a shadow test.
D
Explanation:
https://cloud.google.com/architecture/implementing-deployment-and-testing-strategies-on-gke#perform_a_shadow_test With a shadow test, you test the new version of your application by mirroring user traffic from the current application version without impacting the user requests.
You deployed a new application to Google Kubernetes Engine and are experiencing some performance degradation. Your logs are being written to Cloud Logging, and you are using a Prometheus sidecar model for capturing metrics. You need to correlate the metrics and data from the logs to troubleshoot the performance issue and send real-time alerts while minimizing costs.
What should you do?
- A . Create custom metrics from the Cloud Logging logs, and use Prometheus to import the results using the Cloud Monitoring REST API.
- B . Export the Cloud Logging logs and the Prometheus metrics to Cloud Bigtable. Run a query to join the results, and analyze in Google Data Studio.
- C . Export the Cloud Logging logs and stream the Prometheus metrics to BigQuery. Run a recurring query to join the results, and send notifications using Cloud Tasks.
- D . Export the Prometheus metrics and use Cloud Monitoring to view them as external metrics. Configure Cloud Monitoring to create log-based metrics from the logs, and correlate them with the Prometheus data.
D
Explanation:
Reference: https://cloud.google.com/blog/products/operations/troubleshoot-gke-faster-with-monitoring-data-in-your-logs
You are using Cloud Run to host a global ecommerce web application. Your company’s design team is creating a new color scheme for the web app. You have been tasked with determining whether the new color scheme will increase sales You want to conduct testing on live production traffic.
How should you design the study?
- A . Use an external HTTP(S) load balancer to route a predetermined percentage of traffic to two different color schemes of your application Analyze the results to determine whether there is a statistically significant difference in sales.
- B . Use an external HTTP(S) load balancer to route traffic to the original color scheme while the new deployment is created and tested After testing is complete reroute all traffic to the new color scheme Analyze the results to determine whether there is a statistically significant difference in sales.
- C . Enable a feature flag that displays the new color scheme to half of all users. Monitor sales to see whether they increase for this group of users.
- D . Use an external HTTP(S) load balancer to mirror traffic to the new version of your application Analyze the results to determine whether there is a statistically significant difference in sales.
You are creating a Google Kubernetes Engine (GKE) cluster and run this command:
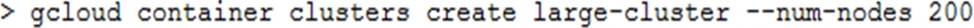
The command fails with the error:

You want to resolve the issue.
What should you do?
- A . Request additional GKE quota is the GCP Console.
- B . Request additional Compute Engine quota in the GCP Console.
- C . Open a support case to request additional GKE quotA.
- D . Decouple services in the cluster, and rewrite new clusters to function with fewer cores.
You are developing a JPEG image-resizing API hosted on Google Kubernetes Engine (GKE). Callers of the service will exist within the same GKE cluster. You want clients to be able to get the IP address of the service.
What should you do?
- A . Define a GKE Service. Clients should use the name of the A record in Cloud DNS to find the service’s
cluster IP address. - B . Define a GKE Service. Clients should use the service name in the URL to connect to the service.
- C . Define a GKE Endpoint. Clients should get the endpoint name from the appropriate environment variable in
the client container. - D . Define a GKE Endpoint. Clients should get the endpoint name from Cloud DNS.
You are planning to deploy hundreds of microservices in your Google Kubernetes Engine (GKE) cluster.
How should you secure communication between the microservices on GKE using a managed service?
- A . Use global HTTP(S) Load Balancing with managed SSL certificates to protect your services
- B . Deploy open source Istio in your GKE cluster, and enable mTLS in your Service Mesh
- C . Install cert-manager on GKE to automatically renew the SSL certificates.
- D . Install Anthos Service Mesh, and enable mTLS in your Service Mesh.
D
Explanation:
https://cloud.google.com/service-mesh/docs/overview#security_benefits
– Ensures encryption in transit. Using mTLS for authentication also ensures that all TCP communications are encrypted in transit.
You need to load-test a set of REST API endpoints that are deployed to Cloud Run. The API responds to HTTP POST requests.
Your load tests must meet the following requirements:
• Load is initiated from multiple parallel threads
• User traffic to the API originates from multiple source IP addresses.
• Load can be scaled up using additional test instances
You want to follow Google-recommended best practices
How should you configure the load testing’?
- A . Create an image that has cURL installed and configure cURLto run a test plan Deploy the image in a
managed instance group, and run one instance of the image for each VM. - B . Create an image that has cURL installed and configure cURL to run a test plan Deploy the image in an
unmanaged instance group, and run one instance of the image for each VM. - C . Deploy a distributed load testing framework on a private Google Kubernetes Engine Cluster Deploy
additional Pods as needed to initiate more traffic and support the number of concurrent users. - D . Download the container image of a distributed load testing framework on Cloud Shell Sequentially start
several instances of the container on Cloud Shell to increase the load on the API.
The new version of your containerized application has been tested and is ready to deploy to production on Google Kubernetes Engine. You were not able to fully load-test the new version in pre-production environments, and you need to make sure that it does not have performance problems once deployed. Your deployment must be automated.
What should you do?
- A . Use Cloud Load Balancing to slowly ramp up traffic between versions. Use Cloud Monitoring to look for performance issues.
- B . Deploy the application via a continuous delivery pipeline using canary deployments. Use Cloud Monitoring to look for performance issues. and ramp up traffic as the metrics support it.
- C . Deploy the application via a continuous delivery pipeline using blue/green deployments. Use Cloud Monitoring to look for performance issues, and launch fully when the metrics support it.
- D . Deploy the application using kubectl and set the spec.updateStrategv.type to RollingUpdate. Use Cloud Monitoring to look for performance issues, and run the kubectl rollback command if there are any issues.
C
Explanation:
https://cloud.google.com/architecture/implementing-deployment-and-testing-strategies-on-gke#perform_a_bluegreen_deployment
You work for an organization that manages an online ecommerce website. Your company plans to expand across the world; however, the estore currently serves one specific region. You need to select a SQL database and configure a schema that will scale as your organization grows. You want to create a table that stores all customer transactions and ensure that the customer (CustomerId) and the transaction (TransactionId) are unique.
What should you do?
- A . Create a Cloud SQL table that has TransactionId and CustomerId configured as primary keys. Use an incremental number for the TransactionId.
- B . Create a Cloud SQL table that has TransactionId and CustomerId configured as primary keys. Use a random string (UUID) for the Transactionid.
- C . Create a Cloud Spanner table that has TransactionId and CustomerId configured as primary keys.
Use a random string (UUID) for the TransactionId. - D . Create a Cloud Spanner table that has TransactionId and CustomerId configured as primary keys.
Use an incremental number for the TransactionId.