
Databricks Databricks Machine Learning Associate Practice Exams
Last updated on Oct 21,2026- Exam Code: Databricks Machine Learning Associate
- Exam Name: Databricks Certified Machine Learning Associate Exam
- Certification Provider: Databricks
- Latest update: Oct 21,2026
A machine learning engineer is trying to scale a machine learning pipeline pipeline that contains multiple feature engineering stages and a modeling stage.
As part of the cross-validation process, they are using the following code block:
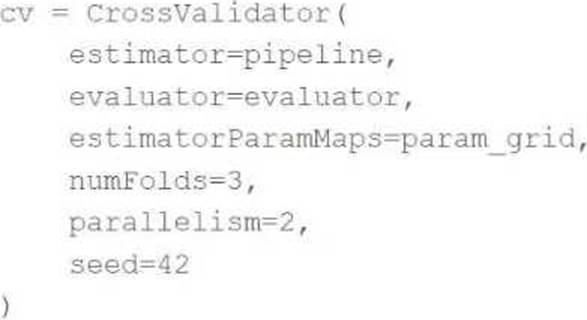
A colleague suggests that the code block can be changed to speed up the tuning process by passing the model object to the estimator parameter and then placing the updated cv object as the final stage of the pipeline in place of the original model.
Which of the following is a negative consequence of the approach suggested by the colleague?
- A . The model will take longer to train for each unique combination of hvperparameter values
- B . The feature engineering stages will be computed using validation data
- C . The cross-validation process will no longer be
- D . The cross-validation process will no longer be reproducible
- E . The model will be refit one more per cross-validation fold
A data scientist is working with a feature set with the following schema:
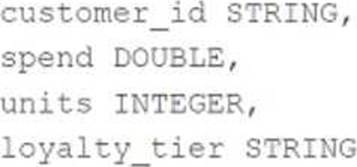
The customer_id column is the primary key in the feature set. Each of the columns in the feature set has missing values. They want to replace the missing values by imputing a common value for each feature.
Which of the following lists all of the columns in the feature set that need to be imputed using the most common value of the column?
- A . customer_id, loyalty_tier
- B . loyalty_tier
- C . units
- D . spend
- E . customer_id
Which of the following is a benefit of using vectorized pandas UDFs instead of standard PySpark UDFs?
- A . The vectorized pandas UDFs allow for the use of type hints
- B . The vectorized pandas UDFs process data in batches rather than one row at a time
- C . The vectorized pandas UDFs allow for pandas API use inside of the function
- D . The vectorized pandas UDFs work on distributed DataFrames
- E . The vectorized pandas UDFs process data in memory rather than spilling to disk
A data scientist has created two linear regression models. The first model uses price as a label variable and the second model uses log(price) as a label variable. When evaluating the RMSE of each model by comparing the label predictions to the actual price values, the data scientist notices that the RMSE for the second model is much larger than the RMSE of the first model.
Which of the following possible explanations for this difference is invalid?
- A . The second model is much more accurate than the first model
- B . The data scientist failed to exponentiate the predictions in the second model prior to computing the RMSE
- C . The data scientist failed to take the log of the predictions in the first model prior to computing the RMSE
- D . The first model is much more accurate than the second model
- E . The RMSE is an invalid evaluation metric for regression problems
A data scientist has a Spark DataFrame spark_df. They want to create a new Spark DataFrame that contains only the rows from spark_df where the value in column price is greater than 0.
Which of the following code blocks will accomplish this task?
- A . spark_df[spark_df["price"] > 0]
- B . spark_df.filter(col("price") > 0)
- C . SELECT * FROM spark_df WHERE price > 0
- D . spark_df.loc[spark_df["price"] > 0,:]
- E . spark_df.loc[:,spark_df["price"] > 0]
A machine learning engineer is trying to perform batch model inference. They want to get predictions using the linear regression model saved at the path model_uri for the DataFrame batch_df.
batch_df has the following schema:
customer_id STRING
The machine learning engineer runs the following code block to perform inference on batch_df using the linear regression model at model_uri:
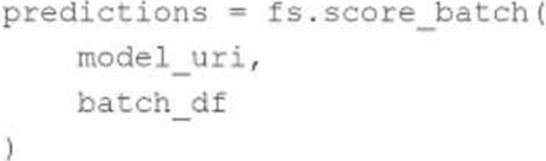
In which situation will the machine learning engineer’s code block perform the desired inference?
- A . When the Feature Store feature set was logged with the model at model_uri
- B . When all of the features used by the model at model_uri are in a Spark DataFrame in the PySpark
- C . When the model at model_uri only uses customer_id as a feature
- D . This code block will not perform the desired inference in any situation.
- E . When all of the features used by the model at model_uri are in a single Feature Store table