
Databricks Databricks Certified Data Engineer Professional Practice Exams
Last updated on Oct 22,2026- Exam Code: Databricks Certified Data Engineer Professional
- Exam Name: Databricks Certified Data Engineer Professional Exam
- Certification Provider: Databricks
- Latest update: Oct 22,2026
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods.
The fields required to populate this dashboard have the following schema:
For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated ncrementally in near real-time. This table named products_per_order, includes the following fields:
Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A . Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
- B . Populate the dashboard by configuring a nightly batch job to save the required to quickly update the dashboard with each query.
- C . Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
- D . Define a view against the products_per_order table and define the dashboard against this view.
A Delta Lake table was created with the below query:
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A . The table reference in the metastore is updated and no data is changed.
- B . The table name change is recorded in the Delta transaction log.
- C . All related files and metadata are dropped and recreated in a single ACID transaction.
- D . The table reference in the metastore is updated and all data files are moved.
- E . A new Delta transaction log Is created for the renamed table.
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job. They attempt to transfer "Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
- A . Databricks jobs must have exactly one owner; "Owner" privileges cannot be assigned to a group.
- B . The creator of a Databricks job will always have "Owner" privileges; this configuration cannot be changed.
- C . Other than the default "admins" group, only individual users can be granted privileges on jobs.
- D . A user can only transfer job ownership to a group if they are also a member of that group.
- E . Only workspace administrators can grant "Owner" privileges to a group.
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source. That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
- A . The Delta log and Structured Streaming checkpoints record the full history of the Kafka producer.
- B . Delta Lake schema evolution can retroactively calculate the correct value for newly added fields, as long as the data was in the original source.
- C . Delta Lake automatically checks that all fields present in the source data are included in the ingestion layer.
- D . Data can never be permanently dropped or deleted from Delta Lake, so data loss is not possible under any circumstance.
- E . Ingestine all raw data and metadata from Kafka to a bronze Delta table creates a permanent, replayable history of the data state.
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A . Regex
- B . Julia
- C . pyspsark.ml.feature
- D . Scala Datasets
- E . C++
The data governance team is reviewing code used for deleting records for compliance with GDPR.
They note the following logic is used to delete records from the Delta Lake table named users.
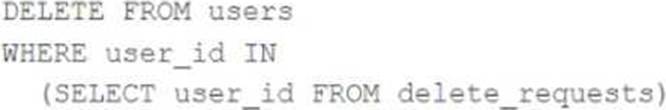
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A . Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- B . No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- C . Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- D . No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- E . No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.
A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production data. Because all users have Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.
Which statement captures best practices for this situation?
- A . Because access to production data will always be verified using passthrough credentials it is safe to mount data to any Databricks development environment.
- B . All developer, testing and production code and data should exist in a single unified workspace; creating separate environments for testing and development further reduces risks.
- C . In environments where interactive code will be executed, production data should only be accessible with read permissions; creating isolated databases for each environment further reduces risks.
- D . Because delta Lake versions all data and supports time travel, it is not possible for user error or malicious actors to permanently delete production data, as such it is generally safe to mount production data anywhere.
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
- A . Stage’s detail screen and Executor’s files
- B . Stage’s detail screen and Query’s detail screen
- C . Driver’s and Executor’s log files
- D . Executor’s detail screen and Executor’s log files
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake’s time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
- A . Because the vacuum command permanently deletes all files containing deleted records, deleted records may be accessible with time travel for around 24 hours.
- B . Because the default data retention threshold is 24 hours, data files containing deleted records will be retained until the vacuum job is run the following day.
- C . Because Delta Lake time travel provides full access to the entire history of a table, deleted records can always be recreated by users with full admin privileges.
- D . Because Delta Lake’s delete statements have ACID guarantees, deleted records will be permanently purged from all storage systems as soon as a delete job completes.
- E . Because the default data retention threshold is 7 days, data files containing deleted records will be retained until the vacuum job is run 8 days later.
A nightly job ingests data into a Delta Lake table using the following code:
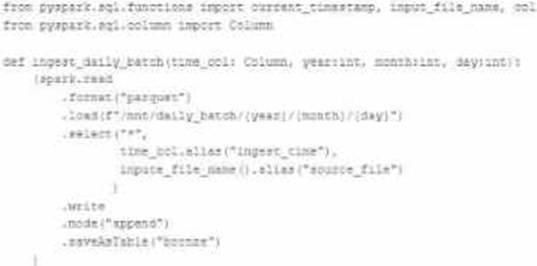
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
A) def new_records():
B) return spark.readStream.table("bronze")
C) return spark.readStream.load("bronze")
D) return spark.read.option("readChangeFeed", "true").table ("bronze")
E)
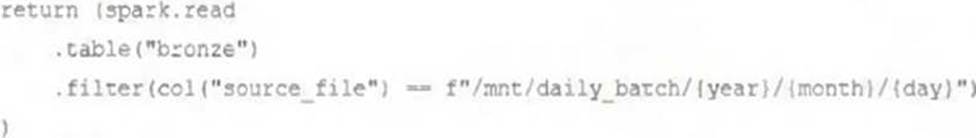
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E