
Databricks Databricks Certified Data Engineer Professional Practice Exams
Last updated on Oct 22,2026- Exam Code: Databricks Certified Data Engineer Professional
- Exam Name: Databricks Certified Data Engineer Professional Exam
- Certification Provider: Databricks
- Latest update: Oct 22,2026
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of 512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
- A . Set spark.sql.files.maxPartitionBytes to 512 MB, ingest the data, execute the narrow transformations, and then write to parquet.
- B . Set spark.sql.shuffle.partitions to 2,048 partitions (1TB*1024*1024/512), ingest the data, execute the narrow transformations, optimize the data by sorting it (which automatically repartitions the data), and then write to parquet.
- C . Set spark.sql.adaptive.advisoryPartitionSizeInBytes to 512 MB bytes, ingest the data, execute the narrow transformations, coalesce to 2,048 partitions (1TB*1024*1024/512), and then write to parquet.
- D . Ingest the data, execute the narrow transformations, repartition to 2,048 partitions (1TB* 1024*1024/512), and then write to parquet.
- E . Set spark.sql.shuffle.partitions to 512, ingest the data, execute the narrow transformations, and then write to parquet.
A developer has successfully configured credential for Databricks Repos and cloned a remote Git repository. Hey don not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace.
Use Response to pull changes from the remote Git repository commit and push changes to a branch that appeared as a changes were pulled.
- A . Use Repos to merge all differences and make a pull request back to the remote repository.
- B . Use repos to merge all difference and make a pull request back to the remote repository.
- C . Use Repos to create a new branch commit all changes and push changes to the remote Git repertory.
- D . Use repos to create a fork of the remote repository commit all changes and make a pull request on the source repository
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
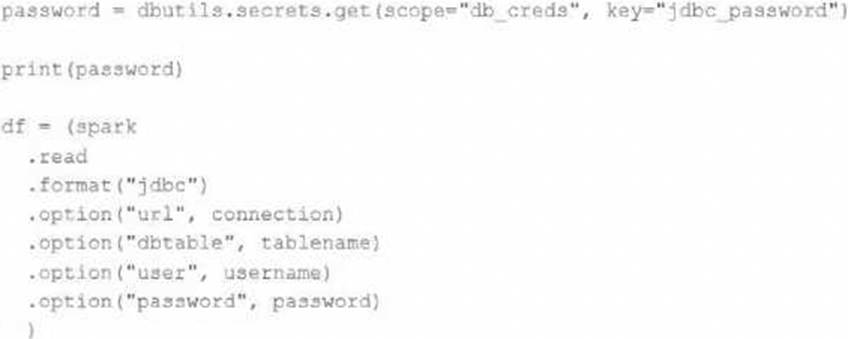
Which statement describes what will happen when the above code is executed?
- A . The connection to the external table will fail; the string "redacted" will be printed.
- B . An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- C . An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- D . The connection to the external table will succeed; the string value of password will be printed in plain text.
- E . The connection to the external table will succeed; the string "redacted" will be printed.
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
- A . Task queueing resulting from improper thread pool assignment.
- B . Spill resulting from attached volume storage being too small.
- C . Network latency due to some cluster nodes being in different regions from the source data
- D . Skew caused by more data being assigned to a subset of spark-partitions.
- E . Credential validation errors while pulling data from an external system.
Which statement describes the default execution mode for Databricks Auto Loader?
- A . New files are identified by listing the input directory; new files are incrementally and idempotently
loaded into the target Delta Lake table. - B . Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C . Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- D . New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
- A . Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until all tasks have successfully been completed.
- B . Tasks B and C will attempt to run as configured; any changes made in task A will be rolled back due to task failure.
- C . Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task A failed, all commits will be rolled back automatically.
- D . Tasks B and C will be skipped; some logic expressed in task A may have been committed before task failure.
- E . Tasks B and C will be skipped; task A will not commit any changes because of stage failure.
A nightly job ingests data into a Delta Lake table using the following code:
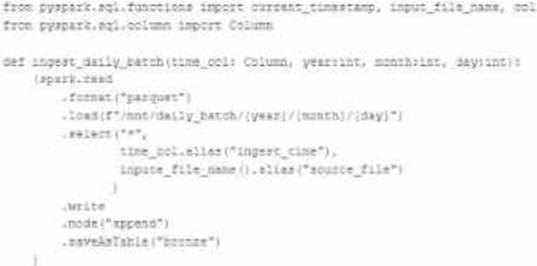
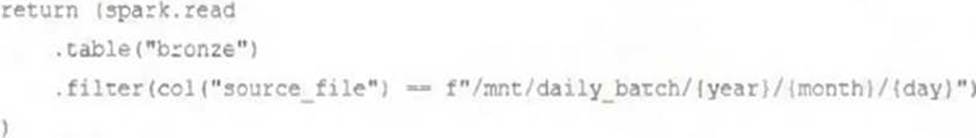
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
A) def new_records():
B) return spark.readStream.table("bronze")
C) return spark.readStream.load("bronze")
D) return spark.read.option("readChangeFeed", "true").table ("bronze")
E)
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
Which of the following is true of Delta Lake and the Lakehouse?
- A . Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
- B . Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
- C . Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- D . Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- E . Z-order can only be applied to numeric values stored in Delta Lake tables
A Databricks SQL dashboard has been configured to monitor the total number of records present in a collection of Delta Lake tables using the following query pattern:
SELECT COUNT (*) FROM table –
Which of the following describes how results are generated each time the dashboard is updated?
- A . The total count of rows is calculated by scanning all data files
- B . The total count of rows will be returned from cached results unless REFRESH is run
- C . The total count of records is calculated from the Delta transaction logs
- D . The total count of records is calculated from the parquet file metadata
- E . The total count of records is calculated from the Hive metastore
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
- A . configure
- B . fs
- C . jobs
- D . libraries
- E . workspace