
Amazon MLS-C01 Practice Exams
Last updated on Oct 23,2026- Exam Code: MLS-C01
- Exam Name: AWS Certified Machine Learning - Specialty
- Certification Provider: Amazon
- Latest update: Oct 23,2026
A data scientist must build a custom recommendation model in Amazon SageMaker for an online retail company. Due to the nature of the company’s products, customers buy only 4-5 products every 5-10 years. So, the company relies on a steady stream of new customers. When a new customer signs up, the company collects data on the customer’s preferences.
Below is a sample of the data available to the data scientist.
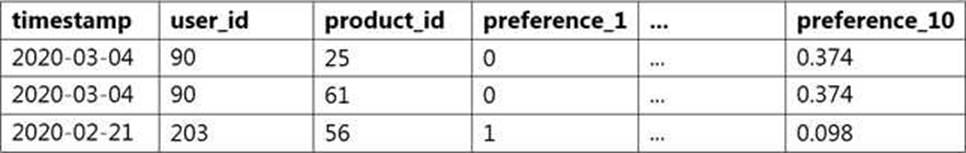
How should the data scientist split the dataset into a training and test set for this use case?
- A . Shuffle all interaction data. Split off the last 10% of the interaction data for the test set.
- B . Identify the most recent 10% of interactions for each user. Split off these interactions for the test set.
- C . Identify the 10% of users with the least interaction data. Split off all interaction data from these users for the test set.
- D . Randomly select 10% of the users. Split off all interaction data from these users for the test set.
D
Explanation:
The best way to split the dataset into a training and test set for this use case is to randomly select 10% of the users and split off all interaction data from these users for the test set. This is because the company relies on a steady stream of new customers, so the test set should reflect the behavior of new customers who have not been seen by the model before. The other options are not suitable because they either mix old and new customers in the test set (A and B), or they bias the test set towards users with less interaction data ©.
References:
Amazon SageMaker Developer Guide: Train and Test Datasets
Amazon Personalize Developer Guide: Preparing and Importing Data
A company wants to create an artificial intelligence (Al) yoga instructor that can lead large classes of students. The company needs to create a feature that can accurately count the number of students who are in a class. The company also needs a feature that can differentiate students who are performing a yoga stretch correctly from students who are performing a stretch incorrectly.
…etermine whether students are performing a stretch correctly, the solution needs to measure the location and angle of each student’s arms and legs A data scientist must use Amazon SageMaker to …ss video footage of a yoga class by extracting image frames and applying computer vision models.
Which combination of models will meet these requirements with the LEAST effort? (Select TWO.)
- A . Image Classification
- B . Optical Character Recognition (OCR)
- C . Object Detection
- D . Pose estimation
- E . Image Generative Adversarial Networks (GANs)
CD
Explanation:
To count the number of students who are in a class, the solution needs to detect and locate each student in the video frame. Object detection is a computer vision model that can identify and locate multiple objects in an image. To differentiate students who are performing a stretch correctly from students who are performing a stretch incorrectly, the solution needs to measure the location and angle of each student’s arms and legs. Pose estimation is a computer vision model that can estimate the pose of a person by detecting the position and orientation of key body parts. Image classification, OCR, and image GANs are not relevant for this use case.
References:
Object Detection: A computer vision technique that identifies and locates objects within an image or video.
Pose Estimation: A computer vision technique that estimates the pose of a person by detecting the position and orientation of key body parts.
Amazon SageMaker: A fully managed service that provides every developer and data scientist with the ability to build, train, and deploy machine learning (ML) models quickly.
A Machine Learning Specialist needs to move and transform data in preparation for training Some of the data needs to be processed in near-real time and other data can be moved hourly There are existing Amazon EMR MapReduce jobs to clean and feature engineering to perform on the data.
Which of the following services can feed data to the MapReduce jobs? (Select TWO )
- A . AWSDMS
- B . Amazon Kinesis
- C . AWS Data Pipeline
- D . Amazon Athena
- E . Amazon ES
B, C
Explanation:
Amazon Kinesis and AWS Data Pipeline are two services that can feed data to the Amazon EMR MapReduce jobs. Amazon Kinesis is a service that can ingest, process, and analyze streaming data in real time. Amazon Kinesis can be integrated with Amazon EMR to run MapReduce jobs on streaming data sources, such as web logs, social media, IoT devices, and clickstreams. Amazon Kinesis can handle data that needs to be processed in near-real time, such as for anomaly detection, fraud detection, or dashboarding. AWS Data Pipeline is a service that can orchestrate and automate data movement and transformation across various AWS services and on-premises data sources. AWS Data Pipeline can be integrated with Amazon EMR to run MapReduce jobs on batch data sources, such as Amazon S3, Amazon RDS, Amazon DynamoDB, and Amazon Redshift. AWS Data Pipeline can handle data that can be moved hourly, such as for data warehousing, reporting, or machine learning. AWSDMS is not a valid service name. AWS Database Migration Service (AWS DMS) is a service that can migrate data from various sources to various targets, but it does not support streaming data or MapReduce jobs.
Amazon Athena is a service that can query data stored in Amazon S3 using standard SQL, but it does not feed data to Amazon EMR or run MapReduce jobs.
Amazon ES is a service that provides a fully managed Elasticsearch cluster, which can be used for search, analytics, and visualization, but it does not feed data to Amazon EMR or run MapReduce jobs.
References:
Using Amazon Kinesis with Amazon EMR – Amazon EMR
AWS Data Pipeline – Amazon Web Services
Using AWS Data Pipeline to Run Amazon EMR Jobs – AWS Data Pipeline
A monitoring service generates 1 TB of scale metrics record data every minute A Research team performs queries on this data using Amazon Athena. The queries run slowly due to the large volume of data, and the team requires better performance
How should the records be stored in Amazon S3 to improve query performance?
- A . CSV files
- B . Parquet files
- C . Compressed JSON
- D . RecordIO
B
Explanation:
Parquet is a columnar storage format that can store data in a compressed and efficient way. Parquet files can improve query performance by reducing the amount of data that needs to be scanned, as only the relevant columns are read from the files. Parquet files can also support predicate pushdown, which means that the filtering conditions are applied at the storage level, further reducing the data that needs to be processed. Parquet files are compatible with Amazon Athena, which can leverage the benefits of the columnar format and provide faster and cheaper queries. Therefore, the records should be stored in Parquet files in Amazon S3 to improve query performance.
References:
Columnar Storage Formats – Amazon Athena
Parquet SerDe – Amazon Athena
Optimizing Amazon Athena Queries – Amazon Athena
Parquet – Apache Software Foundation
A Machine Learning Specialist working for an online fashion company wants to build a data ingestion solution for the company’s Amazon S3-based data lake.
The Specialist wants to create a set of ingestion mechanisms that will enable future capabilities comprised of:
• Real-time analytics
• Interactive analytics of historical data
• Clickstream analytics
• Product recommendations
Which services should the Specialist use?
- A . AWS Glue as the data dialog; Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for real-time data insights; Amazon Kinesis Data Firehose for delivery to Amazon ES for clickstream analytics; Amazon EMR to generate personalized product recommendations
- B . Amazon Athena as the data catalog; Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for near-realtime data insights; Amazon Kinesis Data Firehose for clickstream analytics; AWS Glue to generate personalized product recommendations
- C . AWS Glue as the data catalog; Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for historical data insights; Amazon Kinesis Data Firehose for delivery to Amazon ES for clickstream analytics; Amazon EMR to generate personalized product recommendations
- D . Amazon Athena as the data catalog; Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for historical data insights; Amazon DynamoDB streams for clickstream analytics; AWS Glue to generate personalized product recommendations
A
Explanation:
The best services to use for building a data ingestion solution for the company’s Amazon S3-based data lake are:
AWS Glue as the data catalog: AWS Glue is a fully managed extract, transform, and load (ETL) service that can discover, crawl, and catalog data from various sources and formats, and make it available for analysis. AWS Glue can also generate ETL code in Python or Scala to transform, enrich, and join data using AWS Glue Data Catalog as the metadata repository. AWS Glue Data Catalog is a central metadata store that integrates with Amazon Athena, Amazon EMR, and Amazon Redshift Spectrum, allowing users to create a unified view of their data across various sources and formats.
Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for real-time data insights: Amazon Kinesis Data Streams is a service that enables users to collect, process, and analyze real-time streaming data at any scale. Users can create data streams that can capture data from various sources, such as web and mobile applications, IoT devices, and social media platforms. Amazon Kinesis Data Analytics is a service that allows users to analyze streaming data using standard SQL queries or Apache Flink applications. Users can create real-time dashboards, metrics, and alerts based on the streaming data analysis results.
Amazon Kinesis Data Firehose for delivery to Amazon ES for clickstream analytics: Amazon Kinesis Data Firehose is a service that enables users to load streaming data into data lakes, data stores, and analytics services. Users can configure Kinesis Data Firehose to automatically deliver data to various destinations, such as Amazon S3, Amazon Redshift, Amazon OpenSearch Service, and third-party solutions. For clickstream analytics, users can use Kinesis Data Firehose to deliver data to Amazon OpenSearch Service, a fully managed service that offers search and analytics capabilities for log data. Users can use Amazon OpenSearch Service to perform interactive analysis and visualization of clickstream data using Kibana, an open-source tool that is integrated with Amazon OpenSearch Service.
Amazon EMR to generate personalized product recommendations: Amazon EMR is a service that enables users to run distributed data processing frameworks, such as Apache Spark, Apache Hadoop, and Apache Hive, on scalable clusters of EC2 instances. Users can use Amazon EMR to perform advanced analytics, such as machine learning, on large and complex datasets stored in Amazon S3 or other sources. For product recommendations, users can use Amazon EMR to run Spark MLlib, a library that provides scalable machine learning algorithms, such as collaborative filtering, to generate personalized recommendations based on user behavior and preferences.
References:
AWS Glue – Fully Managed ETL Service
Amazon Kinesis – Data Streaming Service
Amazon OpenSearch Service – Managed OpenSearch Service Amazon EMR – Managed Hadoop Framework
An insurance company developed a new experimental machine learning (ML) model to replace an existing model that is in production. The company must validate the quality of predictions from the new experimental model in a production environment before the company uses the new experimental model to serve general user requests.
Which one model can serve user requests at a time. The company must measure the performance of the new experimental model without affecting the current live traffic.
Which solution will meet these requirements?
- A . A/B testing
- B . Canary release
- C . Shadow deployment
- D . Blue/green deployment
C
Explanation:
The best solution for this scenario is to use shadow deployment, which is a technique that allows the company to run the new experimental model in parallel with the existing model, without exposing it to the end users. In shadow deployment, the company can route the same user requests to both models, but only return the responses from the existing model to the users. The responses from the new experimental model are logged and analyzed for quality and performance metrics, such as accuracy, latency, and resource consumption12. This way, the company can validate the new experimental model in a production environment, without affecting the current live traffic or user experience.
The other solutions are not suitable, because they have the following drawbacks:
A: A/B testing is a technique that involves splitting the user traffic between two or more models, and comparing their outcomes based on predefined metrics. However, this technique exposes the new experimental model to a portion of the end users, which might affect their experience if the model is not reliable or consistent with the existing model3.
B: Canary release is a technique that involves gradually rolling out the new experimental model to a small subset of users, and monitoring its performance and feedback. However, this technique also exposes the new experimental model to some end users, and requires careful selection and segmentation of the user groups4.
D: Blue/green deployment is a technique that involves switching the user traffic from the existing model (blue) to the new experimental model (green) at once, after testing and verifying the new model in a separate environment. However, this technique does not allow the company to validate the new experimental model in a production environment, and might cause service disruption or inconsistency if the new model is not compatible or stable5.
References:
1: Shadow Deployment: A Safe Way to Test in Production | LaunchDarkly Blog
2: Shadow Deployment: A Safe Way to Test in Production | LaunchDarkly Blog
3: A/B Testing for Machine Learning Models | AWS Machine Learning Blog
4: Canary Releases for Machine Learning Models | AWS Machine Learning Blog
5: Blue-Green Deployments for Machine Learning Models | AWS Machine Learning Blog
A company has a podcast platform that has thousands of users. The company implemented an algorithm to detect low podcast engagement based on a 10-minute running window of user events such as listening to. pausing, and closing the podcast. A machine learning (ML) specialist is designing the ingestion process for these events. The ML specialist needs to transform the data to prepare the data for inference.
How should the ML specialist design the transformation step to meet these requirements with the LEAST operational effort?
- A . Use an Amazon Managed Streaming for Apache Kafka (Amazon MSK) cluster to ingest event data. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to transform the most recent 10 minutes of data before inference.
- B . Use Amazon Kinesis Data Streams to ingest event data. Store the data in Amazon S3 by using Amazon Data Firehose. Use AWS Lambda to transform the most recent 10 minutes of data before inference.
- C . Use Amazon Kinesis Data Streams to ingest event data. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to transform the most recent 10 minutes of data before inference.
- D . Use an Amazon Managed Streaming for Apache Kafka (Amazon MSK) cluster to ingest event data.
Use AWS Lambda to transform the most recent 10 minutes of data before inference.
C
Explanation:
In this scenario, Kinesis Data Streams efficiently ingests real-time event data, while Amazon Managed Service for Apache Flink (formerly Amazon Kinesis Data Analytics) is ideal for transforming and analyzing data in a continuous stream. Apache Flink allows processing of time-based windows, such as the 10-minute sliding window required here, with low operational overhead.
This combination provides an effective solution for low-latency data processing and transformation, meeting the requirements for preparing data for inference with minimal setup and serverless scalability.
A tourism company uses a machine learning (ML) model to make recommendations to customers. The company uses an Amazon SageMaker environment and set hyperparameter tuning completion criteria to MaxNumberOfTrainingJobs.
An ML specialist wants to change the hyperparameter tuning completion criteria. The ML specialist wants to stop tuning immediately after an internal algorithm determines that tuning job is unlikely to improve more than 1% over the objective metric from the best training job.
Which completion criteria will meet this requirement?
- A . MaxRuntimelnSeconds
- B . TargetObjectiveMetricValue
- C . CompleteOnConvergence
- D . MaxNumberOfTrainingJobsNotlmproving
C
Explanation:
In Amazon SageMaker, hyperparameter tuning jobs optimize model performance by adjusting hyperparameters. Amazon SageMaker’s hyperparameter tuning supports completion criteria settings that enable efficient management of tuning resources. In this scenario, the ML specialist aims to set a completion criterion that will terminate the tuning job as soon as SageMaker detects that further improvements in the objective metric are unlikely to exceed 1%.
The CompleteOnConvergence setting is designed for such requirements. This criterion enables the tuning job to automatically stop when SageMaker determines that additional hyperparameter evaluations are unlikely to improve the objective metric beyond a certain threshold, allowing for efficient tuning completion. The convergence process relies on an internal optimization algorithm that continuously evaluates the objective metric during tuning and stops when performance stabilizes without further improvement.
This is supported by AWS documentation, which explains that CompleteOnConvergence is an efficient way to manage tuning by stopping unnecessary evaluations once the model performance stabilizes within the specified threshold.
A network security vendor needs to ingest telemetry data from thousands of endpoints that run all over the world. The data is transmitted every 30 seconds in the form of records that contain 50 fields. Each record is up to 1 KB in size. The security vendor uses Amazon Kinesis Data Streams to ingest the data. The vendor requires hourly summaries of the records that Kinesis Data Streams ingests. The vendor will use Amazon Athena to query the records and to generate the summaries. The Athena queries will target 7 to 12 of the available data fields.
Which solution will meet these requirements with the LEAST amount of customization to transform and store the ingested data?
- A . Use AWS Lambda to read and aggregate the data hourly. Transform the data and store it in Amazon S3 by using Amazon Kinesis Data Firehose.
- B . Use Amazon Kinesis Data Firehose to read and aggregate the data hourly. Transform the data and store it in Amazon S3 by using a short-lived Amazon EMR cluster.
- C . Use Amazon Kinesis Data Analytics to read and aggregate the data hourly. Transform the data and store it in Amazon S3 by using Amazon Kinesis Data Firehose.
- D . Use Amazon Kinesis Data Firehose to read and aggregate the data hourly. Transform the data and store it in Amazon S3 by using AWS Lambda.
C
Explanation:
The solution that will meet the requirements with the least amount of customization to transform and store the ingested data is to use Amazon Kinesis Data Analytics to read and aggregate the data hourly, transform the data and store it in Amazon S3 by using Amazon Kinesis Data Firehose. This solution leverages the built-in features of Kinesis Data Analytics to perform SQL queries on streaming data and generate hourly summaries. Kinesis Data Analytics can also output the transformed data to Kinesis Data Firehose, which can then deliver the data to S3 in a specified format and partitioning scheme. This solution does not require any custom code or additional infrastructure to process the data. The other solutions either require more customization (such as using Lambda or EMR) or do not meet the requirement of aggregating the data hourly (such as using Lambda to read the data from Kinesis Data Streams).
References:
1: Boosting Resiliency with an ML-based Telemetry Analytics Architecture | AWS Architecture Blog
2: AWS Cloud Data Ingestion Patterns and Practices
3: IoT ingestion and Machine Learning analytics pipeline with AWS IoT …
4: AWS IoT Data Ingestion Simplified 101: The Complete Guide – Hevo Data
A data scientist needs to identify fraudulent user accounts for a company’s ecommerce platform. The company wants the ability to determine if a newly created account is associated with a previously known fraudulent user. The data scientist is using AWS Glue to cleanse the company’s application logs during ingestion.
Which strategy will allow the data scientist to identify fraudulent accounts?
- A . Execute the built-in FindDuplicates Amazon Athena query.
- B . Create a FindMatches machine learning transform in AWS Glue.
- C . Create an AWS Glue crawler to infer duplicate accounts in the source data.
- D . Search for duplicate accounts in the AWS Glue Data Catalog.
B
Explanation:
The best strategy to identify fraudulent accounts is to create a FindMatches machine learning transform in AWS Glue. The FindMatches transform enables you to identify duplicate or matching records in your dataset, even when the records do not have a common unique identifier and no fields match exactly. This can help you improve fraud detection by finding accounts that are associated with a previously known fraudulent user. You can teach the FindMatches transform your definition of a “duplicate” or a “match” through examples, and it will use machine learning to identify other potential duplicates or matches in your dataset. You can then use the FindMatches transform in your AWS Glue ETL jobs to cleanse your data.
Option A is incorrect because there is no built-in FindDuplicates Amazon Athena query. Amazon Athena is an interactive query service that makes it easy to analyze data in Amazon S3 using standard SQL. However, Amazon Athena does not provide a predefined query to find duplicate records in a dataset. You would have to write your own SQL query to perform this task, which might not be as effective or accurate as using the FindMatches transform.
Option C is incorrect because creating an AWS Glue crawler to infer duplicate accounts in the source data is not a valid strategy. An AWS Glue crawler is a program that connects to a data store, progresses through a prioritized list of classifiers to determine the schema for your data, and then creates metadata tables in the AWS Glue Data Catalog. A crawler does not perform any data cleansing or record matching tasks.
Option D is incorrect because searching for duplicate accounts in the AWS Glue Data Catalog is not a feasible strategy. The AWS Glue Data Catalog is a central repository to store structural and operational metadata for your data assets. The Data Catalog does not store the actual data, but rather the metadata that describes where the data is located, how it is formatted, and what it contains. Therefore, you cannot search for duplicate records in the Data Catalog.
References:
Record matching with AWS Lake Formation FindMatches – AWS Glue Amazon Athena C Interactive SQL Queries for Data in Amazon S3 AWS Glue Crawlers – AWS Glue AWS Glue Data Catalog – AWS Glue