
Snowflake ARA-C01 Practice Exams
Last updated on Oct 22,2026- Exam Code: ARA-C01
- Exam Name: SnowPro Advanced Architect Certification
- Certification Provider: Snowflake
- Latest update: Oct 22,2026
A large manufacturing company runs a dozen individual Snowflake accounts across its business divisions. The company wants to increase the level of data sharing to support supply chain optimizations and increase its purchasing leverage with multiple vendors.
The company’s Snowflake Architects need to design a solution that would allow the business divisions to decide what to share, while minimizing the level of effort spent on configuration and management. Most of the company divisions use Snowflake accounts in the same cloud deployments with a few exceptions for European-based divisions.
According to Snowflake recommended best practice, how should these requirements be met?
- A . Migrate the European accounts in the global region and manage shares in a connected graph architecture. Deploy a Data Exchange.
- B . Deploy a Private Data Exchange in combination with data shares for the European accounts.
- C . Deploy to the Snowflake Marketplace making sure that invoker_share() is used in all secure views.
- D . Deploy a Private Data Exchange and use replication to allow European data shares in the Exchange.
D
Explanation:
According to Snowflake recommended best practice, the requirements of the large manufacturing company should be met by deploying a Private Data Exchange in combination with data shares for the European accounts. A Private Data Exchange is a feature of the Snowflake Data Cloud platform that enables secure and governed sharing of data between organizations. It allows Snowflake customers to create their own data hub and invite other parts of their organization or external partners to access and contribute data sets. A Private Data Exchange provides centralized management, granular access control, and data usage metrics for the data shared in the exchange1. A data share is a secure and direct way of sharing data between Snowflake accounts without having to copy or move the data. A data share allows the data provider to grant privileges on selected objects in their account to one or more data consumers in other accounts2. By using a Private Data Exchange in combination with data shares, the company can achieve the following benefits:
The business divisions can decide what data to share and publish it to the Private Data Exchange, where it can be discovered and accessed by other members of the exchange. This reduces the effort and complexity of managing multiple data sharing relationships and configurations.
The company can leverage the existing Snowflake accounts in the same cloud deployments to create the Private Data Exchange and invite the members to join. This minimizes the migration and setup costs and leverages the existing Snowflake features and security.
The company can use data shares to share data with the European accounts that are in different regions or cloud platforms. This allows the company to comply with the regional and regulatory requirements for data sovereignty and privacy, while still enabling data collaboration across the organization.
The company can use the Snowflake Data Cloud platform to perform data analysis and transformation on the shared data, as well as integrate with other data sources and applications. This enables the company to optimize its supply chain and increase its purchasing leverage with multiple vendors.
A new user user_01 is created within Snowflake. The following two commands are executed:
Command 1-> show grants to user user_01;
Command 2 ~> show grants on user user 01;
What inferences can be made about these commands?
- A . Command 1 defines which user owns user_01
Command 2 defines all the grants which have been given to user_01 - B . Command 1 defines all the grants which are given to user_01 Command 2 defines which user owns user_01
- C . Command 1 defines which role owns user_01
Command 2 defines all the grants which have been given to user_01 - D . Command 1 defines all the grants which are given to user_01
Command 2 defines which role owns user 01
D
Explanation:
The SHOW GRANTS command in Snowflake can be used to list all the access control privileges that have been explicitly granted to roles, users, and shares. The syntax and the output of the command vary depending on the object type and the grantee type specified in the command1.
In this question, the two commands have the following meanings:
Command 1: show grants to user user_01; This command lists all the roles granted to the user user_01. The output includes the role name, the grantee name, and the granted by role name for each grant. This command is equivalent to show grants to user current_user if user_01 is the current user1.
Command 2: show grants on user user_01; This command lists all the privileges that have been granted on the user object user_01. The output includes the privilege name, the grantee name, and the granted by role name for each grant. This command shows which role owns the user object user_01, as the owner role has the privilege to modify or drop the user object2.
Therefore, the correct inference is that command 1 defines all the grants which are given to user_01,
and command 2 defines which role owns user_01.
Reference: SHOW GRANTS
Understanding Access Control in Snowflake
Why might a Snowflake Architect use a star schema model rather than a 3NF model when designing a data architecture to run in Snowflake? (Select TWO).
- A . Snowflake cannot handle the joins implied in a 3NF data model.
- B . The Architect wants to remove data duplication from the data stored in Snowflake.
- C . The Architect is designing a landing zone to receive raw data into Snowflake.
- D . The Bl tool needs a data model that allows users to summarize facts across different dimensions, or to drill down from the summaries.
- E . The Architect wants to present a simple flattened single view of the data to a particular group of end users.
D E
Explanation:
A star schema model is a type of dimensional data model that consists of a single fact table and multiple dimension tables. A 3NF model is a type of relational data model that follows the third normal form, which eliminates data redundancy and ensures referential integrity. A Snowflake Architect might use a star schema model rather than a 3NF model when designing a data architecture to run in Snowflake for the following reasons:
A star schema model is more suitable for analytical queries that require aggregating and slicing data across different dimensions, such as those performed by a BI tool. A 3NF model is more suitable for transactional queries that require inserting, updating, and deleting individual records.
A star schema model is simpler and faster to query than a 3NF model, as it involves fewer joins and less complex SQL statements. A 3NF model is more complex and slower to query, as it involves more joins and more complex SQL statements.
A star schema model can provide a simple flattened single view of the data to a particular group of end users, such as business analysts or data scientists, who need to explore and visualize the data. A 3NF model can provide a more detailed and normalized view of the data to a different group of end users, such as application developers or data engineers, who need to maintain and update the data. The other options are not valid reasons for choosing a star schema model over a 3NF model in Snowflake:
Snowflake can handle the joins implied in a 3NF data model, as it supports ANSI SQL and has a
powerful query engine that can optimize and execute complex queries efficiently.
The Architect can use both star schema and 3NF models to remove data duplication from the data stored in Snowflake, as both models can enforce data integrity and avoid data anomalies. However, the trade-off is that a star schema model may have more data redundancy than a 3NF model, as it denormalizes the data for faster query performance, while a 3NF model may have less data redundancy than a star schema model, as it normalizes the data for easier data maintenance.
The Architect can use both star schema and 3NF models to design a landing zone to receive raw data into Snowflake, as both models can accommodate different types of data sources and formats. However, the choice of the model may depend on the purpose and scope of the landing zone, such as whether it is a temporary or permanent storage, whether it is a staging area or a data lake, and whether it is a single source or a multi-source integration.
Reference: Snowflake Architect Training
Data Modeling: Understanding the Star and Snowflake Schemas
Data Vault vs Star Schema vs Third Normal Form: Which Data Model to Use?
Star Schema vs Snowflake Schema: 5 Key Differences
Dimensional Data Modeling – Snowflake schema
Star schema vs Snowflake Schema
An Architect entered the following commands in sequence:
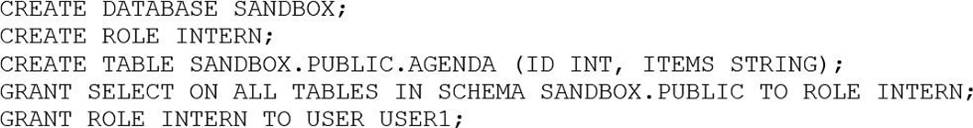
USER1 cannot find the table.
Which of the following commands does the Architect need to run for USER1 to find the tables using
the Principle of Least Privilege? (Choose two.)
- A . GRANT ROLE PUBLIC TO ROLE INTERN;
- B . GRANT USAGE ON DATABASE SANDBOX TO ROLE INTERN;
- C . GRANT USAGE ON SCHEMA SANDBOX.PUBLIC TO ROLE INTERN;
- D . GRANT OWNERSHIP ON DATABASE SANDBOX TO USER INTERN;
- E . GRANT ALL PRIVILEGES ON DATABASE SANDBOX TO ROLE INTERN;
B, C
Explanation:
According to the Principle of Least Privilege, the Architect should grant the minimum privileges necessary for the USER1 to find the tables in the SANDBOX database.
The USER1 needs to have USAGE privilege on the SANDBOX database and the SANDBOX.PUBLIC schema to be able to access the tables in the PUBLIC schema. Therefore, the commands B and C are the correct ones to run.
The command A is not correct because the PUBLIC role is automatically granted to every user and role in the account, and it does not have any privileges on the SANDBOX database by default. The command D is not correct because it would transfer the ownership of the SANDBOX database from the Architect to the USER1, which is not necessary and violates the Principle of Least Privilege. The command E is not correct because it would grant all the possible privileges on the SANDBOX database to the USER1, which is also not necessary and violates the Principle of Least Privilege.
Reference: Snowflake – Principle of Least Privilege: Snowflake – Access Control Privileges: Snowflake – Public Role: Snowflake – Ownership and Grants
An Architect entered the following commands in sequence:
USER1 cannot find the table.
Which of the following commands does the Architect need to run for USER1 to find the tables using
the Principle of Least Privilege? (Choose two.)
- A . GRANT ROLE PUBLIC TO ROLE INTERN;
- B . GRANT USAGE ON DATABASE SANDBOX TO ROLE INTERN;
- C . GRANT USAGE ON SCHEMA SANDBOX.PUBLIC TO ROLE INTERN;
- D . GRANT OWNERSHIP ON DATABASE SANDBOX TO USER INTERN;
- E . GRANT ALL PRIVILEGES ON DATABASE SANDBOX TO ROLE INTERN;
B, C
Explanation:
According to the Principle of Least Privilege, the Architect should grant the minimum privileges necessary for the USER1 to find the tables in the SANDBOX database.
The USER1 needs to have USAGE privilege on the SANDBOX database and the SANDBOX.PUBLIC schema to be able to access the tables in the PUBLIC schema. Therefore, the commands B and C are the correct ones to run.
The command A is not correct because the PUBLIC role is automatically granted to every user and role in the account, and it does not have any privileges on the SANDBOX database by default. The command D is not correct because it would transfer the ownership of the SANDBOX database from the Architect to the USER1, which is not necessary and violates the Principle of Least Privilege. The command E is not correct because it would grant all the possible privileges on the SANDBOX database to the USER1, which is also not necessary and violates the Principle of Least Privilege.
Reference: Snowflake – Principle of Least Privilege: Snowflake – Access Control Privileges: Snowflake – Public Role: Snowflake – Ownership and Grants
Which organization-related tasks can be performed by the ORGADMIN role? (Choose three.)
- A . Changing the name of the organization
- B . Creating an account
- C . Viewing a list of organization accounts
- D . Changing the name of an account
- E . Deleting an account
- F . Enabling the replication of a database
B, C, F
Explanation:
According to the SnowPro Advanced: Architect documents and learning resources, the organization-related tasks that can be performed by the ORGADMIN role are:
Creating an account in the organization. A user with the ORGADMIN role can use the CREATE ACCOUNT command to create a new account that belongs to the same organization as the current account1.
Viewing a list of organization accounts. A user with the ORGADMIN role can use the SHOW ORGANIZATION ACCOUNTS command to view the names and properties of all accounts in the organization2. Alternatively, the user can use the Admin » Accounts page in the web interface to view the organization name and account names3.
Enabling the replication of a database. A user with the ORGADMIN role can use the SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER function to enable database replication for an account in the organization. This allows the user to replicate databases across accounts in different regions and cloud platforms for data availability and durability4.
The other options are incorrect because they are not organization-related tasks that can be performed by the ORGADMIN role. Option A is incorrect because changing the name of the organization is not a task that can be performed by the ORGADMIN role. To change the name of an organization, the user must contact Snowflake Support3. Option D is incorrect because changing the name of an account is not a task that can be performed by the ORGADMIN role. To change the name of an account, the user must contact Snowflake Support5. Option E is incorrect because deleting an account is not a task that can be performed by the ORGADMIN role. To delete an account, the user must contact Snowflake Support.
Reference: CREATE ACCOUNT | Snowflake Documentation, SHOW ORGANIZATION ACCOUNTS | Snowflake Documentation, Getting Started with Organizations | Snowflake Documentation, SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER | Snowflake Documentation, ALTER ACCOUNT | Snowflake Documentation, [DROP ACCOUNT | Snowflake Documentation]
When loading data from stage using COPY INTO, what options can you specify for the ON_ERROR
clause?
- A . CONTINUE
- B . SKIP_FILE
- C . ABORT_STATEMENT
- D . FAIL
A, B, C
Explanation:
The ON_ERROR clause is an optional parameter for the COPY INTO command that specifies the behavior of the command when it encounters errors in the files. The ON_ERROR clause can have one of the following values1:
CONTINUE: This value instructs the command to continue loading the file and return an error message for a maximum of one error encountered per data file. The difference between the ROWS_PARSED and ROWS_LOADED column values represents the number of rows that include detected errors. To view all errors in the data files, use the VALIDATION_MODE parameter or query the VALIDATE function1.
SKIP_FILE: This value instructs the command to skip the file when it encounters a data error on any of the records in the file. The command moves on to the next file in the stage and continues loading. The skipped file is not loaded and no error message is returned for the file1.
ABORT_STATEMENT: This value instructs the command to stop loading data when the first error is encountered. The command returns an error message for the file and aborts the load operation. This is the default value for the ON_ERROR clause1.
Therefore, options A, B, and C are correct.
Reference: COPY INTO <table>
A group of Data Analysts have been granted the role analyst role. They need a Snowflake database where they can create and modify tables, views, and other objects to load with their own data. The Analysts should not have the ability to give other Snowflake users outside of their role access to this data.
How should these requirements be met?
- A . Grant ANALYST_R0LE OWNERSHIP on the database, but make sure that ANALYST_ROLE does not have the MANAGE GRANTS privilege on the account.
- B . Grant SYSADMIN ownership of the database, but grant the create schema privilege on the database to the ANALYST_ROLE.
- C . Make every schema in the database a managed access schema, owned by SYSADMIN, and grant create privileges on each schema to the ANALYST_ROLE for each type of object that needs to be created.
- D . Grant ANALYST_ROLE ownership on the database, but grant the ownership on future [object type] s in database privilege to SYSADMIN.
C
Explanation:
The requirements state that the data analysts need to be able to create and modify database objects and load data, but should not be able to manage access for users outside of their role.
Option C: By making each schema within the database a managed access schema and having them owned by SYSADMIN, the ability to grant privileges on the schema’s objects is strictly controlled. Managed access schemas limit the granting of privileges to the role specified as the owner of the schema, in this case, SYSADMIN. The ANALYST_ROLE can be granted the privileges necessary to create and modify objects within these schemas, satisfying the requirement for the analysts to perform their tasks without being able to extend access beyond their role.
Database DB1 has schema S1 which has one table, T1.
DB1 –> S1 –> T1
The retention period of EG1 is set to 10 days.
The retention period of s: is set to 20 days.
The retention period of t: Is set to 30 days.
The user runs the following command:
Drop Database DB1;
What will the Time Travel retention period be for T1?
- A . 10 days
- B . 20 days
- C . 30 days
- D . 37 days
C
Explanation:
The Time Travel retention period for T1 will be 30 days, which is the retention period set at the table level. The Time Travel retention period determines how long the historical data is preserved and accessible for an object after it is modified or dropped. The Time Travel retention period can be set at the account level, the database level, the schema level, or the table level. The retention period set at the lowest level of the hierarchy takes precedence over the higher levels. Therefore, the retention period set at the table level overrides the retention periods set at the schema level, the database level, or the account level. When the user drops the database DB1, the table T1 is also dropped, but the historical data is still preserved for 30 days, which is the retention period set at the table level. The user can use the UNDROP command to restore the table T1 within the 30-day period.
The other options are incorrect because:
10 days is the retention period set at the database level, which is overridden by the table level.
20 days is the retention period set at the schema level, which is also overridden by the table level.
37 days is not a valid option, as it is not the retention period set at any level.
Reference: Understanding & Using Time Travel
AT | BEFORE
Snowflake Time Travel & Fail-safe
Which columns can be included in an external table schema? (Select THREE).
- A . VALUE
- B . METADATASROW_ID
- C . METADATASISUPDATE
- D . METADAT A$ FILENAME
- E . METADATAS FILE_ROW_NUMBER
- F . METADATASEXTERNAL TABLE PARTITION
A, D E
Explanation:
An external table schema defines the columns and data types of the data stored in an external stage.
All external tables include the following columns by default:
VALUE: A VARIANT type column that represents a single row in the external file.
METADATA$FILENAME: A pseudocolumn that identifies the name of each staged data file included in the external table, including its path in the stage.
METADATA$FILE_ROW_NUMBER: A pseudocolumn that shows the row number for each record in a staged data file.
You can also create additional virtual columns as expressions using the VALUE column and/or the pseudocolumns. However, the following columns are not valid for external tables and cannot be included in the schema:
METADATASROW_ID: This column is only available for internal tables and shows the unique identifier for each row in the table.
METADATASISUPDATE: This column is only available for internal tables and shows whether the row was inserted or updated by a merge operation.
METADATASEXTERNAL TABLE PARTITION: This column is not a valid column name and does not exist in Snowflake.
Reference: Introduction to External Tables, CREATE EXTERNAL TABLE