Microsoft DP-203 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-203
- Exam Name: Data Engineering on Microsoft Azure
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
HOTSPOT
You have an Azure Data Factory instance named ADF1 and two Azure Synapse Analytics workspaces named WS1 and WS2.
ADF1 contains the following pipelines:
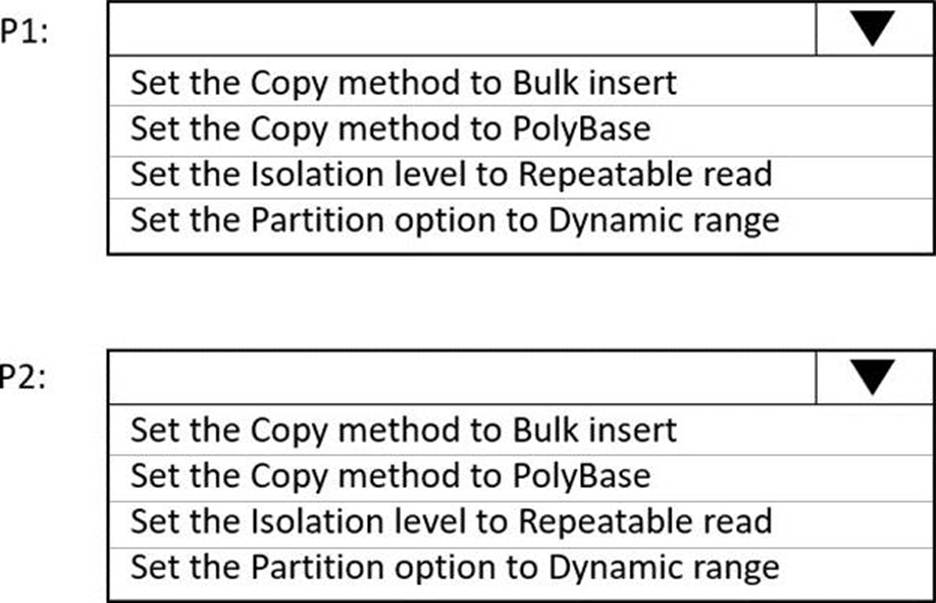
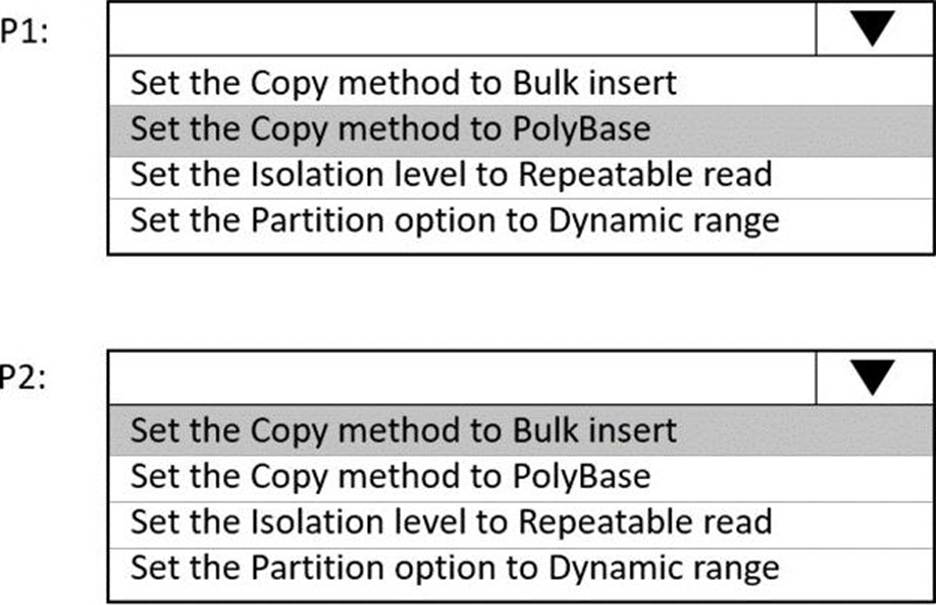
✑ P1: Uses a copy activity to copy data from a nonpartitioned table in a dedicated SQL pool of WS1 to an Azure Data Lake Storage Gen2 account
✑ P2: Uses a copy activity to copy data from text-delimited files in an Azure Data Lake Storage Gen2 account to a nonpartitioned table in a dedicated SQL pool of WS2
You need to configure P1 and P2 to maximize parallelism and performance.
Which dataset settings should you configure for the copy activity if each pipeline? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
HOTSPOT
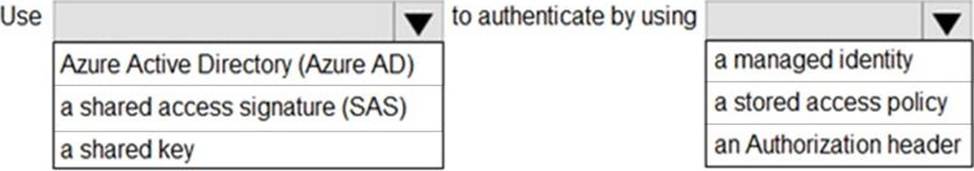
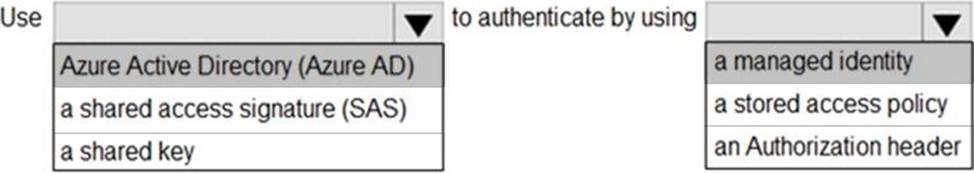
You have an Azure subscription that contains an Azure Data Lake Storage account. The storage account contains a data lake named DataLake1.
You plan to use an Azure data factory to ingest data from a folder in DataLake1, transform the data, and land the data in another folder.
You need to ensure that the data factory can read and write data from any folder in the DataLake1 file system.
The solution must meet the following requirements:
✑ Minimize the risk of unauthorized user access.
✑ Use the principle of least privilege.
✑ Minimize maintenance effort.
How should you configure access to the storage account for the data factory? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
You have an Azure Synapse Analytics dedicated SQL pool named Pool1. Pool1 contains a table named table1.
You load 5 TB of data intotable1.
You need to ensure that columnstore compression is maximized for table1.
Which statement should you execute?
- A . ALTER INDEX ALL on table1 REORGANIZE
- B . ALTER INDEX ALL on table1 REBUILD
- C . DBCC DBREINOEX (table1)
- D . DBCC INDEXDEFRAG (pool1, tablel)
You are designing an Azure Synapse solution that will provide a query interface for the data stored in an Azure Storage account. The storage account is only accessible from a virtual network.
You need to recommend an authentication mechanism to ensure that the solution can access the source data.
What should you recommend?
- A . a managed identity
- B . anonymous public read access
- C . a shared key
HOTSPOT
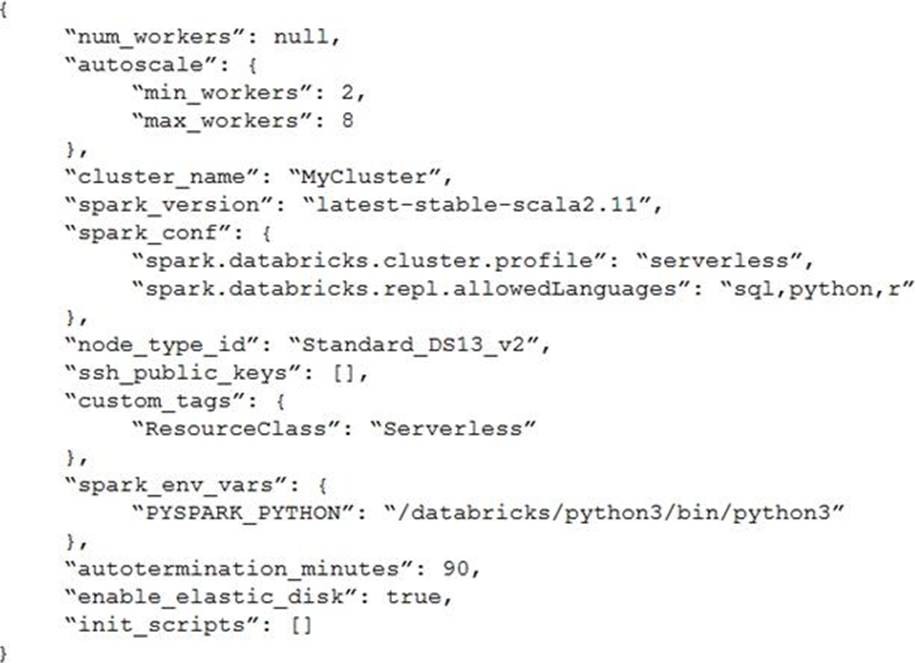
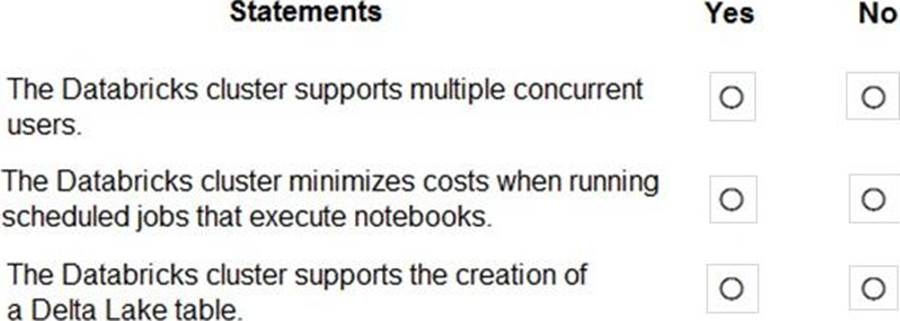
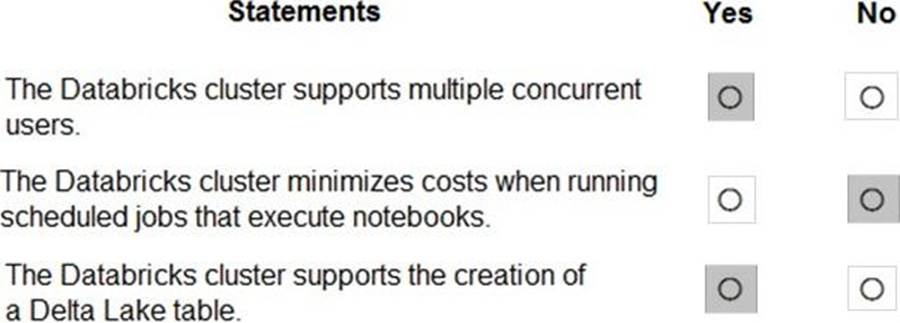
The following code segment is used to create an Azure Databricks cluster.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
You have a Microsoft Entra tenant.
The tenant contains an Azure Data Lake Storage Gen2 account named storage! that has two containers named fs1 and fs2. You have a Microsoft Entra group named Oepartment A.
You need to meet the following requirements:
• OepartmentA must be able to read, write, and list all the files in fs1.
• OepartmentA must be prevented from accessing any files in fs2
• The solution must use the principle of least privilege.
Which role should you assign to DepartmentA?
- A . Contributor for fsl
- B . Storage Blob Data Owner for fsl
- C . Storage Blob Data Contributor for storage1
- D . Storage Blob Data Contributor for fsl
HOTSPOT
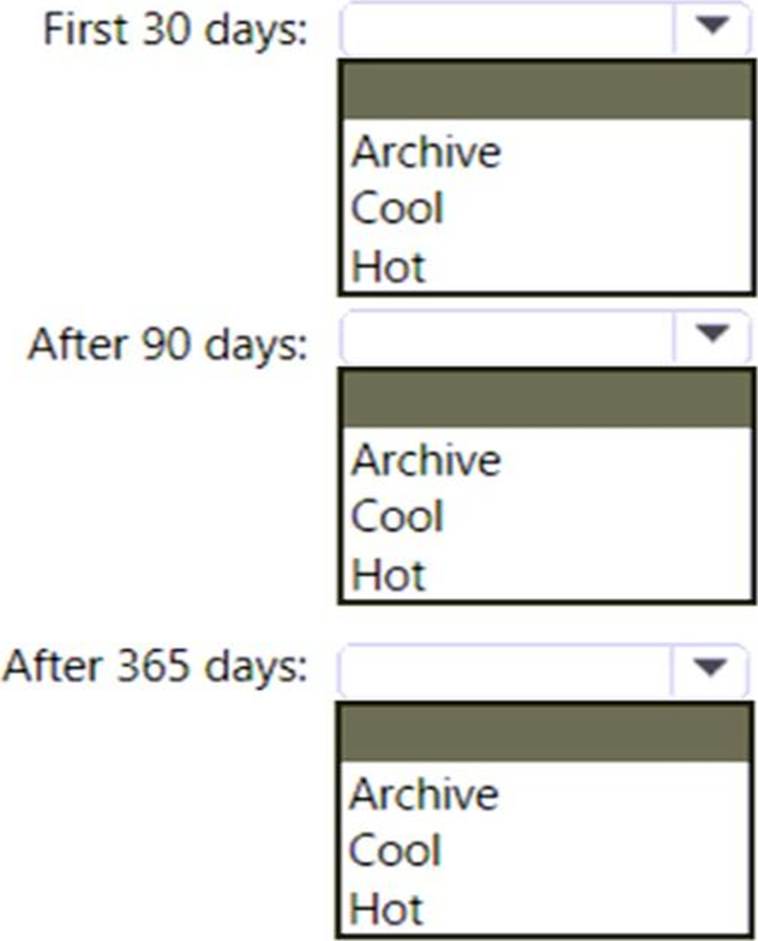
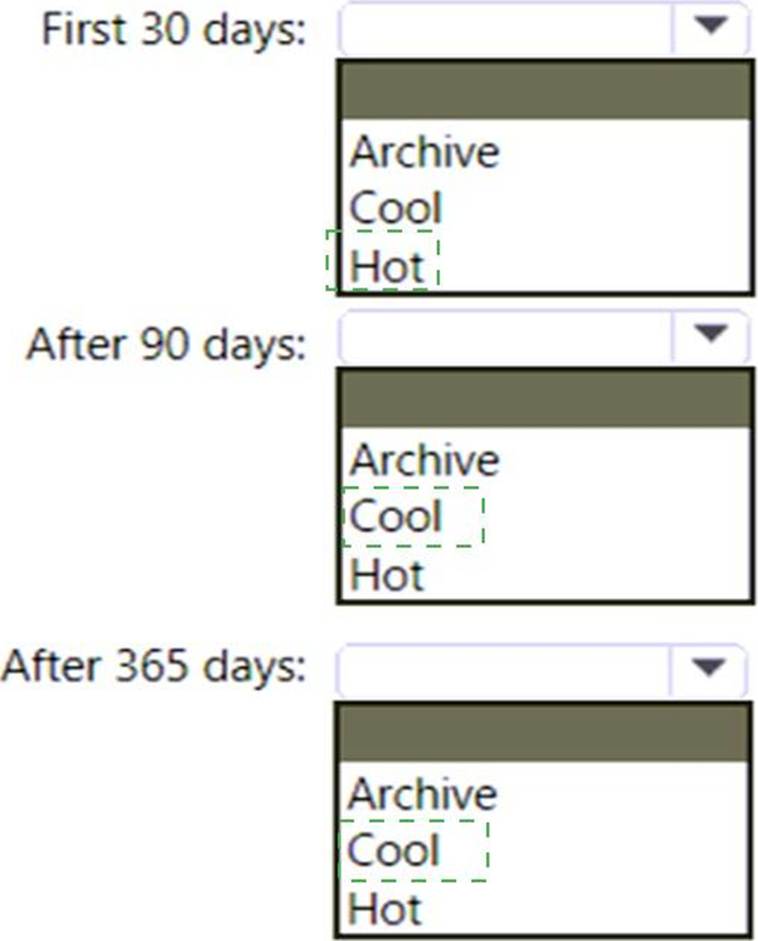
You are designing an application that will use an Azure Data Lake Storage Gen 2 account to store petabytes of license plate photos from toll booths. The account will use zone-redundant storage (ZRS).
You identify the following usage patterns:
• The data will be accessed several times a day during the first 30 days after the data is created. The data must meet an availability SU of 99.9%.
• After 90 days, the data will be accessed infrequently but must be available within 30 seconds.
• After 365 days, the data will be accessed infrequently but must be available within five minutes.
HOTSPOT
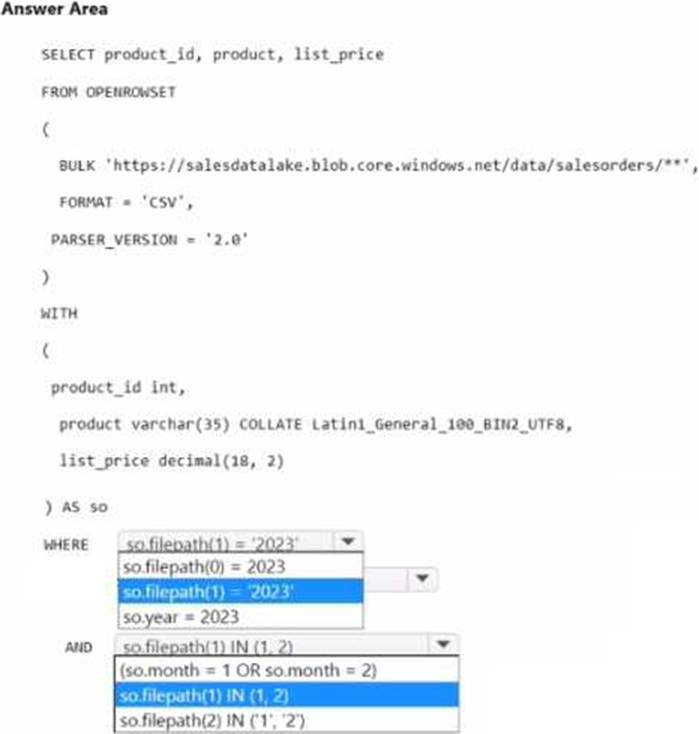
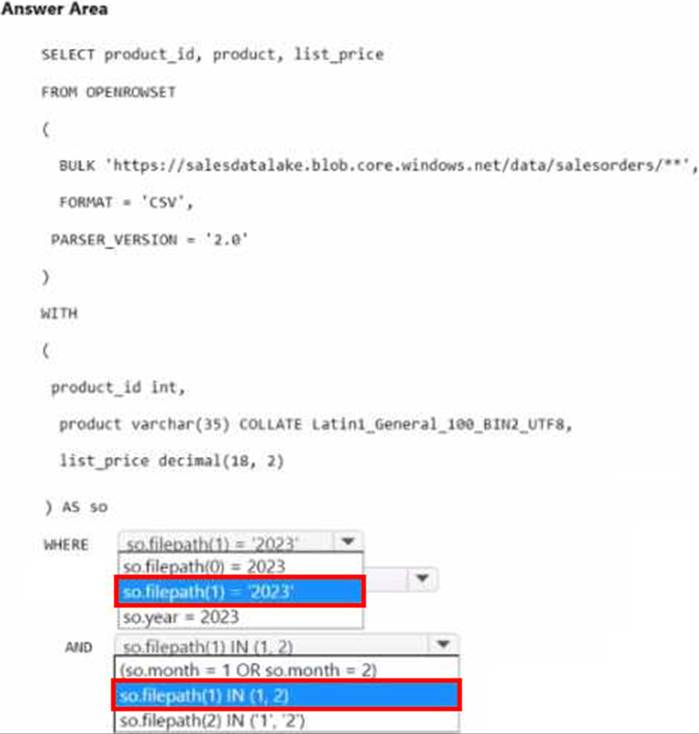
You have an Azure Data Lake Storage account that contains CSV files. The CSV files contain sales order data and are partitioned by using the following format. /data/salesorders/year=xxxx/month-y
You need to retrieve only the sales orders from January 2023 and February 2023.
How should you complete the query? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
HOTSPOT
You have an Azure Data Lake Storage account that contains CSV files. The CSV files contain sales order data and are partitioned by using the following format. /data/salesorders/year=xxxx/month-y
You need to retrieve only the sales orders from January 2023 and February 2023.
How should you complete the query? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
DRAG DROP
You have an Azure data factory.
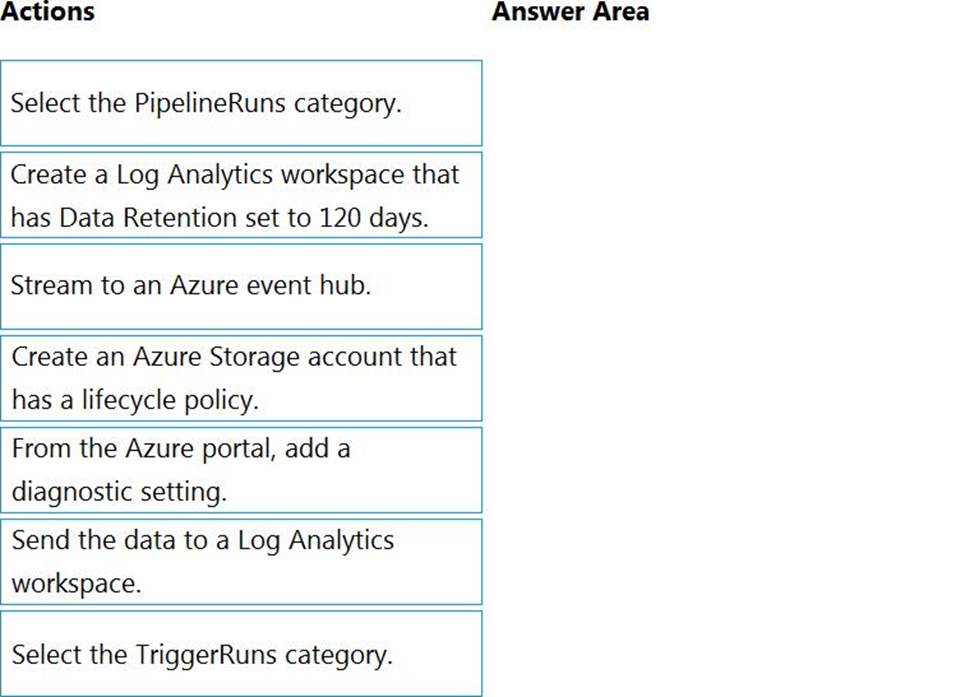
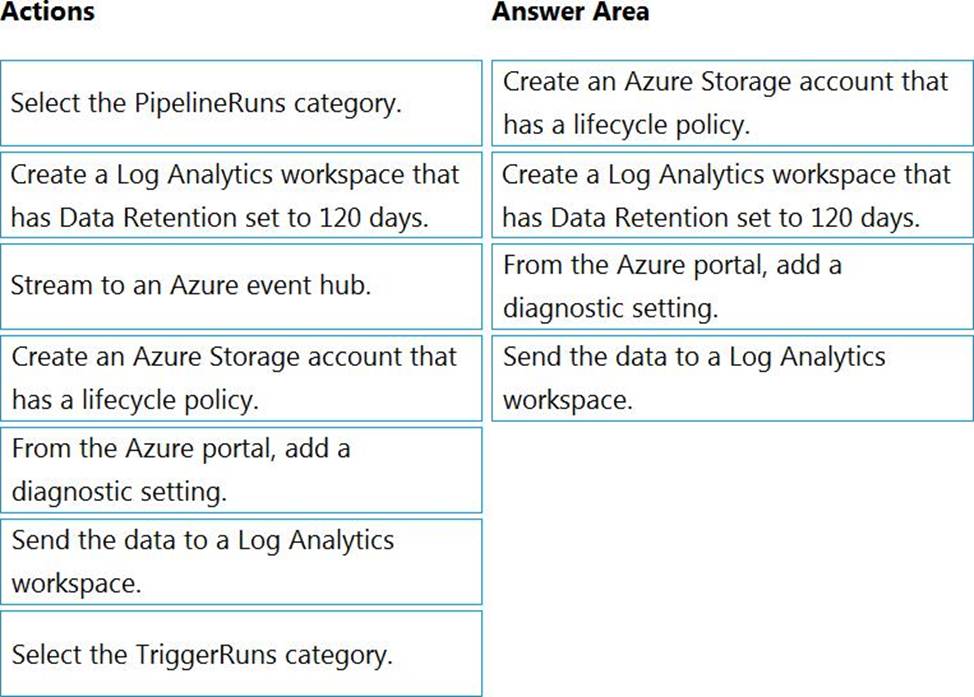
You need to ensure that pipeline-run data is retained for 120 days. The solution must ensure that you can query the data by using the Kusto query language.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order. NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.