Microsoft DP-100 Practice Exams
Last updated on Nov 16,2026- Exam Code: DP-100
- Exam Name: Designing and Implementing a Data Science Solution on Azure
- Certification Provider: Microsoft
- Latest update: Nov 16,2026
You create a deep learning model for image recognition on Azure Machine Learning service using GPU-based training.
You must deploy the model to a context that allows for real-time GPU-based inferencing.
You need to configure compute resources for model inferencing.
Which compute type should you use?
- A . Azure Container Instance
- B . Azure Kubernetes Service
- C . Field Programmable Gate Array
- D . Machine Learning Compute
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model.
You configure a HyperDriveConfig for the experiment by running the following code:
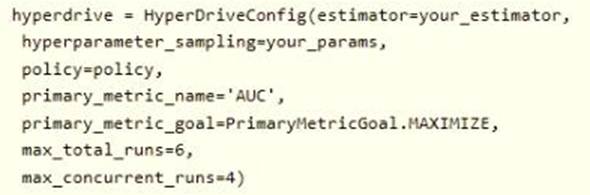
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
Solution: Run the following code:
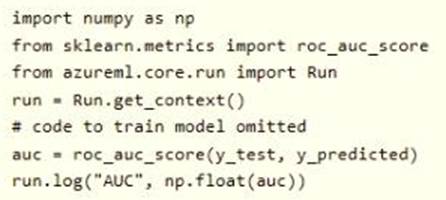
Does the solution meet the goal?
- A . Yes
- B . No
You create a workspace by using Azure Machine Learning Studio.
You must run a Python SDK v2 notebook in the workspace by using Azure Machine Learning Studio.
You need to reset the state of the notebook.
Which three actions should you use? Each correct answer presents a complete solution. NOTE: Each correct selection is worth one point.
- A . Reset the compute.
- B . Change the current kernel.
- C . Stop the current kernel.
- D . Change the compute.
- E . Navigate to another section of the workspace.
HOTSPOT
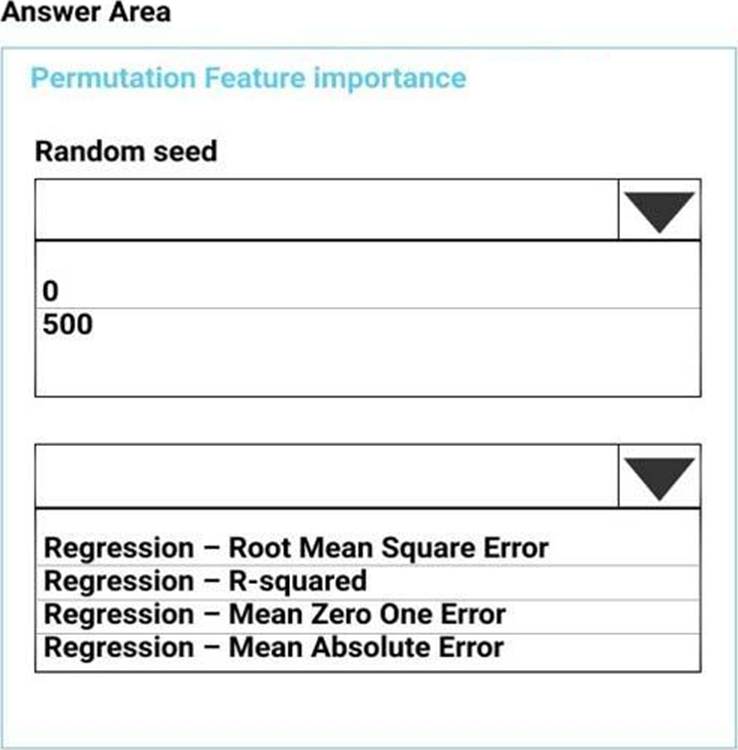
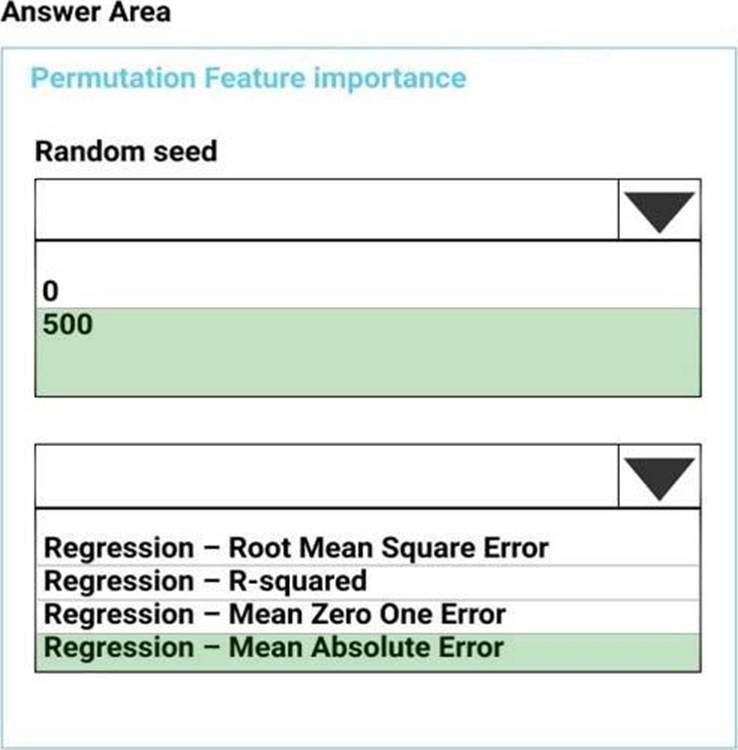
You need to configure the Permutation Feature Importance module for the model training requirements.
What should you do? To answer, select the appropriate options in the dialog box in the answer area. NOTE: Each correct selection is worth one point.
You manage an Azure Machine learning workspace. You develop a machine teaming model.
You are deploying the model to use a low-pointy VM mm a pacing discount.
You need to deploy the model.
Which compute large! should you use?
- A . Azure Machine Learning coulee clusters
- B . Azure Container instances (ACI)
- C . Azure Kubemetes Service (AKS)
- D . local deployment
HOTSPOT
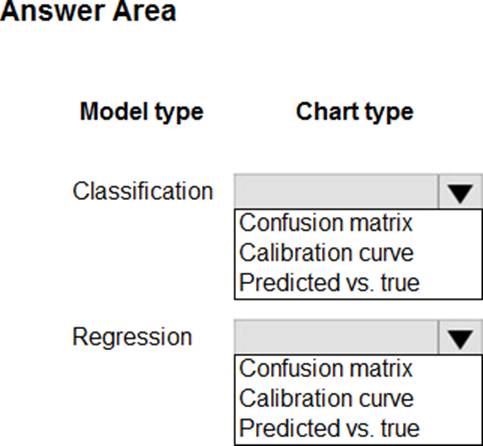
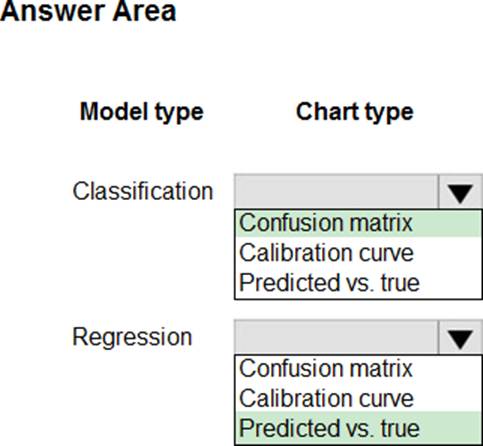
You train classification and regression models by using automated machine learning.
You must evaluate automated machine learning experiment results. The results include how a classification model is making systematic errors in its predictions and the relationship between the target feature and the regression model’s predictions. You must use charts generated by automated machine learning.
You need to choose a chart type for each model type.
Which chart types should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
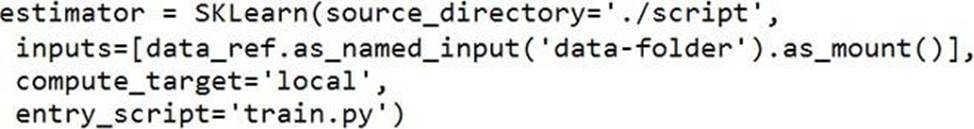
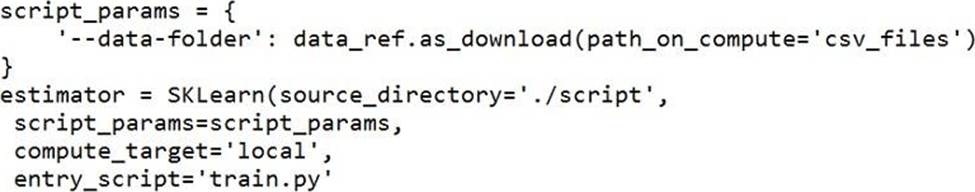
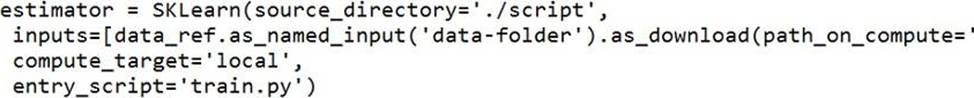
You create a datastore named training_data that references a blob container in an Azure Storage account. The blob container contains a folder named csv_files in which multiple comma-separated values (CSV) files are stored.
You have a script named train.py in a local folder named ./script that you plan to run as an experiment using an estimator.
The script includes the following code to read data from the csv_files folder:
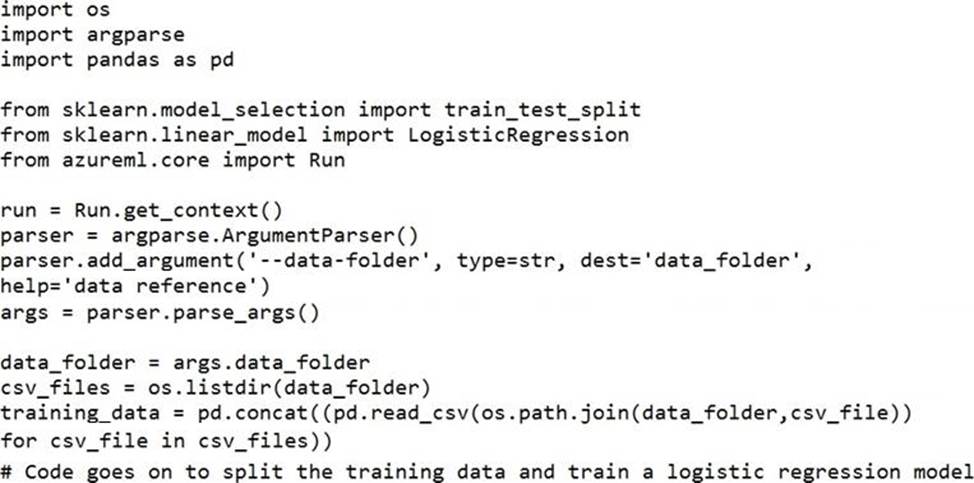
You have the following script.
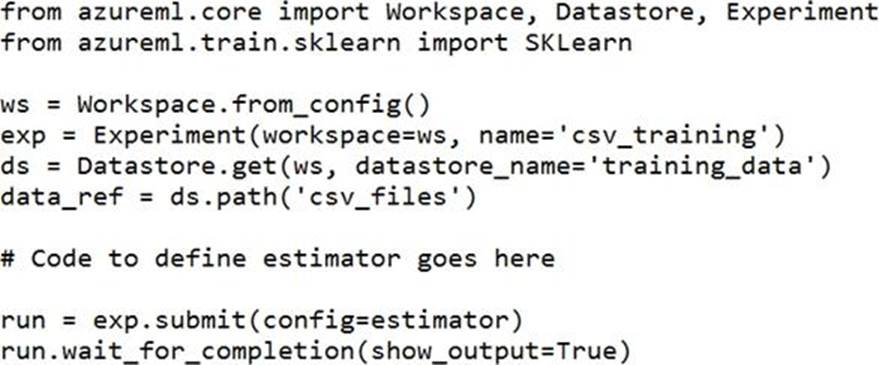
You need to configure the estimator for the experiment so that the script can read the data from a data reference named data_ref that references the csv_files folder in the training_data datastore.
Which code should you use to configure the estimator?
A)
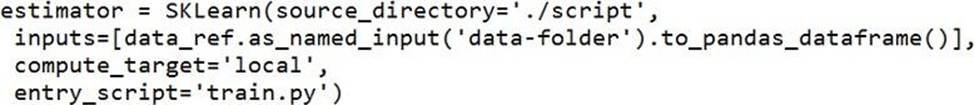
B)
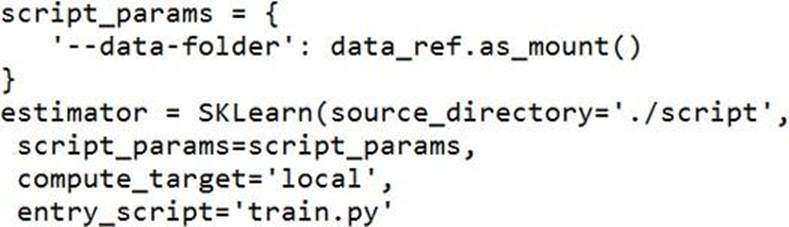
C)
D)
E)
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
You run an experiment that uses an AutoMLConfig class to define an automated machine learning task with a maximum of ten model training iterations. The task will attempt to find the best performing model based on a metric named accuracy.
You submit the experiment with the following code:
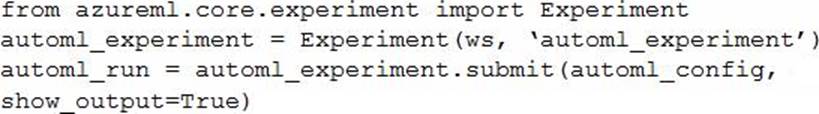
You need to create Python code that returns the best model that is generated by the automated machine learning task.
Which code segment should you use?
- A . best_model = automl_run.get_details()
- B . best_model = automl_run.get_output()[1]
- C . best_model = automl_run.get_file_names()[1]
- D . best_model = automl_run.get_metrics()
HOTSPOT
You have a dataset created for multiclass classification tasks that contains a normalized numerical feature set with 10,000 data points and 150 features.
You use 75 percent of the data points for training and 25 percent for testing. You are using the scikit-learn machine learning library in Python. You use X to denote the feature set and Y to denote class labels.
You create the following Python data frames:
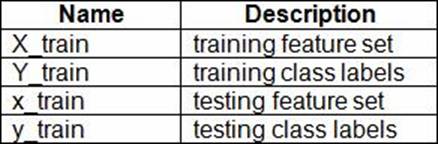
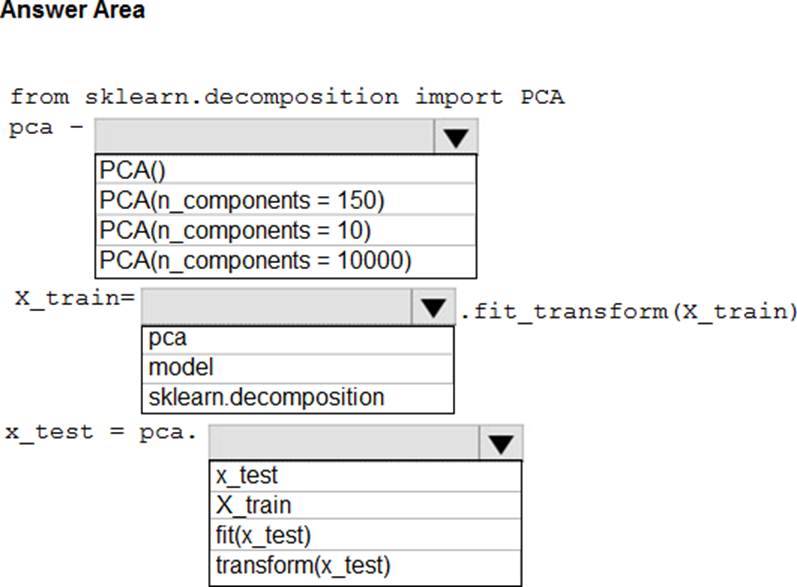
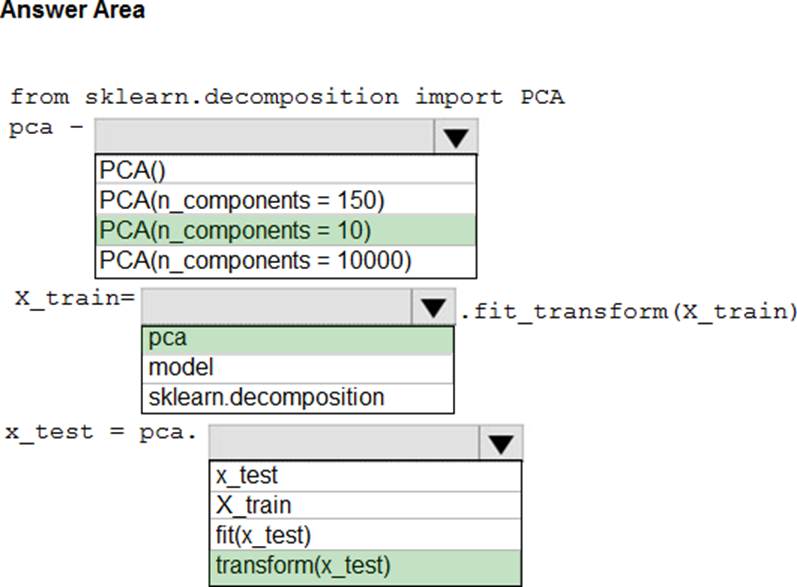
You need to apply the Principal Component Analysis (PCA) method to reduce the dimensionality of the feature set to 10 features in both training and testing sets.
How should you complete the code segment? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
HOTSPOT
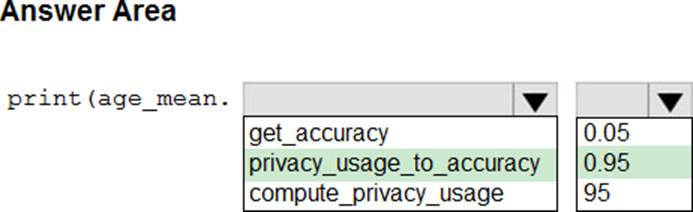
You create an Azure Machine Learning workspace and a dataset. The dataset includes age values for a large group of diabetes patients. You use the dp.mean function from the SmartNoise library to calculate the mean of the age value. You store the value in a variable named age.mean.
You must output the value of the interval range of released mean values that will be returned 95 percent of the time.
You need to complete the code.
Which code values should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.