
Google Professional Machine Learning Engineer Practice Exams
Last updated on Oct 11,2026- Exam Code: Professional Machine Learning Engineer
- Exam Name: Google Professional Machine Learning Engineer
- Certification Provider: Google
- Latest update: Oct 11,2026
You have trained a model on a dataset that required computationally expensive preprocessing operations. You need to execute the same preprocessing at prediction time. You deployed the model on Al Platform for high-throughput online prediction.
Which architecture should you use?
- A . • Validate the accuracy of the model that you trained on preprocessed data
• Create a new model that uses the raw data and is available in real time
• Deploy the new model onto Al Platform for online prediction - B . • Send incoming prediction requests to a Pub/Sub topic
• Transform the incoming data using a Dataflow job
• Submit a prediction request to Al Platform using the transformed data
• Write the predictions to an outbound Pub/Sub queue - C . • Stream incoming prediction request data into Cloud Spanner
• Create a view to abstract your preprocessing logic.
• Query the view every second for new records
• Submit a prediction request to Al Platform using the transformed data
• Write the predictions to an outbound Pub/Sub queue. - D . • Send incoming prediction requests to a Pub/Sub topic
• Set up a Cloud Function that is triggered when messages are published to the Pub/Sub topic.
• Implement your preprocessing logic in the Cloud Function
• Submit a prediction request to Al Platform using the transformed data
• Write the predictions to an outbound Pub/Sub queue
D
Explanation:
Option A is incorrect because creating a new model that uses the raw data and is available in real time would require retraining the model and deploying it again, which is not efficient or scalable.
Option B is incorrect because using a Dataflow job to transform the incoming data would introduce unnecessary latency and complexity for online prediction, which requires fast and simple processing.
Option C is incorrect because using Cloud Spanner to stream and query the incoming data would incur high costs and overhead for online prediction, which does not need a relational database.
Option D is correct because using a Cloud Function to preprocess the data and submit a prediction request to Al Platform is a simple and scalable solution for online prediction, which leverages the serverless and event-driven features of Cloud Functions.
You are building a custom image classification model and plan to use Vertex Al Pipelines to implement the end-to-end training. Your dataset consists of images that need to be preprocessed before they can be used to train the model. The preprocessing steps include resizing the images, converting them to grayscale, and extracting features. You have already implemented some Python functions for the preprocessing tasks.
Which components should you use in your pipeline?
A)

B)

C)

D)
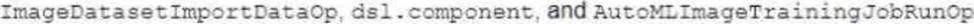
- A . Option A
- B . Option B
- C . Option C
- D . Option D
While monitoring your model training’s GPU utilization, you discover that you have a native synchronous implementation. The training data is split into multiple files. You want to reduce the execution time of your input pipeline.
What should you do?
- A . Increase the CPU load
- B . Add caching to the pipeline
- C . Increase the network bandwidth
- D . Add parallel interleave to the pipeline
D
Explanation:
Parallel interleave is a technique that can improve the performance of the input pipeline by reading and processing data from multiple files in parallel. This can reduce the idle time of the GPU and speed up the training process. Parallel interleave can be implemented using the tf.data.experimental.parallel_interleave () function in TensorFlow, which takes a map function that returns a dataset for each input element, and a cycle length that determines how many input elements are processed concurrently. Parallel interleave can also handle different file sizes and processing times by using a block length argument that controls how many consecutive elements are produced from each input element before switching to another input element. For more information about parallel interleave and how to use it, see the following references:
How to use parallel_interleave in TensorFlow
Better performance with the tf.data API
You need to build an ML model for a social media application to predict whether a user’s submitted profile photo meets the requirements. The application will inform the user if the picture meets the requirements.
How should you build a model to ensure that the application does not falsely accept a non-compliant picture?
- A . Use AutoML to optimize the model’s recall in order to minimize false negatives.
- B . Use AutoML to optimize the model’s F1 score in order to balance the accuracy of false positives and false negatives.
- C . Use Vertex AI Workbench user-managed notebooks to build a custom model that has three times as many examples of pictures that meet the profile photo requirements.
- D . Use Vertex AI Workbench user-managed notebooks to build a custom model that has three times as many examples of pictures that do not meet the profile photo requirements.
A
Explanation:
Recall is the ratio of true positives to the sum of true positives and false negatives. It measures how well the model can identify all the relevant cases. In this scenario, the relevant cases are the pictures that do not meet the profile photo requirements. Therefore, minimizing false negatives means minimizing the cases where the model incorrectly predicts that a non-compliant picture meets the requirements. By using AutoML to optimize the model’s recall, the model will be more likely to reject a non-compliant picture and inform the user accordingly.
Reference: [AutoML Vision] is a service that allows you to train custom ML models for image classification and object detection tasks. You can use AutoML to optimize your model for different metrics, such as recall, precision, or F1 score.
[Recall] is one of the evaluation metrics for ML models. It is defined as TP / (TP + FN), where TP is the
number of true positives and FN is the number of false negatives. Recall measures how well the model can identify all the relevant cases. A high recall means that the model has a low rate of false negatives.
You work for the AI team of an automobile company, and you are developing a visual defect detection model using TensorFlow and Keras. To improve your model performance, you want to incorporate some image augmentation functions such as translation, cropping, and contrast tweaking. You randomly apply these functions to each training batch. You want to optimize your data processing pipeline for run time and compute resources utilization.
What should you do?
- A . Embed the augmentation functions dynamically in the tf.Data pipeline.
- B . Embed the augmentation functions dynamically as part of Keras generators.
- C . Use Dataflow to create all possible augmentations, and store them as TFRecords.
- D . Use Dataflow to create the augmentations dynamically per training run, and stage them as TFRecords.
A
Explanation:
The best option for optimizing the data processing pipeline for run time and compute resources utilization is to embed the augmentation functions dynamically in the tf.Data pipeline.
This option has the following advantages:
It allows the data augmentation to be performed on the fly, without creating or storing additional copies of the data. This saves storage space and reduces the data transfer time.
It leverages the parallelism and performance of the tf.Data API, which can efficiently apply the augmentation functions to multiple batches of data in parallel, using multiple CPU cores or GPU devices. The tf.Data API also supports various optimization techniques, such as caching, prefetching, and autotuning, to improve the data processing speed and reduce the latency.
It integrates seamlessly with the TensorFlow and Keras models, which can consume the tf.Data datasets as inputs for training and evaluation. The tf.Data API also supports various data formats, such as images, text, audio, and video, and various data sources, such as files, databases, and web services.
The other options are less optimal for the following reasons:
Option B: Embedding the augmentation functions dynamically as part of Keras generators introduces some limitations and overhead. Keras generators are Python generators that yield batches of data for training or evaluation. However, Keras generators are not compatible with the tf.distribute API, which is used to distribute the training across multiple devices or machines. Moreover, Keras generators are not as efficient or scalable as the tf.Data API, as they run on a single Python thread and do not support parallelism or optimization techniques.
Option C: Using Dataflow to create all possible augmentations, and store them as TFRecords introduces additional complexity and cost. Dataflow is a fully managed service that runs Apache Beam pipelines for data processing and transformation. However, using Dataflow to create all possible augmentations requires generating and storing a large number of augmented images, which can consume a lot of storage space and incur storage and network costs. Moreover, using Dataflow to create the augmentations requires writing and deploying a separate Dataflow pipeline, which can be tedious and time-consuming.
Option D: Using Dataflow to create the augmentations dynamically per training run, and stage them as TFRecords introduces additional complexity and latency. Dataflow is a fully managed service that runs Apache Beam pipelines for data processing and transformation. However, using Dataflow to create the augmentations dynamically per training run requires running a Dataflow pipeline every time the model is trained, which can introduce latency and delay the training process. Moreover, using Dataflow to create the augmentations requires writing and deploying a separate Dataflow pipeline, which can be tedious and time-consuming.
Reference: [tf.data: Build TensorFlow input pipelines]
[Image augmentation | TensorFlow Core]
[Dataflow documentation]
You are developing a recommendation engine for an online clothing store. The historical customer transaction data is stored in BigQuery and Cloud Storage. You need to perform exploratory data analysis (EDA), preprocessing and model training. You plan to rerun these EDA, preprocessing, and training steps as you experiment with different types of algorithms. You want to minimize the cost and development effort of running these steps as you experiment.
How should you configure the environment?
- A . Create a Vertex Al Workbench user-managed notebook using the default VM instance, and use the %%bigquery magic commands in Jupyter to query the tables.
- B . Create a Vertex Al Workbench managed notebook to browse and query the tables directly from the JupyterLab interface.
- C . Create a Vertex Al Workbench user-managed notebook on a Dataproc Hub. and use the %%bigquery magic commands in Jupyter to query the tables.
- D . Create a Vertex Al Workbench managed notebook on a Dataproc cluster, and use the spark-bigquery-connector to access the tables.
A
Explanation:
Cost-effectiveness: User-managed notebooks in Vertex AI Workbench allow you to leverage pre-configured virtual machines with reasonable resource allocation, keeping costs lower compared to options involving managed notebooks or Dataproc clusters.
Development flexibility: User-managed notebooks offer full control over the environment, allowing you to install additional libraries or dependencies needed for your specific EDA, preprocessing, and model training tasks. This flexibility is crucial while experimenting with different algorithms.
BigQuery integration: The %%bigquery magic commands provide seamless integration with BigQuery within the Jupyter Notebook environment. This enables efficient querying and exploration of customer transaction data stored in BigQuery directly from the notebook, streamlining the workflow.
Other options and why they are not the best fit:
B. Managed notebook: While managed notebooks offer an easier setup, they might have limited customization options, potentially hindering your ability to install specific libraries or tools.
C. Dataproc Hub: Dataproc Hub focuses on running large-scale distributed workloads, and it might be overkill for your scenario involving exploratory analysis and experimentation with different algorithms. Additionally, it could incur higher costs compared to a user-managed notebook.
D. Dataproc cluster with spark-bigquery-connector: Similar to option C, using a Dataproc cluster with the spark-bigquery-connector would be more complex and potentially more expensive than using %%bigquery magic commands within a user-managed notebook for accessing BigQuery data.
Reference: https://cloud.google.com/vertex-ai/docs/workbench/instances/bigquery https://cloud.google.com/vertex-ai-notebooks
You trained a model, packaged it with a custom Docker container for serving, and deployed it to Vertex Al Model Registry. When you submit a batch prediction job, it fails with this error "Error model server never became ready Please validate that your model file or container configuration are valid. There are no additional errors in the logs
What should you do?
- A . Add a logging configuration to your application to emit logs to Cloud Logging.
- B . Change the HTTP port in your model’s configuration to the default value of 8080
- C . Change the health Route value in your models configuration to /heal thcheck.
- D . Pull the Docker image locally and use the decker run command to launch it locally. Use the docker logs command to explore the error logs.
B
Explanation:
When you deploy a custom container to Vertex AI Model Registry, you need to follow some requirements for the container configuration. One of these requirements is to use the HTTP port 8080 for serving predictions. If you use a different port, the model server might not be able to communicate with Vertex AI and cause the error “Error model server never became ready”. To fix this error, you need to change the HTTP port in your model’s configuration to the default value of 8080 and redeploy the container.
Reference: Custom container requirements documentation
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
You are building a MLOps platform to automate your company’s ML experiments and model retraining. You need to organize the artifacts for dozens of pipelines.
How should you store the pipelines’ artifacts’?
- A . Store parameters in Cloud SQL and store the models’ source code and binaries in GitHub
- B . Store parameters in Cloud SQL store the models’ source code in GitHub, and store the models’ binaries in Cloud Storage.
- C . Store parameters in Vertex ML Metadata store the models’ source code in GitHub and store the models’ binaries in Cloud Storage.
- D . Store parameters in Vertex ML Metadata and store the models source code and binaries in GitHub.
C
Explanation:
To organize the artifacts for dozens of pipelines, you should store the parameters in Vertex ML Metadata, store the models’ source code in GitHub, and store the models’ binaries in Cloud Storage.
This option has the following advantages:
Vertex ML Metadata is a service that helps you track and manage the metadata of your ML workflows, such as datasets, models, metrics, and parameters1. It can also help you with data lineage, model versioning, and model performance monitoring2.
GitHub is a popular platform for hosting and collaborating on code repositories. It can help you manage the source code of your models, as well as the configuration files, scripts, and notebooks that are part of your ML pipelines3.
Cloud Storage is a scalable and durable object storage service that can store any type of data, including model binaries4. It can also integrate with other services, such as Vertex AI, Cloud Functions, and Cloud Run, to enable easy deployment and serving of your models5.
Reference:
1: Introduction to Vertex ML Metadata | Vertex AI | Google Cloud
2: Manage metadata for ML workflows | Vertex AI | Google Cloud
3: GitHub – Where the world builds software
4: Cloud Storage | Google Cloud
5: Deploying models | Vertex AI | Google Cloud