
Google Professional Machine Learning Engineer Practice Exams
Last updated on Oct 10,2026- Exam Code: Professional Machine Learning Engineer
- Exam Name: Google Professional Machine Learning Engineer
- Certification Provider: Google
- Latest update: Oct 10,2026
You work as an ML researcher at an investment bank and are experimenting with the Gemini large language model (LLM). You plan to deploy the model for an internal use case and need full control of the model’s underlying infrastructure while minimizing inference time.
Which serving configuration should you use for this task?
- A . Deploy the model on a Vertex AI endpoint using one-click deployment in Model Garden.
- B . Deploy the model on a Google Kubernetes Engine (GKE) cluster manually by creating a custom YAML manifest.
- C . Deploy the model on a Vertex AI endpoint manually by creating a custom inference container.
- D . Deploy the model on a Google Kubernetes Engine (GKE) cluster using the deployment options in Model Garden.
B
Explanation:
Deploying the model on GKE with a custom YAML manifest allows maximum control over infrastructure and latency, aligning with the need for low inference time and internal model use. Vertex AI’s one-click deployment (Option A) limits control, and deploying on Vertex AI (Option C) doesn’t allow for as much customization as a GKE setup.
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run.
How should you set up your experiments?
A)
B)
C)
D)
- A . Option A
- B . Option B
- C . Option C
- D . Option D
A
Explanation:
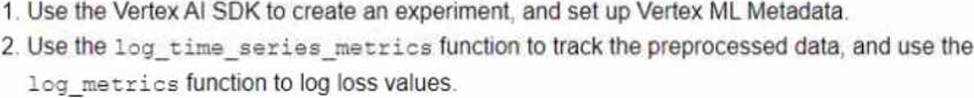
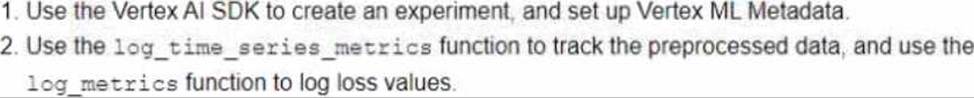
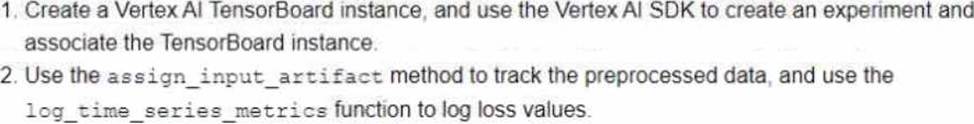
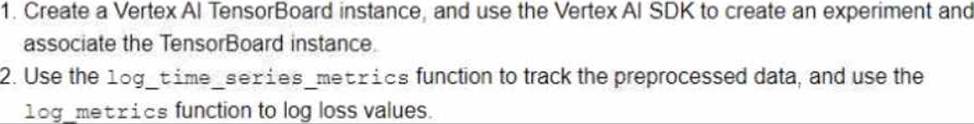
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem. You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run. The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook.
Reference: Vertex AI Workbench documentation
Vertex AI TensorBoard documentation
Vertex AI SDK documentation
log_time_series_metrics function documentation
log_metrics function documentation
[Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run.
How should you set up your experiments?
A)
B)
C)
D)
- A . Option A
- B . Option B
- C . Option C
- D . Option D
A
Explanation:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem. You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run. The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook.
Reference: Vertex AI Workbench documentation
Vertex AI TensorBoard documentation
Vertex AI SDK documentation
log_time_series_metrics function documentation
log_metrics function documentation
[Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
You need to train a regression model based on a dataset containing 50,000 records that is stored in BigQuery. The data includes a total of 20 categorical and numerical features with a target variable that can include negative values. You need to minimize effort and training time while maximizing model performance.
What approach should you take to train this regression model?
- A . Create a custom TensorFlow DNN model.
- B . Use BQML XGBoost regression to train the model
- C . Use AutoML Tables to train the model without early stopping.
- D . Use AutoML Tables to train the model with RMSLE as the optimization objective
D
Explanation:
AutoML Tables is a service that allows you to automatically build, analyze, and deploy machine learning models on tabular data. It is suitable for large-scale regression and classification problems, and it supports various optimization objectives, data splitting methods, and hyperparameter tuning algorithms. AutoML Tables can handle both categorical and numerical features, and it can also handle missing values and outliers. AutoML Tables is a good choice for this problem because it minimizes the effort and training time required to train a regression model, while maximizing the model performance.
RMSLE stands for Root Mean Squared Logarithmic Error, and it is a metric that measures the average difference between the logarithm of the predicted values and the logarithm of the actual values. RMSLE is useful for regression problems where the target variable can include negative values, and where large differences between small values are more important than large differences between large values. For example, RMSLE penalizes underestimating a value of 10 by 2 more than overestimating a value of 1000 by 20. RMSLE is a good optimization objective for this problem because it can handle negative values in the target variable, and it can reduce the impact of outliers and large errors.
For more information about AutoML Tables and RMSLE, see the following references:
AutoML Tables: end-to-end workflows on AI Platform Pipelines Predict workload failures before they happen with AutoML Tables How to Calculate RMSE in R
You work for a company that is developing an application to help users with meal planning You want to use machine learning to scan a corpus of recipes and extract each ingredient (e g carrot, rice pasta) and each kitchen cookware (e.g. bowl, pot spoon) mentioned Each recipe is saved in an unstructured text file.
What should you do?
- A . Create a text dataset on Vertex Al for entity extraction Create two entities called ingredient" and cookware" and label at least 200 examples of each entity Train an AutoML entity extraction model to extract occurrences of these entity types Evaluate performance on a holdout dataset.
- B . Create a multi-label text classification dataset on Vertex Al Create a test dataset and label each recipe that corresponds to its ingredients and cookware Train a multi-class classification model Evaluate the model’s performance on a holdout dataset.
- C . Use the Entity Analysis method of the Natural Language API to extract the ingredients and cookware from each recipe Evaluate the model’s performance on a prelabeled dataset.
- D . Create a text dataset on Vertex Al for entity extraction Create as many entities as there are different ingredients and cookware Train an AutoML entity extraction model to extract those entities Evaluate the models performance on a holdout dataset.
A
Explanation:
Entity extraction is a natural language processing (NLP) task that involves identifying and extracting specific types of information from text, such as names, dates, locations, etc. Entity extraction can help you analyze a corpus of recipes and extract each ingredient and cookware mentioned in them. Vertex AI is a unified platform for building and managing machine learning solutions on Google Cloud. It provides a service for AutoML entity extraction, which allows you to create and train custom entity extraction models without writing any code. You can use Vertex AI to create a text dataset for entity extraction, and label your data with two entities: “ingredient” and “cookware”. You need to label at least 200 examples of each entity type to train an AutoML entity extraction model. You can also use a holdout dataset to evaluate the performance of your model, such as precision, recall, and F1-score. This solution can help you build a machine learning model to scan a corpus of recipes and extract each ingredient and cookware mentioned in them, and use the results to help users with meal planning.
Reference: AutoML Entity Extraction | Vertex AI
Preparing data for AutoML Entity Extraction | Vertex AI
Your company needs to generate product summaries for vendors. You evaluated a foundation model from Model Garden for text summarization but found that the summaries do not align with your company’s brand voice.
How should you improve this LLM-based summarization model to better meet your business objectives?
- A . Increase the model’s temperature parameter.
- B . Fine-tune the model using a company-specific dataset.
- C . Tune the token output limit in the response.
- D . Replace the pre-trained model with another model in Model Garden.
B
Explanation:
Fine-tuning the model with a company-specific dataset aligns the model outputs with the brand voice, making it better suited for the company’s objectives. Adjusting the temperature (Option A) affects randomness rather than content style, and changing token limits (Option C) does not impact tone. Replacing the model (Option D) is inefficient without guarantees of better alignment.