
Databricks Databricks Machine Learning Professional Practice Exams
Last updated on Oct 21,2026- Exam Code: Databricks Machine Learning Professional
- Exam Name: Databricks Certified Machine Learning Professional
- Certification Provider: Databricks
- Latest update: Oct 21,2026
A machine learning engineer is using the following code block as part of a batch deployment pipeline:
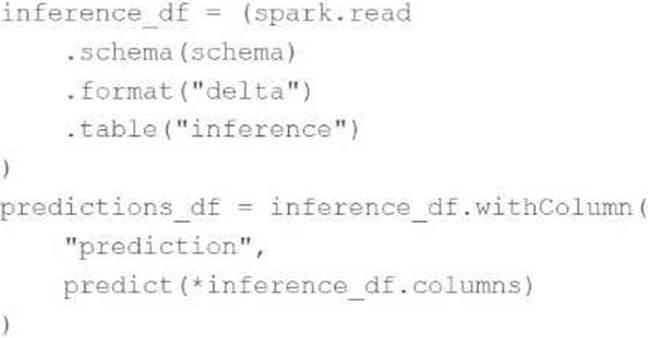
Which of the following changes needs to be made so this code block will work when the inference table is a stream source?
- A . Replace "inference" with the path to the location of the Delta table
- B . Replace schema(schema) with option("maxFilesPerTriqqer", 1}
- C . Replace spark.read with spark.readStream
- D . Replace formatfdelta") with format("stream")
- E . Replace predict with a stream-friendly prediction function
A machine learning engineer needs to deliver predictions of a machine learning model in real-time. However, the feature values needed for computing the predictions are available one week before the
query time.
Which of the following is a benefit of using a batch serving deployment in this scenario rather than a real-time serving deployment where predictions are computed at query time?
- A . Batch serving has built-in capabilities in Databricks Machine Learning
- B . There is no advantage to using batch serving deployments over real-time serving deployments
- C . Computing predictions in real-time provides more up-to-date results
- D . Testing is not possible in real-time serving deployments
- E . Querying stored predictions can be faster than computing predictions in real-time
A data scientist has developed a scikit-learn model sklearn_model and they want to log the model using MLflow.
They write the following incomplete code block:
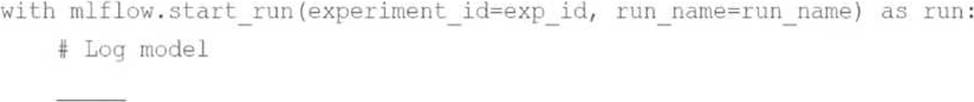
Which of the following lines of code can be used to fill in the blank so the code block can successfully complete the task?
- A . mlflow.spark.track_model(sklearn_model, "model")
- B . mlflow.sklearn.log_model(sklearn_model, "model")
- C . mlflow.spark.log_model(sklearn_model, "model")
- D . mlflow.sklearn.load_model("model")
- E . mlflow.sklearn.track_model(sklearn_model, "model")
A machine learning engineer is migrating a machine learning pipeline to use Databricks Machine Learning. They have programmatically identified the best run from an MLflow Experiment and stored its URI in the model_uri variable and its Run ID in the run_id variable. They have also determined that the model was logged with the name "model". Now, the machine learning engineer wants to register that model in the MLflow Model Registry with the name "best_model".
Which of the following lines of code can they use to register the model to the MLflow Model Registry?
- A . mlflow.register_model(model_uri, "best_model")
- B . mlflow.register_model(run_id, "best_model")
- C . mlflow.register_model(f"runs:/{run_id}/best_model", "model")
- D . mlflow.register_model(model_uri, "model")
- E . mlflow.register_model(f"runs:/{run_id}/model")
Which of the following Databricks-managed MLflow capabilities is a centralized model store?
- A . Models
- B . Model Registry
- C . Model Serving
- D . Feature Store
- E . Experiments
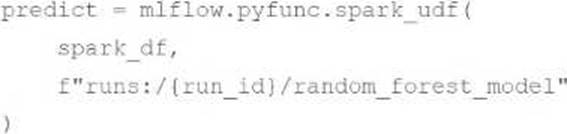
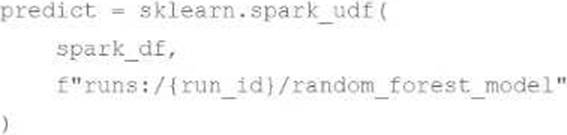
A machine learning engineer has developed a random forest model using scikit-learn, logged the model using MLflow as random_forest_model, and stored its run ID in the run_id Python variable.
They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df.
Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
A)
B) It is not possible to deploy a scikit-learn model on a Spark DataFrame.
C)
D)
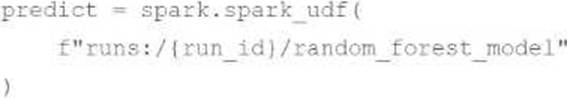
E)
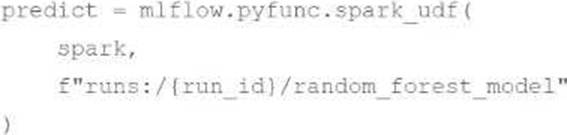
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
Which of the following is a benefit of logging a model signature with an MLflow model?
- A . The model will have a unique identifier in the MLflow experiment
- B . The schema of input data can be validated when serving models
- C . The model can be deployed using real-time serving tools
- D . The model will be secured by the user that developed it
- E . The schema of input data will be converted to match the signature
Which of the following is an advantage of using the python_function(pyfunc) model flavor over the built-in library-specific model flavors?
- A . python_function provides no benefits over the built-in library-specific model flavors
- B . python_function can be used to deploy models in a parallelizable fashion
- C . python_function can be used to deploy models without worrying about which library was used to create the model
- D . python_function can be used to store models in an MLmodel file
- E . python_function can be used to deploy models without worrying about whether they are deployed in batch, streaming, or real-time environments
Which of the following statements describes streaming with Spark as a model deployment strategy?
- A . The inference of batch processed records as soon as a trigger is hit
- B . The inference of all types of records in real-time
- C . The inference of batch processed records as soon as a Spark job is run
- D . The inference of incrementally processed records as soon as trigger is hit
- E . The inference of incrementally processed records as soon as a Spark job is run