
Databricks Databricks Certified Data Engineer Professional Practice Exams
Last updated on Oct 22,2026- Exam Code: Databricks Certified Data Engineer Professional
- Exam Name: Databricks Certified Data Engineer Professional Exam
- Certification Provider: Databricks
- Latest update: Oct 22,2026
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
- A . The job_id is returned in this field.
- B . The job_id and number of times the job has been are concatenated and returned.
- C . The number of times the job definition has been run in the workspace.
- D . The globally unique ID of the newly triggered run.
Which statement characterizes the general programming model used by Spark Structured Streaming?
- A . Structured Streaming leverages the parallel processing of GPUs to achieve highly parallel data throughput.
- B . Structured Streaming is implemented as a messaging bus and is derived from Apache Kafka.
- C . Structured Streaming uses specialized hardware and I/O streams to achieve sub-second latency for data transfer.
- D . Structured Streaming models new data arriving in a data stream as new rows appended to an unbounded table.
- E . Structured Streaming relies on a distributed network of nodes that hold incremental state values for cached stages.
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG
There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion. However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A . All data should be deleted biweekly; Delta Lake’s time travel functionality should be leveraged to maintain a history of non-PII information.
- B . Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
- C . Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
- D . Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
- E . Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
When evaluating the Ganglia Metrics for a given cluster with 3 executor nodes, which indicator would signal proper utilization of the VM’s resources?
- A . The five Minute Load Average remains consistent/flat
- B . Bytes Received never exceeds 80 million bytes per second
- C . Network I/O never spikes
- D . Total Disk Space remains constant
- E . CPU Utilization is around 75%
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate
table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
- A . Send all users notice that the schema for the table will be changing; include in the communication the logic necessary to revert the new table schema to match historic queries.
- B . Configure a new table with all the requisite fields and new names and use this as the source for the customer-facing application; create a view that maintains the original data schema and table name by aliasing select fields from the new table.
- C . Create a new table with the required schema and new fields and use Delta Lake’s deep clone functionality to sync up changes committed to one table to the corresponding table.
- D . Replace the current table definition with a logical view defined with the query logic currently writing the aggregate table; create a new table to power the customer-facing application.
- E . Add a table comment warning all users that the table schema and field names will be changing on a given date; overwrite the table in place to the specifications of the customer-facing application.
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM, 160 total cores and only one Executor per VM.
Given a job with at least one wide transformation, which of the following cluster configurations will result in maximum performance?
- A . • Total VMs; 1
• 400 GB per Executor
• 160 Cores / Executor - B . • Total VMs: 8
• 50 GB per Executor
• 20 Cores / Executor C.
• Total VMs: 4
• 100 GB per Executor
• 40 Cores/Executor D.
• Total VMs:2
• 200 GB per Executor
• 80 Cores / Executor
A developer has successfully configured credential for Databricks Repos and cloned a remote Git repository. Hey don not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace.
Use Response to pull changes from the remote Git repository commit and push changes to a branch that appeared as a changes were pulled.
- A . Use Repos to merge all differences and make a pull request back to the remote repository.
- B . Use repos to merge all difference and make a pull request back to the remote repository.
- C . Use Repos to create a new branch commit all changes and push changes to the remote Git repertory.
- D . Use repos to create a fork of the remote repository commit all changes and make a pull request on the source repository
The data governance team is reviewing code used for deleting records for compliance with GDPR.
They note the following logic is used to delete records from the Delta Lake table named users.
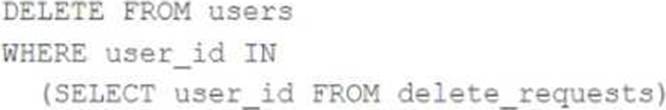
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A . Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- B . No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- C . Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- D . No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- E . No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
Which statement regarding stream-static joins and static Delta tables is correct?
- A . Each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch.
- B . Each microbatch of a stream-static join will use the most recent version of the static Delta table as of the job’s initialization.
- C . The checkpoint directory will be used to track state information for the unique keys present in the join.
- D . Stream-static joins cannot use static Delta tables because of consistency issues.
- E . The checkpoint directory will be used to track updates to the static Delta table.
Which statement describes the default execution mode for Databricks Auto Loader?
- A . New files are identified by listing the input directory; new files are incrementally and idempotently
loaded into the target Delta Lake table. - B . Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C . Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- D . New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.