
Databricks Databricks Certified Data Engineer Associate Practice Exams
Last updated on Oct 22,2026- Exam Code: Databricks Certified Data Engineer Associate
- Exam Name: Databricks Certified Data Engineer Associate Exam
- Certification Provider: Databricks
- Latest update: Oct 22,2026
A data engineer is designing a data pipeline. The source system generates files in a shared directory that is also used by other processes. As a result, the files should be kept as is and will accumulate in the directory. The data engineer needs to identify which files are new since the previous run in the pipeline, and set up the pipeline to only ingest those new files with each run.
Which of the following tools can the data engineer use to solve this problem?
- A . Unity Catalog
- B . Delta Lake
- C . Databricks SQL
- D . Data Explorer
- E . Auto Loader
Which of the following Structured Streaming queries is performing a hop from a Silver table to a Gold table?
A)
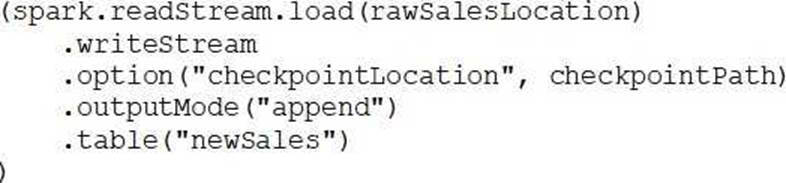
B)
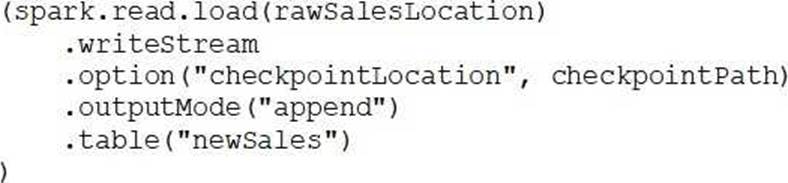
C)
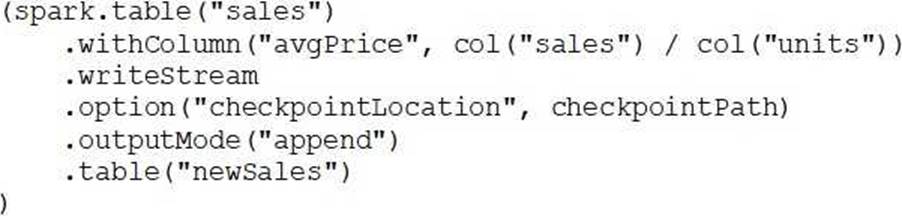
D)
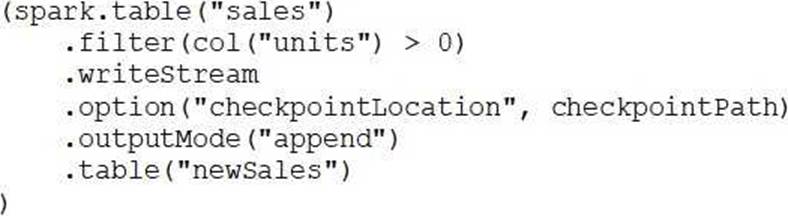
E)
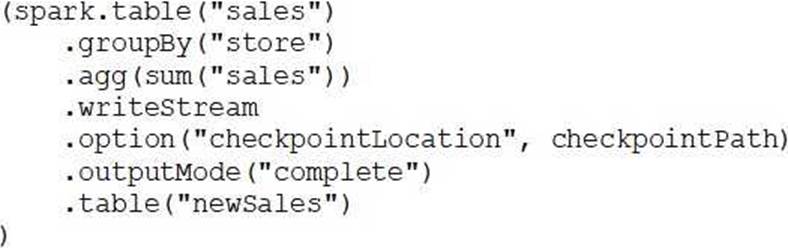
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
A data engineer has a single-task Job that runs each morning before they begin working. After identifying an upstream data issue, they need to set up another task to run a new notebook prior to the original task.
Which of the following approaches can the data engineer use to set up the new task?
- A . They can clone the existing task in the existing Job and update it to run the new notebook.
- B . They can create a new task in the existing Job and then add it as a dependency of the original task.
- C . They can create a new task in the existing Job and then add the original task as a dependency of the new task.
- D . They can create a new job from scratch and add both tasks to run concurrently.
- E . They can clone the existing task to a new Job and then edit it to run the new notebook.
A data engineer has three tables in a Delta Live Tables (DLT) pipeline. They have configured the pipeline to drop invalid records at each table. They notice that some data is being dropped due to quality concerns at some point in the DLT pipeline. They would like to determine at which table in their pipeline the data is being dropped.
Which of the following approaches can the data engineer take to identify the table that is dropping the records?
- A . They can set up separate expectations for each table when developing their DLT pipeline.
- B . They cannot determine which table is dropping the records.
- C . They can set up DLT to notify them via email when records are dropped.
- D . They can navigate to the DLT pipeline page, click on each table, and view the data quality statistics.
- E . They can navigate to the DLT pipeline page, click on the “Error” button, and review the present errors.
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table:
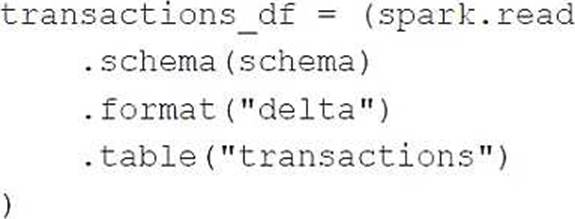
Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?
- A . Replace predict with a stream-friendly prediction function
- B . Replace schema(schema) with option ("maxFilesPerTrigger", 1)
- C . Replace "transactions" with the path to the location of the Delta table
- D . Replace format("delta") with format("stream")
- E . Replace spark.read with spark.readStream
Which of the following statements regarding the relationship between Silver tables and Bronze tables is always true?
- A . Silver tables contain a less refined, less clean view of data than Bronze data.
- B . Silver tables contain aggregates while Bronze data is unaggregated.
- C . Silver tables contain more data than Bronze tables.
- D . Silver tables contain a more refined and cleaner view of data than Bronze tables.
- E . Silver tables contain less data than Bronze tables.
Which of the following is hosted completely in the control plane of the classic Databricks architecture?
- A . Worker node
- B . JDBC data source
- C . Databricks web application
- D . Databricks Filesystem
- E . Driver node
Which of the following is stored in the Databricks customer’s cloud account?
- A . Databricks web application
- B . Cluster management metadata
- C . Repos
- D . Data
- E . Notebooks
A data engineer wants to create a relational object by pulling data from two tables. The relational object does not need to be used by other data engineers in other sessions. In order to save on storage costs, the data engineer wants to avoid copying and storing physical data.
Which of the following relational objects should the data engineer create?
- A . Spark SQL Table
- B . View
- C . Database
- D . Temporary view
- E . Delta Table
A data engineer runs a statement every day to copy the previous day’s sales into the table transactions. Each day’s sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task:
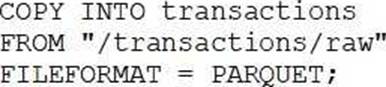
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
- A . The format of the files to be copied were not included with the FORMAT_OPTIONS keyword.
- B . The names of the files to be copied were not included with the FILES keyword.
- C . The previous day’s file has already been copied into the table.
- D . The PARQUET file format does not support COPY INTO.
- E . The COPY INTO statement requires the table to be refreshed to view the copied rows.