
Databricks Databricks Certified Data Engineer Associate Practice Exams
Last updated on Oct 22,2026- Exam Code: Databricks Certified Data Engineer Associate
- Exam Name: Databricks Certified Data Engineer Associate Exam
- Certification Provider: Databricks
- Latest update: Oct 22,2026
What is stored in a Databricks customer’s cloud account?
- A . Data
- B . Cluster management metadata
- C . Databricks web application
- D . Notebooks
A data analyst has created a Delta table sales that is used by the entire data analysis team. They want help from the data engineering team to implement a series of tests to ensure the data is clean. However, the data engineering team uses Python for its tests rather than SQL.
Which of the following commands could the data engineering team use to access sales in PySpark?
- A . SELECT * FROM sales
- B . There is no way to share data between PySpark and SQL.
- C . spark.sql("sales")
- D . spark.delta.table("sales")
- E . spark.table("sales")
Which of the following code blocks will remove the rows where the value in column age is greater than 25 from the existing Delta table my_table and save the updated table?
- A . SELECT * FROM my_table WHERE age > 25;
- B . UPDATE my_table WHERE age > 25;
- C . DELETE FROM my_table WHERE age > 25;
- D . UPDATE my_table WHERE age <= 25;
- E . DELETE FROM my_table WHERE age <= 25;
A data engineer and data analyst are working together on a data pipeline. The data engineer is working on the raw, bronze, and silver layers of the pipeline using Python, and the data analyst is working on the gold layer of the pipeline using SQL The raw source of the pipeline is a streaming input. They now want to migrate their pipeline to use Delta Live Tables.
Which change will need to be made to the pipeline when migrating to Delta Live Tables?
- A . The pipeline can have different notebook sources in SQL & Python.
- B . The pipeline will need to be written entirely in SQL.
- C . The pipeline will need to be written entirely in Python.
- D . The pipeline will need to use a batch source in place of a streaming source.
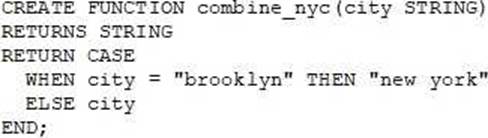
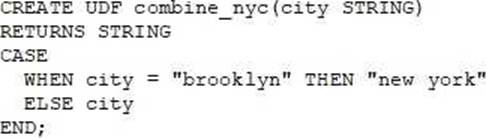
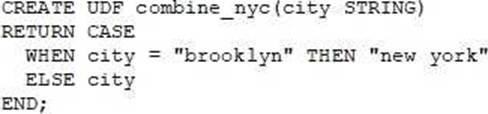
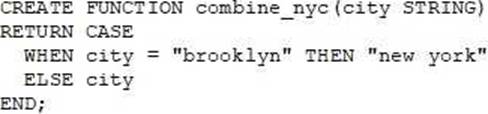
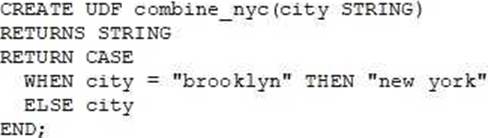
A data engineer needs to apply custom logic to string column city in table stores for a specific use case. In order to apply this custom logic at scale, the data engineer wants to create a SQL user-defined function (UDF).
Which of the following code blocks creates this SQL UDF?
A)
B)
C)
D)
E)
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
In which of the following scenarios should a data engineer select a Task in the Depends On field of a new Databricks Job Task?
- A . When another task needs to be replaced by the new task
- B . When another task needs to fail before the new task begins
- C . When another task has the same dependency libraries as the new task
- D . When another task needs to use as little compute resources as possible
- E . When another task needs to successfully complete before the new task begins
Which of the following describes when to use the CREATE STREAMING LIVE TABLE (formerly CREATE INCREMENTAL LIVE TABLE) syntax over the CREATE LIVE TABLE syntax when creating Delta Live Tables (DLT) tables using SQL?
- A . CREATE STREAMING LIVE TABLE should be used when the subsequent step in the DLT pipeline is static.
- B . CREATE STREAMING LIVE TABLE should be used when data needs to be processed incrementally.
- C . CREATE STREAMING LIVE TABLE is redundant for DLT and it does not need to be used.
- D . CREATE STREAMING LIVE TABLE should be used when data needs to be processed through complicated aggregations.
- E . CREATE STREAMING LIVE TABLE should be used when the previous step in the DLT pipeline is static.
A data engineer is attempting to drop a Spark SQL table my_table and runs the following command:
DROP TABLE IF EXISTS my_table;
After running this command, the engineer notices that the data files and metadata files have been deleted from the file system.
Which of the following describes why all of these files were deleted?
- A . The table was managed
- B . The table’s data was smaller than 10 GB
- C . The table’s data was larger than 10 GB
- D . The table was external
- E . The table did not have a location
Which of the following describes a scenario in which a data team will want to utilize cluster pools?
- A . An automated report needs to be refreshed as quickly as possible.
- B . An automated report needs to be made reproducible.
- C . An automated report needs to be tested to identify errors.
- D . An automated report needs to be version-controlled across multiple collaborators.
- E . An automated report needs to be runnable by all stakeholders.
A data engineer wants to create a new table containing the names of customers that live in France.
They have written the following command:
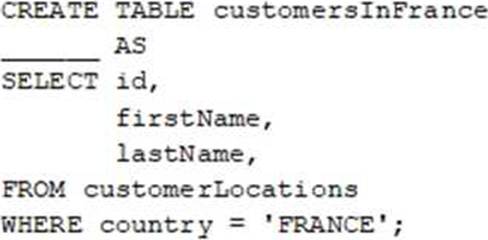
A senior data engineer mentions that it is organization policy to include a table property indicating that the new table includes personally identifiable information (PII).
Which of the following lines of code fills in the above blank to successfully complete the task?
- A . There is no way to indicate whether a table contains PII.
- B . "COMMENT PII"
- C . TBLPROPERTIES PII
- D . COMMENT "Contains PII"
- E . PII