
Databricks Databricks Certified Data Engineer Associate Practice Exams
Last updated on Oct 22,2026- Exam Code: Databricks Certified Data Engineer Associate
- Exam Name: Databricks Certified Data Engineer Associate Exam
- Certification Provider: Databricks
- Latest update: Oct 22,2026
A data engineer wants to create a new table containing the names of customers who live in France.
They have written the following command:
CREATE TABLE customersInFrance
_____ AS
SELECT id,
firstName,
lastName
FROM customerLocations
WHERE country = ’FRANCE’;
A senior data engineer mentions that it is organization policy to include a table property indicating that the new table includes personally identifiable information (Pll).
Which line of code fills in the above blank to successfully complete the task?
- A . COMMENT "Contains PIT
- B . 511
- C . "COMMENT PII"
- D . TBLPROPERTIES PII
Which of the following describes a scenario in which a data engineer will want to use a single-node cluster?
- A . When they are working interactively with a small amount of data
- B . When they are running automated reports to be refreshed as quickly as possible
- C . When they are working with SQL within Databricks SQL
- D . When they are concerned about the ability to automatically scale with larger data
- E . When they are manually running reports with a large amount of data
Which of the following describes the storage organization of a Delta table?
- A . Delta tables are stored in a single file that contains data, history, metadata, and other attributes.
- B . Delta tables store their data in a single file and all metadata in a collection of files in a separate location.
- C . Delta tables are stored in a collection of files that contain data, history, metadata, and other attributes.
- D . Delta tables are stored in a collection of files that contain only the data stored within the table.
- E . Delta tables are stored in a single file that contains only the data stored within the table.
Which Databricks component is essential for creating and managing machine learning workflows?
- A . Delta Lake
- B . Databricks SQL
- C . MLflow
- D . GraphFrames
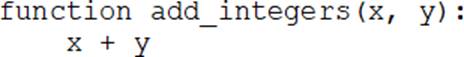
A data engineer that is new to using Python needs to create a Python function to add two integers together and return the sum?
Which of the following code blocks can the data engineer use to complete this task?
A)
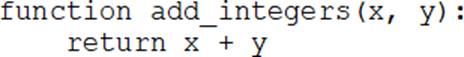
B)
C)
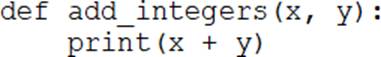
D)
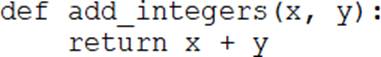
E)
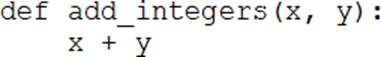
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
In order for Structured Streaming to reliably track the exact progress of the processing so that it can handle any kind of failure by restarting and/or reprocessing, which of the following two approaches is used by Spark to record the offset range of the data being processed in each trigger?
- A . Checkpointing and Write-ahead Logs
- B . Structured Streaming cannot record the offset range of the data being processed in each trigger.
- C . Replayable Sources and Idempotent Sinks
- D . Write-ahead Logs and Idempotent Sinks
- E . Checkpointing and Idempotent Sinks
A data engineer is maintaining a data pipeline. Upon data ingestion, the data engineer notices that the source data is starting to have a lower level of quality. The data engineer would like to automate the process of monitoring the quality level.
Which of the following tools can the data engineer use to solve this problem?
- A . Unity Catalog
- B . Data Explorer
- C . Delta Lake
- D . Delta Live Tables
- E . Auto Loader
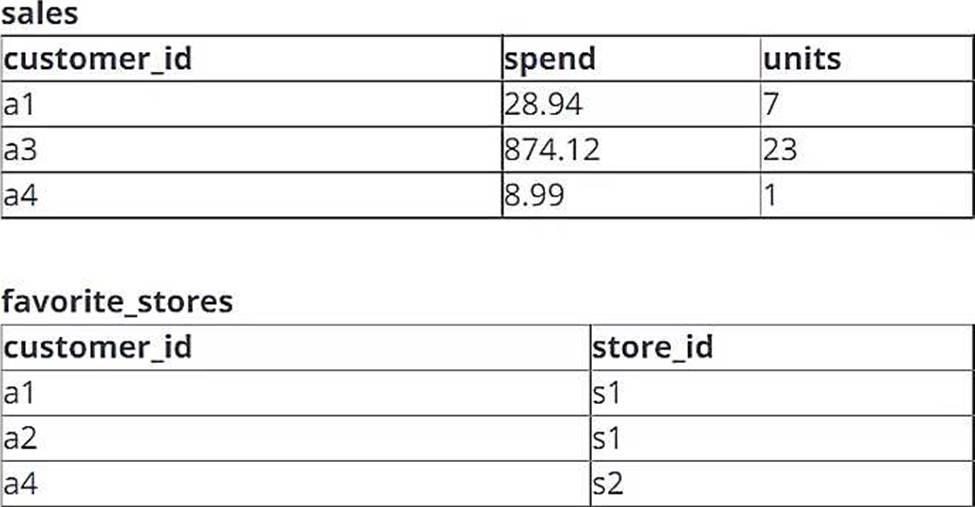
A data engineer is working with two tables. Each of these tables is displayed below in its entirety.
The data engineer runs the following query to join these tables together:
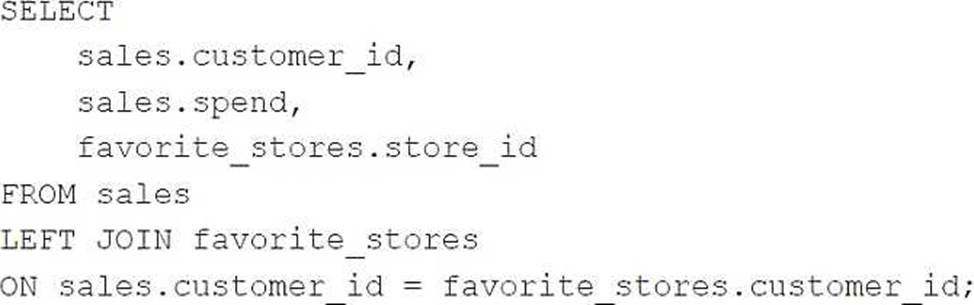
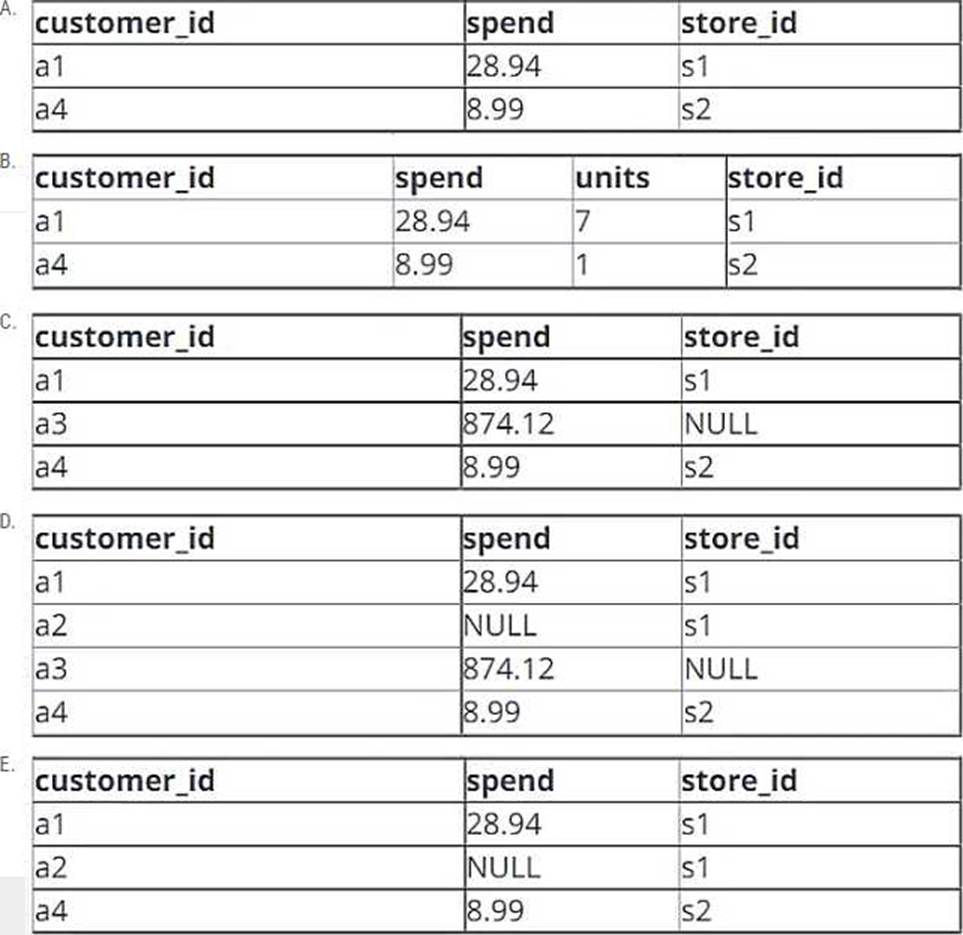
Which of the following will be returned by the above query?
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
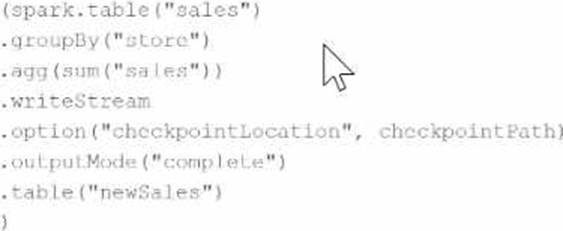
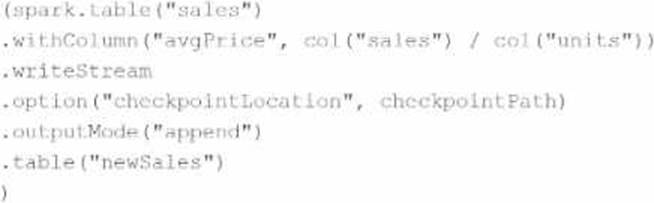
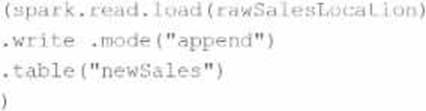
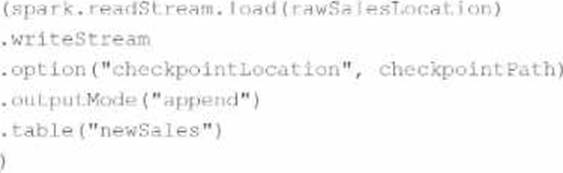
Which query is performing a streaming hop from raw data to a Bronze table?
A)
B)
C)
D)
- A . Option A
- B . Option B
- C . Option C
- D . Option D
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
- A . All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will persist to allow for additional testing.
- B . All datasets will be updated once and the pipeline will persist without any processing. The compute resources will persist but go unused.
- C . All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will be deployed for the update and terminated when the pipeline is stopped.
- D . All datasets will be updated once and the pipeline will shut down. The compute resources will be terminated.
- E . All datasets will be updated once and the pipeline will shut down. The compute resources will persist to allow for additional testing.