
Databricks Databricks Certified Data Analyst Associate Practice Exams
Last updated on Oct 21,2026- Exam Code: Databricks Certified Data Analyst Associate
- Exam Name: Databricks Certified Data Analyst Associate Exam
- Certification Provider: Databricks
- Latest update: Oct 21,2026
A data engineer is working with a nested array column products in table transactions. They want to expand the table so each unique item in products for each row has its own row where the transaction_id column is duplicated as necessary.
They are using the following incomplete command:
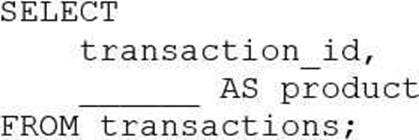
Which of the following lines of code can they use to fill in the blank in the above code block so that it successfully completes the task?
- A . array distinct(produces)
- B . explode(produces)
- C . reduce(produces)
- D . array(produces)
- E . flatten(produces)
B
The explode function is used to transform a DataFrame column of arrays or maps into multiple rows, duplicating the other column’s values. In this context, it will be used to expand the nested array column products in the transactions table so that each unique item in products for each row has its own row and the transaction_id column is duplicated as necessary.
Reference: Databricks Documentation
I also noticed that you sent me an image along with your message. The image shows a snippet of SQL code that is incomplete. It begins with “SELECT” indicating a query to retrieve data. “transaction_id,” suggests that transaction_id is one of the columns being selected. There are blanks indicated by underscores where certain parts of the SQL command should be, including what appears to be an alias for a column and part of the FROM clause. The query ends with “FROM transactions;” indicating data is being selected from a ‘transactions’ table.
If you are interested in learning more about Databricks Data Analyst Associate certification, you can check out the following resources:
Databricks Certified Data Analyst Associate: This is the official page for the certification exam, where
you can find the exam guide, registration details, and preparation tips.
Data Analysis With Databricks SQL: This is a self-paced course that covers the topics and skills required for the certification exam. You can access it for free on Databricks Academy.
Tips for the Databricks Certified Data Analyst Associate Certification: This is a blog post that provides some useful advice and study tips for passing the certification exam.
Databricks Certified Data Analyst Associate Certification: This is another blog post that gives an overview of the certification exam and its benefits.
A data scientist has asked a data analyst to create histograms for every continuous variable in a data set. The data analyst needs to identify which columns are continuous in the data set.
What describes a continuous variable?
- A . A quantitative variable that never stops changing
- B . A quantitative variable Chat can take on a finite or countably infinite set of values
- C . A quantitative variable that can take on an uncountable set of values
- D . A categorical variable in which the number of categories continues to increase over time
C
Explanation:
A continuous variable is a type of quantitative variable that can assume an infinite number of values within a given range. This means that between any two possible values, there can be an infinite number of other values. For example, variables such as height, weight, and temperature are continuous because they can be measured to any level of precision, and there are no gaps between possible values. This is in contrast to discrete variables, which can only take on specific, distinct values (e.g., the number of children in a family). Understanding the nature of continuous variables is crucial for data analysts, especially when selecting appropriate statistical methods and visualizations, such as histograms, to accurately represent and analyze the data.
A data analysis team is working with the table_bronze SQL table as a source for one of its most complex projects. A stakeholder of the project notices that some of the downstream data is duplicative. The analysis team identifies table_bronze as the source of the duplication.
Which of the following queries can be used to deduplicate the data from table_bronze and write it to a new table table_silver?
A) CREATE TABLE table_silver AS SELECT DISTINCT *
FROM table_bronze;
B) CREATE TABLE table_silver AS
INSERT *
FROM table_bronze;
C) CREATE TABLE table_silver AS
MERGE DEDUPLICATE *
FROM table_bronze;
D) INSERT INTO TABLE table_silver
SELECT * FROM table_bronze;
E) INSERT OVERWRITE TABLE table_silver
SELECT * FROM table_bronze;
- A . Option A
- B . Option B
- C . Option C
- D . Option D
- E . Option E
A
Explanation:
Option A uses the SELECT DISTINCT statement to remove duplicate rows from the table_bronze and create a new table table_silver with the deduplicated data. This is the correct way to deduplicate data using Spark SQL12. Option B simply inserts all the rows from table_bronze into table_silver, without removing any duplicates. Option C is not a valid syntax for Spark SQL, as there is no MERGE DEDUPLICATE statement. Option D appends all the rows from table_bronze into table_silver, without removing any duplicates. Option E overwrites the existing data in table_silver with the data
from table_bronze, without removing any duplicates.
Reference: Delete Duplicate using SPARK SQL, Spark SQL – How to Remove Duplicate Rows
Which location can be used to determine the owner of a managed table?
- A . Review the Owner field in the table page using Catalog Explorer
- B . Review the Owner field in the database page using Data Explorer
- C . Review the Owner field in the schema page using Data Explorer
- D . Review the Owner field in the table page using the SQL Editor
A
Explanation:
In Databricks, to determine the owner of a managed table, you can utilize the Catalog Explorer
feature. The steps are as follows:
Access Catalog Explorer:
In your Databricks workspace, click on the Catalog icon in the sidebar to open Catalog Explorer.
Navigate to the Table:
Within Catalog Explorer, browse through the catalog and schema to locate the specific managed
table whose ownership you wish to verify.
View Table Details:
Click on the table name to open its details page.
Identify the Owner:
On the table’s details page, review the Owner field, which displays the principal (user, service principal, or group) that owns the table.
This method provides a straightforward way to ascertain the ownership of managed tables within the Databricks environment. Understanding table ownership is essential for managing permissions and ensuring proper access control.
Reference: Manage Unity Catalog object ownership
Consider the following two statements:
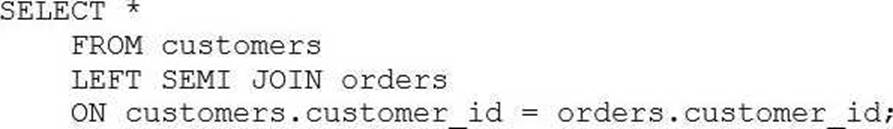
Statement 1:
Statement 2:
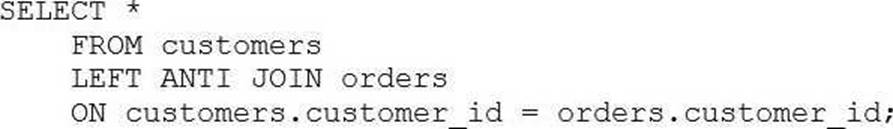
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
- A . The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.
- B . When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
- C . There is no difference between the result sets for both statements.
- D . Both statements will fail because Databricks SQL does not support those join types.
- E . When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
B
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id). Therefore, the result sets for the two statements will differ in the following way:
The first statement will return a subset of the customers table that contains only the customers who
have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table. The other options are not correct because:
A data analyst has been asked to provide a list of options on how to share a dashboard with a client. It is a security requirement that the client does not gain access to any other information, resources, or artifacts in the database.
Which of the following approaches cannot be used to share the dashboard and meet the security requirement?
- A . Download the Dashboard as a PDF and share it with the client.
- B . Set a refresh schedule for the dashboard and enter the client’s email address in the "Subscribers" box.
- C . Take a screenshot of the dashboard and share it with the client.
- D . Generate a Personal Access Token that is good for 1 day and share it with the client.
- E . Download a PNG file of the visualizations in the dashboard and share them with the client.
D
The approach that cannot be used to share the dashboard and meet the security requirement is D. Generating a Personal Access Token that is good for 1 day and sharing it with the client. This approach would give the client access to the Databricks workspace using the token owner’s identity and permissions, which could expose other information, resources, or artifacts in the database1.
The other approaches can be used to share the dashboard and meet the security requirement because:
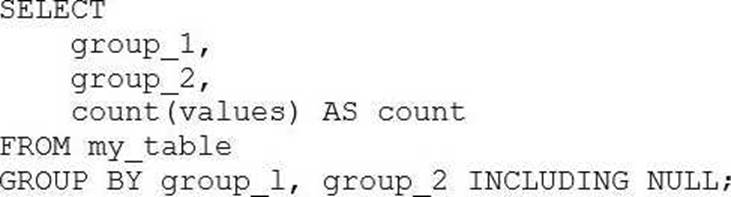
A data analyst is processing a complex aggregation on a table with zero null values and the query returns the following result:
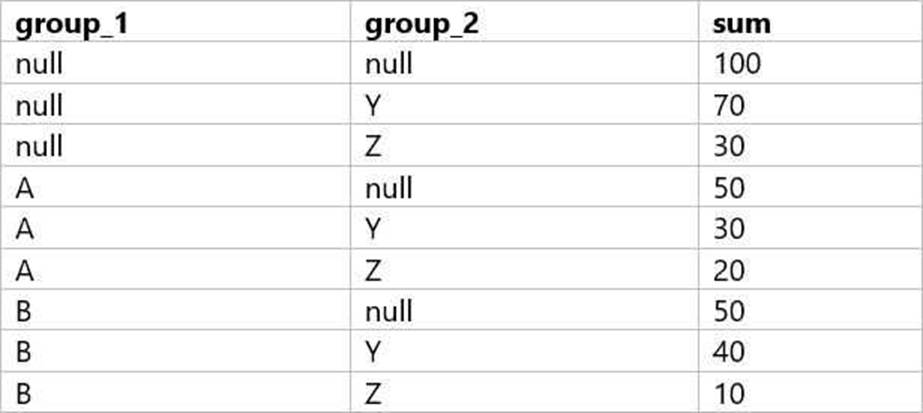
Which query did the analyst execute in order to get this result?
A)
B)
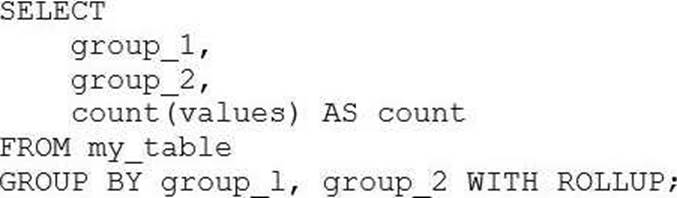
C)
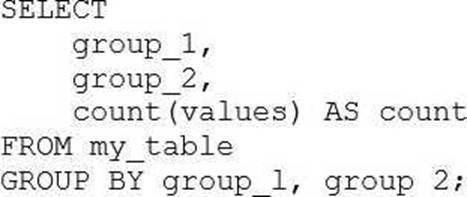
D)
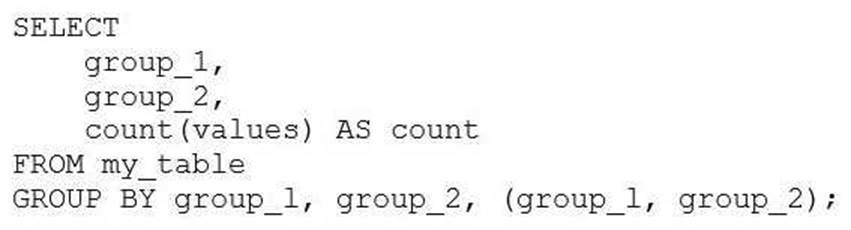
- A . Option A
- B . Option B
- C . Option C
- D . Option D
Which of the following approaches can be used to ingest data directly from cloud-based object storage?
- A . Create an external table while specifying the DBFS storage path to FROM
- B . Create an external table while specifying the DBFS storage path to PATH
- C . It is not possible to directly ingest data from cloud-based object storage
- D . Create an external table while specifying the object storage path to FROM
- E . Create an external table while specifying the object storage path to LOCATION
E
Explanation:
External tables are tables that are defined in the Databricks metastore using the information stored in a cloud object storage location. External tables do not manage the data, but provide a schema and a table name to query the data. To create an external table, you can use the CREATE EXTERNAL TABLE statement and specify the object storage path to the LOCATION clause. For example, to create an external table named ext_table on a Parquet file stored in S3, you can use the following statement: SQL
CREATE EXTERNAL TABLE ext_table (
col1 INT,
col2 STRING
)
STORED AS PARQUET
LOCATION ‘s3://bucket/path/file.parquet’
AI-generated code. Review and use carefully. More info on FAQ.
Reference: External tables
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every 10 minutes. A data analyst has created a dashboard based on this gold level data. The project stakeholders want to see the results in the dashboard updated within 10 minutes or less of new data becoming available within the gold-level tables.
What is the ability to ensure the streamed data is included in the dashboard at the standard requested by the project stakeholders?
- A . A refresh schedule with an interval of 10 minutes or less
- B . A refresh schedule with an always-on SQL Warehouse (formerly known as SQL Endpoint
- C . A refresh schedule with stakeholders included as subscribers
- D . A refresh schedule with a Structured Streaming cluster
A
Explanation:
In this scenario, the data engineering team has configured a Structured Streaming pipeline that updates the gold-level tables every 10 minutes. To ensure that the dashboard reflects the most recent data, it is essential to set the dashboard’s refresh schedule to an interval of 10 minutes or less. This synchronization ensures that stakeholders view the latest information shortly after it becomes available in the gold-level tables. Options B, C, and D do not directly address the requirement of aligning the dashboard refresh frequency with the data update interval.
A data analyst has been asked to configure an alert for a query that returns the income in the accounts_receivable table for a date range. The date range is configurable using a Date query parameter.
The Alert does not work.
Which of the following describes why the Alert does not work?
- A . Alerts don’t work with queries that access tables.
- B . Queries that return results based on dates cannot be used with Alerts.
- C . The wrong query parameter is being used. Alerts only work with Date and Time query parameters.
- D . Queries that use query parameters cannot be used with Alerts.
- E . The wrong query parameter is being used. Alerts only work with drogdown list query parameters, not dates.
D
Explanation:
The reason the alert is not functioning as expected is because Databricks SQL Alerts do not support query parameters. This limitation applies to all types of parameters, including date parameters.
Here’s why:
Alerts require static, deterministic query results so they can compare values consistently during scheduled executions.
When a query includes parameters (e.g., a date range parameter), its results may change based on user input or the default value set in the query editor.
However, Databricks SQL Alerts will always use the default value set for the parameter at the time the alert is created. This means the alert doesn’t dynamically adapt to new date ranges and will not reflect changes unless the query is manually updated.
As a result, if the business logic behind the alert depends on changing date ranges or any user input, the alert will not trigger correctly, or may never trigger at all.
Therefore, the correct explanation contradicts Option B, which is incorrect in saying that alerts
cannot work with date-based queries at all. In fact, they can―as long as the query is static (i.e.,
without parameters).
Reference: Databricks SQL Alerts Documentation
Databricks Knowledge: “You cannot use alerts with queries that contain parameters.”