
Databricks Databricks Certified Data Analyst Associate Practice Exams
Last updated on Oct 21,2026- Exam Code: Databricks Certified Data Analyst Associate
- Exam Name: Databricks Certified Data Analyst Associate Exam
- Certification Provider: Databricks
- Latest update: Oct 21,2026
Which of the following is a benefit of Databricks SQL using ANSI SQL as its standard SQL dialect?
- A . It has increased customization capabilities
- B . It is easy to migrate existing SQL queries to Databricks SQL
- C . It allows for the use of Photon’s computation optimizations
- D . It is more performant than other SQL dialects
- E . It is more compatible with Spark’s interpreters
B
Explanation:
Databricks SQL uses ANSI SQL as its standard SQL dialect, which means it follows the SQL specifications defined by the American National Standards Institute (ANSI). This makes it easier to migrate existing SQL queries from other data warehouses or platforms that also use ANSI SQL or a similar dialect, such as PostgreSQL, Oracle, or Teradata. By using ANSI SQL, Databricks SQL avoids surprises in behavior or unfamiliar syntax that may arise from using a non-standard SQL dialect, such as Spark SQL or Hive SQL12. Moreover, Databricks SQL also adds compatibility features to support common SQL constructs that are widely used in other data warehouses, such as QUALIFY, FILTER, and user-defined functions2.
Reference: ANSI compliance in Databricks Runtime, Evolution of the SQL language at Databricks: ANSI standard by default and easier migrations from data warehouses
Delta Lake stores table data as a series of data files, but it also stores a lot of other information.
Which of the following is stored alongside data files when using Delta Lake?
- A . None of these
- B . Table metadata, data summary visualizations, and owner account information
- C . Table metadata
- D . Data summary visualizations
- E . Owner account information
C
Delta Lake is a storage layer that enhances data lakes with features like ACID transactions, schema enforcement, and time travel. While it stores table data as Parquet files, Delta Lake also keeps a transaction log (stored in the _delta_log directory) that contains detailed table metadata.
This metadata includes:
Table schema
Partitioning information
Data file paths
Transactional operations like inserts, updates, and deletes
Commit history and version control
This metadata is critical for supporting Delta Lake’s advanced capabilities such as time travel and efficient query execution. Delta Lake does not store data summary visualizations or owner account information directly alongside the data files.
Reference: Delta Lake Table Features – Databricks Documentation
A data analyst wants to create a Databricks SQL dashboard with multiple data visualizations and multiple counters.
What must be completed before adding the data visualizations and counters to the dashboard?
- A . All data visualizations and counters must be created using Queries.
- B . A SQL warehouse (formerly known as SQL endpoint) must be turned on and selected.
- C . A markdown-based tile must be added to the top of the dashboard displaying the dashboard’s name.
- D . The dashboard owner must also be the owner of the queries, data visualizations, and counters.
A
Explanation:
In Databricks SQL, when creating a dashboard that includes multiple data visualizations and counters, it is imperative that each visualization and counter is based on a query. The process involves the following steps:
Develop Queries:
For each desired visualization or counter, write a SQL query that retrieves the necessary data.
Create Visualizations and Counters:
After executing each query, utilize the results to create corresponding visualizations or counters.
Databricks SQL offers a variety of visualization types to represent data effectively.
Assemble the Dashboard:
Add the created visualizations and counters to your dashboard, arranging them as needed to convey the desired insights.
By ensuring that all components of the dashboard are derived from queries, you maintain consistency, accuracy, and the ability to refresh data as needed. This approach also facilitates easier maintenance and updates to the dashboard elements.
Reference: Visualization in Databricks SQL
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every 10 minutes. A data analyst has created a dashboard based on this gold level data. The project stakeholders want to see the results in the dashboard updated within 10 minutes or less of new data becoming available within the gold-level tables.
What is the ability to ensure the streamed data is included in the dashboard at the standard requested by the project stakeholders?
- A . A refresh schedule with an interval of 10 minutes or less
- B . A refresh schedule with an always-on SQL Warehouse (formerly known as SQL Endpoint
- C . A refresh schedule with stakeholders included as subscribers
- D . A refresh schedule with a Structured Streaming cluster
A
Explanation:
In this scenario, the data engineering team has configured a Structured Streaming pipeline that updates the gold-level tables every 10 minutes. To ensure that the dashboard reflects the most recent data, it is essential to set the dashboard’s refresh schedule to an interval of 10 minutes or less. This synchronization ensures that stakeholders view the latest information shortly after it becomes available in the gold-level tables. Options B, C, and D do not directly address the requirement of aligning the dashboard refresh frequency with the data update interval.
Where in the Databricks SQL workspace can a data analyst configure a refresh schedule for a query when the query is not attached to a dashboard or alert?
- A . Data bxplorer
- B . The Visualization editor
- C . The Query Editor
- D . The Dashboard Editor
C
Explanation:
In Databricks SQL, to configure a refresh schedule for a query that is not attached to a dashboard or alert, a data analyst should use the Query Editor. Within the Query Editor, there is an option to set up scheduled executions for queries. This feature enables the query to run at specified intervals, ensuring that the results are updated regularly. By scheduling queries in this manner, analysts can automate data refreshes and maintain up-to-date query results without manual intervention.
Reference: Schedule a query – Databricks Documentation
The stakeholders.customers table has 15 columns and 3,000 rows of data.
The following command is run:
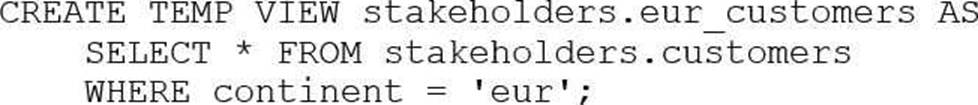
After running SELECT * FROM stakeholders.eur_customers, 15 rows are returned. After the command executes completely, the user logs out of Databricks.
After logging back in two days later, what is the status of the stakeholders.eur_customers view?
- A . The view remains available and SELECT * FROM stakeholders.eur_customers will execute correctly.
- B . The view has been dropped.
- C . The view is not available in the metastore, but the underlying data can be accessed with SELECT * FROM delta. `stakeholders.eur_customers`.
- D . The view remains available but attempting to SELECT from it results in an empty result set because data in views are automatically deleted after logging out.
- E . The view has been converted into a table.
A
Explanation:
In Databricks, a view is a saved SQL query definition that references existing tables or other views.
Once created, a view remains persisted in the metastore (such as Unity Catalog or Hive Metastore)
until it is explicitly dropped.
Key points:
Views do not store data themselves but reference data from underlying tables.
Logging out or being inactive does not delete or alter views.
Unless a user or admin explicitly drops the view or the underlying data/table is deleted, the view continues to function as expected.
Therefore, after logging back in―even days later―a user can still run SELECT * FROM stakeholders.eur_customers, and it will return the same data (provided the underlying table hasn’t changed).
Reference: Views – Databricks Documentation
A data analyst wants to create a dashboard with three main sections: Development, Testing, and Production. They want all three sections on the same dashboard, but they want to clearly designate the sections using text on the dashboard.
Which of the following tools can the data analyst use to designate the Development, Testing, and Production sections using text?
- A . Separate endpoints for each section
- B . Separate queries for each section
- C . Markdown-based text boxes
- D . Direct text written into the dashboard in editing mode
- E . Separate color palettes for each section
C
Explanation:
Markdown-based text boxes are useful as labels on a dashboard. They allow the data analyst to add text to a dashboard using the %md magic command in a notebook cell and then select the dashboard
icon in the cell actions menu. The text can be formatted using markdown syntax and can include headings, lists, links, images, and more. The text boxes can be resized and moved around on the dashboard using the float layout option.
Reference: Dashboards in notebooks, How to add text to a dashboard in Databricks
Data professionals with varying titles use the Databricks SQL service as the primary touchpoint with the Databricks Lakehouse Platform. However, some users will use other services like Databricks Machine Learning or Databricks Data Science and Engineering.
Which of the following roles uses Databricks SQL as a secondary service while primarily using one of the other services?
- A . Business analyst
- B . SQL analyst
- C . Data engineer
- D . Business intelligence analyst
- E . Data analyst
C
Explanation:
Data engineers are primarily responsible for building, managing, and optimizing data pipelines and architectures. They use Databricks Data Science and Engineering service to perform tasks such as data ingestion, transformation, quality, and governance. Data engineers may use Databricks SQL as a secondary service to query, analyze, and visualize data from the lakehouse, but this is not their main focus.
Reference: Databricks SQL overview, Databricks Data Science and Engineering overview, Data engineering with Databricks
An analyst writes a query that contains a query parameter. They then add an area chart visualization to the query. While adding the area chart visualization to a dashboard, the analyst chooses "Dashboard Parameter" for the query parameter associated with the area chart.
Which of the following statements is true?
- A . The area chart will use whatever is selected in the Dashboard Parameter while all or the other visualizations will remain changed regardless of their parameter use.
- B . The area chart will use whatever is selected in the Dashboard Parameter along with all of the other visualizations in the dashboard that use the same parameter.
- C . The area chart will use whatever value is chosen on the dashboard at the time the area chart is added to the dashboard.
- D . The area chart will use whatever value is input by the analyst when the visualization is added to the dashboard. The parameter cannot be changed by the user afterwards.
- E . The area chart will convert to a Dashboard Parameter.
B
A Dashboard Parameter is a parameter that is configured for one or more visualizations within a dashboard and appears at the top of the dashboard. The parameter values specified for a Dashboard Parameter apply to all visualizations reusing that particular Dashboard Parameter1. Therefore, if the analyst chooses “Dashboard Parameter” for the query parameter associated with the area chart, the area chart will use whatever is selected in the Dashboard Parameter along with all of the other visualizations in the dashboard that use the same parameter. This allows the user to filter the data across multiple visualizations using a single parameter widget2.
Reference: Databricks SQL dashboards, Query parameters